3986 stories
·
4 followers

New in Chrome 154: iframes that automatically resize themselves to their content

1 Share

~

Chrome 154 adds support for responsively-sized iframes, letting an <iframe> size itself based on the intrinsic size of its embedded document. This is perfect for seamlessly embedding third-party comment widgets, varying-height social media embeds, or any other type of embed that uses an <iframe>.

~

# The Code

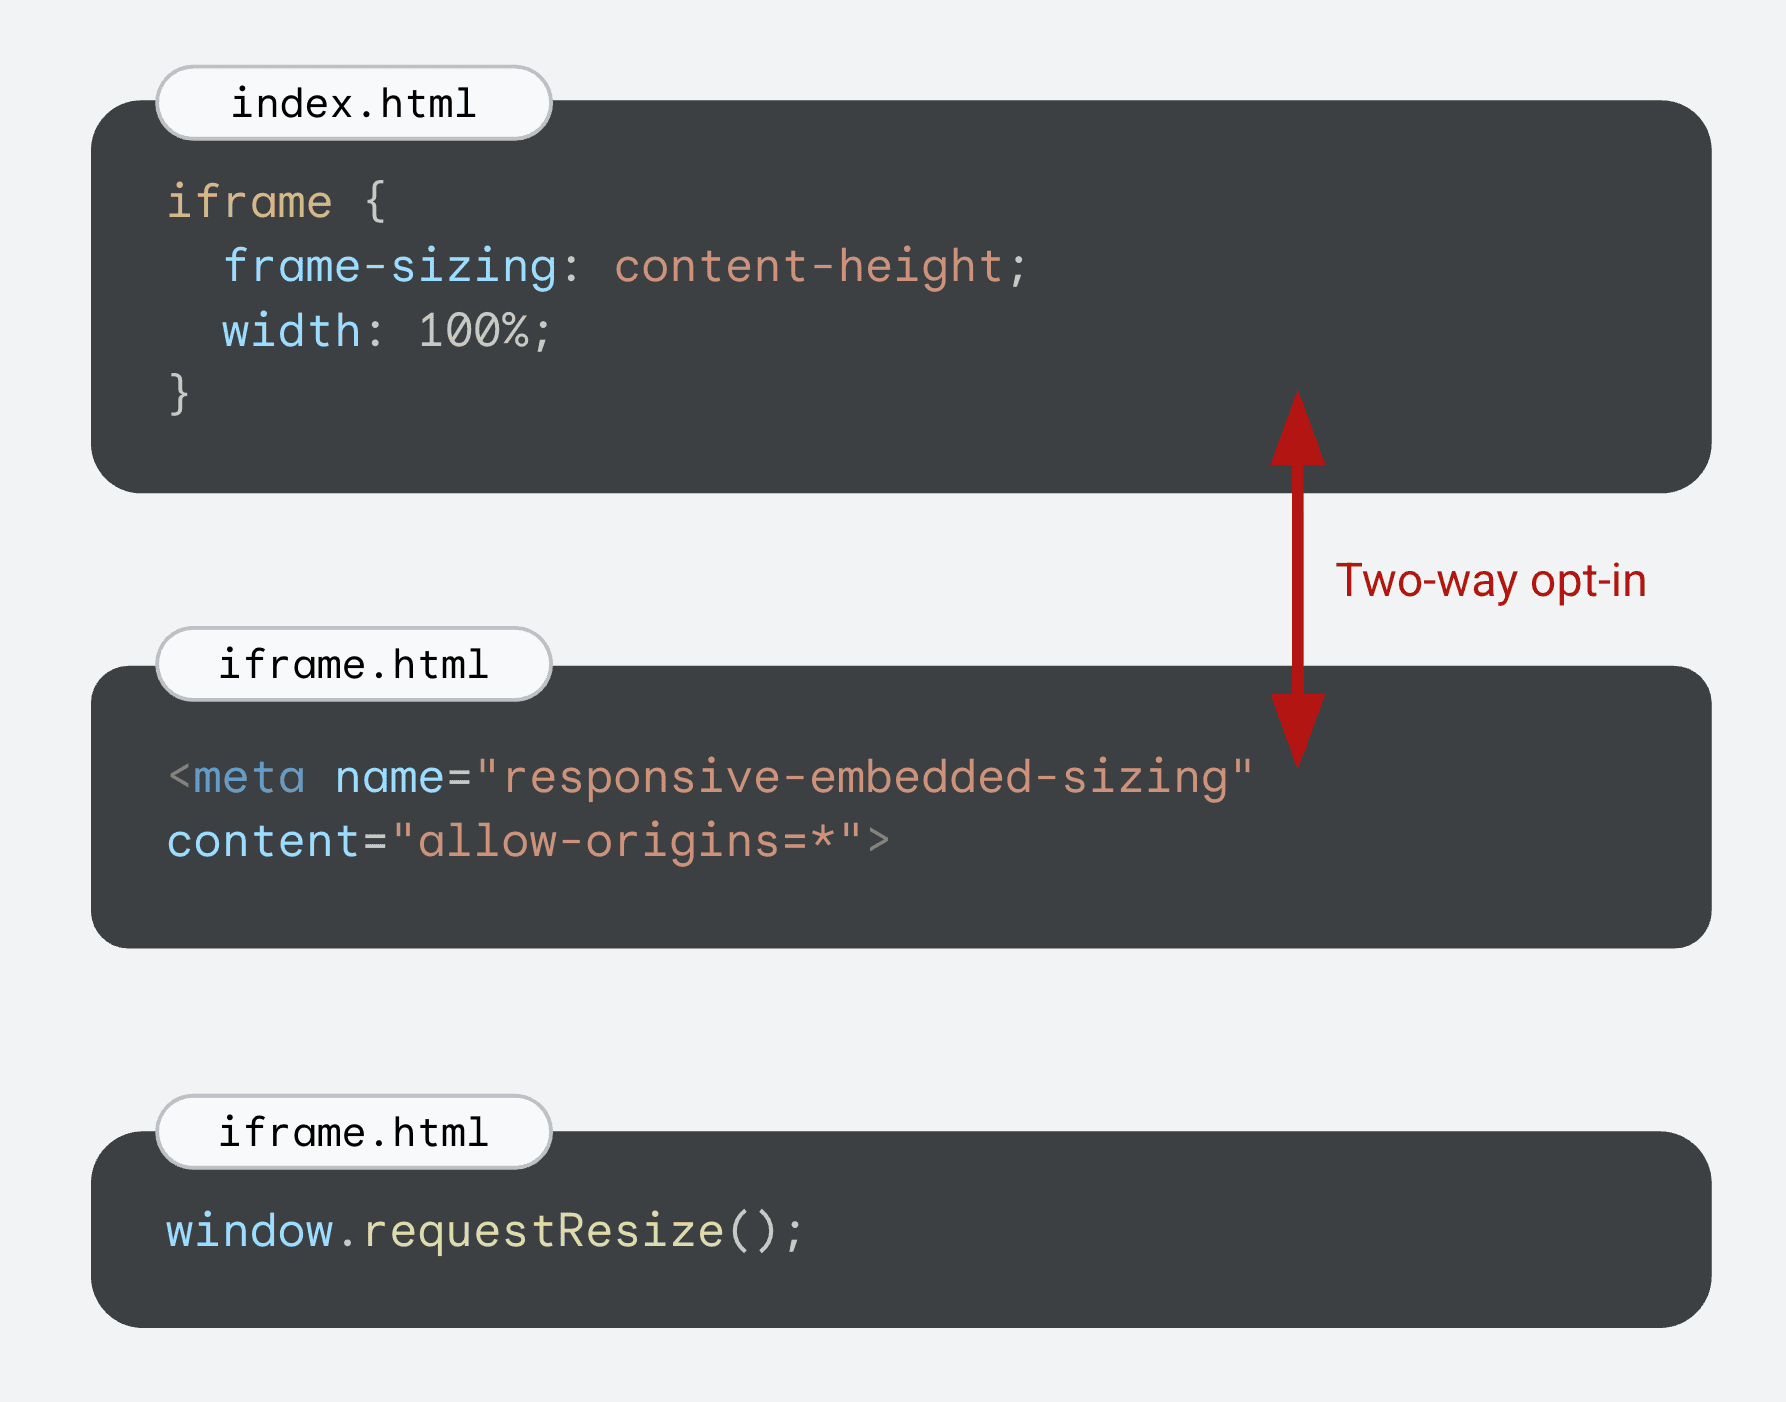
To make this work there is a two-way opt-in:

  • The embedder (e.g. index.html) needs to set the frame-sizing CSS property with a value of auto, content-height, or content-width (or its logical variants) on the iframe.
  • The document loaded in the <iframe> (e.g. iframe.html) needs to include a meta tag to indicate that it’s OK to communicate its size the parent embedder.

In code:

/* In styles.css for index.html */
iframe {
  frame-sizing: content-height;
  width: 100%;
}
<!-- In the iframe.html’s head -->
<meta name="responsive-embedded-sizing" content="allow-origins=*">

The content’s size is communicated from the embedded document after page load. To communicate a new size, the document in the frame must call window.requestResize();

Use allow-origins to limit which origins the document communicates its size info to.

~

# Demo

Here’s a demo that contains a form which is an <iframe>. Whenever you go to a next step of the form, the <iframe> resizes itself to its contents … if your browser suppports frame-sizing that is.

Because the iframe resizes itself, the form is seamlessly embedded, without any scrollbar appearing at all.

~

# Browser Support

💡 Although this post was originally published in September 2026, the list below is constantly being updated. Last update: September 26, 2026.

Support for responsively size iframes is this:

Chromium (Blink)

✅ Supported in Chrome 154

Firefox (Gecko)

❌ No Support. There is no bug tracking this yet.

Safari (WebKit)

❌ No Support. There is no bug tracking this yet.

~

# Learn More

Get all the details about responsive iframes on developer.chrome.com, in this article I co-authored: Responsive iframes in Chrome 154 →

~

🔥 Like what you see? Want to stay in the loop? Here's how:

I can also be found on 𝕏 Twitter and 🐘 Mastodon but only post there sporadically.

Read the whole story
emrox
2 hours ago
reply
Hamburg, Germany
Share this story
Delete

Is AI ruining my brain?

1 Share

I am an AI skeptic/hater/slow adopter, due to a combination of concerns about the ethics and environmental impact of AI and the fact that I like doing things myself. I knit my own socks, I built a swing for my porch this summer, and every Thanksgiving I make pies from scratch — even the crust (do you like my handmade em dash?). I truly enjoy the work of writing code, so I have been hesitant to involve AI in my workflow.

But recently, I’ve been working on a project where the team uses a lot of AI and the domain is very complex, so I’ve reluctantly been using it to help me understand what is happening in the app and how changes I make affect areas of the app I didn’t even know existed. As I get more and more comfortable turning to Cursor to help me get unstuck in my code, I do not like what is happening to my brain.

I keep knitting near my desk so I have a way to keep my hands busy in meetings and I’ve been picking it up while waiting for a response from Cursor sometimes. I’m currently working on a pretty complicated sweater pattern with minimal instructions that are hard to interpret. I recently stepped back to look at my work and saw the pattern had gotten wonky a few rows back and realized my first instinct was to turn to AI. This horrified me.

The whole reason I enjoy knitting is the process. I spend dozens of hours and more money than I’d like to admit on yarn to create a sweater that sometimes looks no better than a $20 one I could have gotten on Amazon. But that’s not the point! I enjoy knitting. I like using my brain and my hands and figuring out solutions to problems. It feels amazing to respond to “I like your sweater” with “THANKS I MADE IT ALL BY MYSELF”. Turning to AI when I encounter a bump in the road is the opposite of that. And to be totally honest, I have tried asking ChatGPT for help on projects before and it didn’t help at all. So why did I find myself reaching for AI to fix my sweater?

Apparently, I can’t isolate the way I solve problems at work from the rest of my life. Even if I can justify using it on my work project (a big if), I’m not a character in Severance. What I do at work affects my whole brain. Getting into the habit of handing AI tedious tasks and asking it to explain things I’m not familiar with instead of trying to figure them out myself seems to have decreased how much work I’m willing to put into hard things outside of work. How far will it creep into my life? When does asking Cursor to pass the right props into the right React components turn into outsourcing talking to my kids to ChatGPT?

I don’t have the answers to any of this, but I can be proud of something: my first instinct was to ask ChatGPT to fix my knitting, but I didn’t stop there. I paused, thought about how ChatGPT would approach the problem and how I would approach it, and decided that it was worth struggling through on my own. AI hasn’t ruined my brain yet, but I’m going to keep checking to make sure.

Read the whole story
emrox
2 hours ago
reply
Hamburg, Germany
Share this story
Delete

Can gzip be a language model?

1 Share

A while back I wrote about language modeling without neural networks, where I generated Shakespeare with an unbounded n-gram model: no weights, no training, just counting. Fortuitously, I came across the paper Language Modeling is Compression, which mentioned the compression–prediction equivalence:

every prediction model is inherently a compressor, and all compression algorithms are prediction models.

This led to the natural question: can gzip do language modeling?1 No neural network, no learned parameters, nothing. Just the compressor that ships with your operating system. You prime it with a corpus, give it a normal text prompt, and it continues that prompt by searching for the byte sequences that compress best. Here’s some real, unedited output after priming it on tiny Shakespeare:

gzipt --corpus data/tinyshakespeare.txt --prompt $'MENENIUS:\n' --length 200
MENENIUS:
'Though all at once canq

MARCIUS:
Pray now, nocamest thou to a morsel .

LARTIUS:
Hence, and
I' the end admire, where G
again; and after it ag .

It turns out, kind of? It’s not exactly coherent text, but it clearly knows something about the text. Much more than I expected gzip to know.2 So how can a compressor generate this?

Compression is prediction#

Think about what a compressor does. It spends few bytes on data it “expects” and many bytes on data it doesn’t. If I hand you a file that’s the letter A repeated a million times, you can describe it in one sentence. A million random bytes, on the other hand, have no structure to exploit and barely compress at all.

This is not a coincidence; it’s the core of information theory. The number of bits needed to encode a symbol is , where is the probability the model assigns to it. High probability means few bits. So any compressor has a probability model hiding inside it, whether or not anyone wrote one down.

gzip uses DEFLATE, which compresses the next bytes by finding matches against the recent text in a 32 KiB sliding window. If a continuation echoes something already in the window, DEFLATE encodes it as a cheap back-reference instead of literal bytes. So:

A continuation that gzip “expected”, because it echoes text already in its window, compresses to almost nothing.

That gives us a score. If I have some context and I want to know how good a candidate continuation is, I just measure:

The smaller the compressed length, the more “predicted” the candidate is. To prime the model, I include a corpus in gzip’s window. Any continuation that looks like the corpus compresses small, and any continuation that doesn’t compresses large.

Scoring is one thing; generating is another. The naive approach of picking the single next byte that compresses best fails badly, and for a subtle reason: gzip only gives an integer byte length (no fractions). Adding one byte often doesn’t change the compressed length at all, so many candidates tie and the signal is buried in quantization noise.

The fix is to look ahead a whole span before committing. gzipt runs a beam search over byte sequences. At each step, the current context is:

corpus window + recent tail of (prompt + generated bytes)

Then gzipt tries possible next bytes. Each candidate continuation is scored by compressing context + candidate and checking how many bytes the compressed result takes.

The loop is:

  1. Prompt. Start with the user’s prompt as the initial text to continue. There is no start token; the prompt bytes are just part of the context gzip sees.
  2. Context. Show gzip the corpus window plus the recent tail of the prompt/generated text.
  3. Search. Keep the beam_width most-compressible partial continuations. Extend each by every byte that occurs in the corpus, score all of them by compressed length, and prune back down to the best beam_width. Repeat for horizon bytes.
  4. Commit. Take the most-compressible full span (or sample among the finalists if temperature is positive), append it, and start the loop over.

One detail that matters is that only the last tail bytes of generated output stay in the scoring context. DEFLATE codes nearby matches more cheaply than far ones, so if gzip could see its entire history, the cheapest thing to do is often to fall into verbatim loops, repeatedly copying text it just emitted.


You can see the decoding and scoring process in the animation above, which is the same replay shown at the top. The whole thing is one file of pure standard-library Python (just zlib). Code’s on GitHub if you want to play with it.


  1. The paper did try this, but it ended up performing poorly. Adding beam search significantly improved generation quality (an idea they mentioned), which is discussed below. ↩︎

  2. The code actually uses zlib instead of spawning a gzip process, but the name GziPT was too good. I believe they both use the same DEFLATE algorithm under the hood. ↩︎

1

The paper did try this, but it ended up performing poorly. Adding beam search significantly improved generation quality (an idea they mentioned), which is discussed below. 

2

The code actually uses zlib instead of spawning a gzip process, but the name GziPT was too good. I believe they both use the same DEFLATE algorithm under the hood. 

Read the whole story
emrox
1 day ago
reply
Hamburg, Germany
Share this story
Delete

Jev introduces a new shape of LLM—System One, aka Decision Models

1 Share

21st September 2026

Last week TypeSafe AI unveiled Jev, their first example of a new category of model that they are calling “System One models” (I’m with Maggie Appleton, I think “decision models” is a better name for these). Jev is an interesting variant on the usual LLM format: it still accepts text inputs, but instead of text output it returns floating point numbers corresponding to categories, yes/no questions, ratings, and associated confidence scores.

TypeSafe describe Jev like this:

Think of Jev as a frontier-intelligence function call: unstructured state in, typed probabilistic decisions out.

It’s also very fast, and really cheap. Regular LLMs are priced in terms of input and output tokens, with output generally charged at significantly higher rates. Jev charges only for input—output is free—and the input price of their first model is $0.042 per million tokens—cheaper even than OpenAI’s GPT-5 Nano ($0.05/million).

Jev lets you ask questions about text or semi-structured data. You compose a “state” object containing a string, array of strings, or set of name-value pairs—this might describe an article, or a customer, or any other kind of record. You then send that to their API with one or more questions, and get a reply back for each.

You can ask three kinds of questions:

  • Yes/No questions, which Jev calls “Noul” questions—their CEO confirmed on Hacker News that this is short for Bernoulli, from the Bernoulli distribution. You pose a statement and get back a floating point number between 0 and 1 for how confident the model is that the statement is true.
  • Choice questions, where the model picks one from a set of provided options—actually a confidence score plus a probability distribution across all of the options.
  • Score questions, where you provide sequence of numeric levels with descriptions and it provides a floating point score somewhere along that range.

The Jev API can accept a single document (“state”) and as many questions as you can cram into the context window. Questions are evaluated in parallel, so sending many questions should take a similar time to sending just one.

I think the decision model framing is useful for understanding where to use Jev. It’s great for anything that can be expressed as a classification task—think spam detection, suggesting labels, prioritization and ranking.

I’ve also been experimenting with it for search reranking, where you fetch 100 likely matches using an inexpensive algorithm like BM25, then have Jev score those 100 candidates for relevance against the original query.

Black boxes are back in fashion #

Something I’ve found a little uncomfortable about Jev is how it very much represents a regression even further towards black box machine learning systems.

LLMs are black boxes already—you can ask them to justify their decisions, but you can’t guarantee that what they say is useful or accurate.

Jev doesn’t even give you that: put in all the text you want, the only thing you’re going to get back is a floating point number. If Jev marks something as spam, which content signals tipped it off?

This also means that concerns about bias should be front and center. I really hope nobody uses Jev to rank job applicants—that floating point number could conceal all manner of unseen bias baked into the models, and experimentally picking that bias apart is going to be a tricky business.

(I tried one experiment where I had Jev score every city in the San Francisco Bay Area on a yes/no answer to whether they were a “Good city?”—it rated Cupertino top and East Palo Alto bottom. Huh.)

In practice, this all means that evals and structured experiments are even more important than they are for regular LLM projects. Thankfully, Jev is so cheap that running hundreds or even thousands of experimental prompts through it costs just a few cents.

Unconventional uses for Jev #

It’s been really fun watching the wider community come up with potential use-cases for Jev over the past few days. Here are some creative ones that caught my eye:

  • jevchat by Kyle Pena turns Jev into a (terrible) chat model. “At every step it asks Jev one question: Given the user’s question and the reply written so far, which symbol comes next?”. ericpruitt on Hacker News: “It’s the digital equivalent of Morty speaking with the death crystal”.
  • jev-leftpad by Fatih Kadir Akın implements left-pad with the prompt “How many spaces are needed before value to reach targetLength?” and a choice query allowing options from “0 spaces are needed” to “10 spaces are needed”.
  • jev-2048 by Andy Gayton uses Jev to play the 2048 sliding puzzle game.

Open weight recreations #

There’s also been a flurry of projects attempting to create a model like Jev using on top of open weight models. Kev is one interesting example, using Qwen 3.5 to produce 0.8B, 4B, and 9B models. Here’s the accompanying Hacker News thread, where someone linked to a JevBench benchmark that has already cropped up to compare “Jev-class decision models”.

Given Jev was released just under a week ago, the amount of activity around it is extremely impressive.

Read the whole story
emrox
1 day ago
reply
Hamburg, Germany
Share this story
Delete

The search for a Spotify alternative

1 Share

About six months ago, I realised I was feeling increasingly uncomfortable paying for our Spotify Premium Family plan. The company had hiked its prices yet again. It had changed its policy to remove any royalty payments to artists with under 1,000 streams a year — despite already taking the number one spot for the worst-paying streaming service (already a low bar). And Spotify CEO Daniel Ek is investing the huge personal profits he’s made from these tactics into AI-powered weaponry. So I decided, like quite a few folks have recently, that it was time to look for an alternative streaming service.

And in those six months, I’ve been trying pretty much all of them. This post is intended to serve as a non-exhaustive list of considerations for anyone else of doing the same. (Because it was exhausting, believe me.)

But first, a caveat: this post is about choosing a streaming service, not about if they could or should be used in the first place. I’m a lifetime Plex user and I love it. My Plex library is loaded with all the music that’s not on the streaming platforms, most of it purchased from Bandcamp. But, for better or worse, streaming is a must-have in our household (and switching or remaining on a service is a four-person decision), so going Plex-only isn’t an option.

Second caveat: as an artist, I have no intention to remove my music from Spotify. Although I’m not so active with releasing new music these days, taking my music off the platform would just be shooting myself in the promotional foot. So that’s a consideration for another day.

Lastly, a warning: please don’t do what I’ve done, which is pay for multiple services for six months while I attempt to make my mind up and write this bloody long blog post. Oh, and here’s another tip: TuneMyMusic is what I used and (temporarily) paid for to move my library to and from the various services — although it’s worth Qobuz has Soundiiz integration built in for free.

Oh, and: all of these views are my own, obviously.

The logical first choice in a search for a Spotify alternative was Apple Music. We’re already paying monthly for Apple TV+ and extra iCloud storage, so upgrading to an Apple One family plan would only be a couple quid more a month. Easy decision. I’d tried out the service about a year or so ago and not got on with its design, but guessed that in that time, things must’ve improved. Surely they would’ve finally found a way to get around that legacy confusion between Apple Music, iTunes, and the iTunes Music Store, right…?

Conceptually, it feels like the service is still unsure about what it wants to be, and this manifests in a variety of UX inconsistencies.

Try searching for an artist: you can filter your results by ‘Your Library’, ‘Apple Music’, and ‘iTunes Store’. That seems logical enough, except that Your Library is actually a mix of music you’ve either purchased or loaded into the-library-formerly-known-as-iTunes, plus any music you’ve saved from Apple Music.

Screenshot of the Apple Music service Left: an artist page within your library. Right: an artist page within Music.

Navigate through your library to your artist of choice, and suddenly it’s gone all iTunes-like again, where no artist names are links… unless, that is, you go via the Albums tab in the sidebar, and then they are links from those album pages… which now look somewhat more Apple Music-like again.

Screenshot of the Apple Music service Left: an album within your library. Right: the same album on Music.

It’s a frustrating experience because this inconsistency leaves almost every interaction feeling like a guess. And it’s even more infuriating because it feels like Apple should’ve fixed this stuff years ago. Not just fixed — nailed it. It’s Apple. They can and should operate the very best music streaming / purchasing / collecting experience there is, especially on their own platforms. Even with the superior design of the iOS app over its macOS counterpart, the conceptual heart of Apple Music is, in my opinion, still too muddled to be usable. Most of my friends who’ve moved there from Spotify seem like they’re putting up with it rather than enjoying it. (One thing I do like about Apple Music, which more services should support, is making the record label a link to all releases from that label.)

In fairness to Apple, one of my additional strikes against the service was because personally I just like dark interfaces for music apps. I’m sure this is because Spotify has accustomed me to it over the years, but the fact that Apple Music in black can only exist if you change your whole system to Dark Mode feels like an unnecessary restriction. So, with a dark interface as a criteria, my attention to turned to… well, pretty much any other streaming service.

Deezer — great, but let down by one huge bug

Deezer wasn’t originally on my list because when I’d last looked, its design looked pretty dated, but hold on, what’s this? Deezer now looks, in fact, rather lovely! Who knew? (Okay, lots of people knew — their brand refresh happened in 2023 and was handled by none other than Koto, and the brand’s bespoke typeface, Deezer Sans, was designed by the wonderful NaN, so of course it’s gorgeous.) Anyway, yes, this won Deezer lots of points in my book. I’m a pathetic, shallow, aesthetics-focussed designer, after all.

First impressions were pretty good. Deezer’s got a friendly interface with lots of customisation options (made dark instantly, of course). It’s kind of odd that the playlists sidebar only shows some of my playlists, but I can live with it. Slightly weird that clicking on the track titles does absolutely nothing: unlike every single other service, which effectively treats the whole track area as a button, you need to explicitly hit the play (or pause) button next to the track. Why is this? This hit area decision can’t be intentional, can it? It’s fine, though. I can live with this, too.

There are some lovely touches, like being able to pin artists, releases, or playlists to the ‘Quick access’ sidebar. The overall design and behaviour of the apps won me over: I decided Deezer was the one to switch to. Time to start the move!

But then something very odd happened.

I was on the profile page for Recondite, an electronic artist whose album Hinterland (released on Ghostly International in 2013) is one of my all-time favourites to play in winter time. But this album was nowhere to be found.

Screenshot of the Deezer music service The album isn’t there. In fact, no albums are there! This artist has albums, trust me.

Worried that it might not be in Deezer’s catalogue, I searched for it and found it. Phew!

Screenshot of the Deezer music service Wait, it is there!

But why wasn’t it appearing on his artist page? In fact, why weren’t any of his albums showing up on that page? After all, they do show up on the search results page for “Recondite”.

Screenshot of the Tidal music service I’m losing my mind here.

Going the other way, clicking the artist page link from the album page, demonstrated it was definitely connected to the correct artist, so I assumed it must be down to some inconsistent metadata. Oh well. Annoying, but not a biggie.

Except that then, it happened again. And again. And again.

These next examples were for more mainstream artists, and it started to seem pretty strange that the albums weren’t showing up on these artists’ pages. And it couldn’t be bad metadata — on every other service I tested, the releases were present on the profiles.

A quick bit of Kagi-ing revealed two things: firstly, that I wasn’t going crazy (what a relief); secondly, that this has been a known issue for years. Just take a look at the number of people questioning it on Reddit or even on Deezer’s own community pages (where several admins mistakenly claim that the issue is fixed). This came as a relief, but it’s also baffling: how can a service as mature as Deezer have such a fundamental flaw with its catalogue?

For folks questioning why this might be a problem, it’s worth remembering that exploring an artist’s discography is a vital part of the process of discovery — you find a new band you like and you want to see what else they’ve released — and therefore it’s a vital form of potential revenue for the artist. The money made from streaming is pitiful, whatever the service, but 10 streams of an album’s tracks that then convert to 100 streams of their other albums is clearly better than a one-release dead-end.

Tidal — nice, but not immune to metadata muddles

Deciding that this well-known and oddly unfixed discography bug made Deezer usable for me, I turned my attention to Tidal. Despite perhaps looking a little too much like Spotify, I immediately felt at home, and the inclusion of high-quality audio for a monthly price that’s a good 20% cheaper than Spotify’s seems quite reasonable. There are some nice unique features, too, like being able to group playlists into folders.

Screenshot of the Tidal music service Playlist folders! Why doesn’t everyone have this?

Unfortunately, Tidal isn’t immune to weird metadata bugs. I’ve come across a few instances of multiple profiles for an artist or band, with the releases spread across both, often with one very clearly being the official, label-managed page.

I noticed some of these being fixed. Even over the course of writing this post, Tidal seemed to consolidate Spiritbox’s profile to include all of their releases. But then I discovered Vower and found their discography split across two profiles.

Screenshot of the Tidal music service Left: Vower’s artist page. Right: also Vower’s artist page. Wait, what?

This actually highlights a problem with metadata as a whole: if you want, you can upload a release (via a distribution network), put in whatever metadata you like, and effectively break the system. This is exactly what’s happening with all the AI-authored slop being uploaded to the streaming services, credited to ‘real’ artists — and therefore receiving a tonne of streams from devoted fans keen to hear their new releases — when in fact the only thing shared by these nefarious tracks and the legit artists is the value in a cell in a metadata spreadsheet.

However, this is an issue with the way streaming services work rather than Tidal specifically. And Tidal does at least seem to be attempting to fix these things. So it looked like Tidal could be the one. Some slight weirdness, but no outright showstoppers like Deezer.

But then I got in the car.

Our Volvo XC40 has Android Auto. I can use CarPlay if I plug the phone in, but my wife and kids prefer something more instant, especially when you can just ask the car to play music. We’ve always used the Spotify app without issue, but for some reason both the Deezer and Tidal apps are more basic: searching for an artist and then tapping on that result simply plays their top track. Digging into any discography is almost impossible unless you ask for a specific release name. And the CarPlay apps aren’t actually much better because you’re forced into navigating via Siri — still the most useless assistant out there.

With frustrating apps getting in the way of a decent listening experience, maybe it was time to look again at some more alternatives?

YouTube Music & Amazon Music

YouTube Music: Around the time I started this experiment, YouTube had offered me a one-month free trial of YouTube Premium, which includes full access to YouTube Music. Or, to put it another way, your YouTube Music subscription will remove ads from your videos — and that’s a tempting offer. But I quickly decided against this service: the lack of a dedicated macOS app and a catalogue overstuffed with bootlegs made YouTube Music a no-go for me (even with its dark interface).

Amazon Music: Apparently — and I think this’ll come as a genuine surprise to just about everyone — Amazon pays artists better than some of the other streaming services. But even a very quick test of it proved that it was missing vital albums from my favourites. It was a consideration for about half an hour of testing.

Back to Apple Music via DaftMusic (and Albums)

Frustrated by Deezer and Tidal, and put off almost instantly by the alternatives, I was encouraged to see the release of DaftMusic — a UI for accessing Apple Music without any of the, well, Apple Music UI. And it’s nice! It manages to get around the iTunes-like ‘Collection’ weirdness and there are a load of customisation options, too. Plus, I love supporting indie developers.

Screenshot of the Daft Music app DaftMusic: a third-party UI for Apple Music. Way nicer than what Apple came up with themselves.

Unfortunately, the need to manually import playlists to the app (rather than them being synced from the Apple Music itself) is a pain when using multiple devices. I’m excited to hear that an iOS app is on its way, though, and how this might change things.

I also briefly tried Albums after my mate Jon Hicks’ recommendation. The iCloud-powered syncing across Mac and iOS is great and, again, yay for indie devs. But my family love their playlists, so an album-only interface is never going to fly.

Is anything as good as Spotify?

About two months ago, I was getting ready to hit ‘publish’ on an earlier draft of this post that ended with a disappointing conclusion: that, because every other streaming platform I’d tried has a range of issues — in some cases, bugs that hamper basic everyday use — it was impossible, right now, to replace Spotify.

Yes, it’s still susceptible to the metadata issues and abuses I’ve detailed above. Yes, it’s bloated and full of podcasts and audiobooks and videos you don’t want. And yes, Daniel Ek’s investment choices — but it does so much well. Custom-sorting for playlists feels like such an obvious feature and yet it’s missing from the competition. And Spotify Connect — being able to swap playback between devices seamlessly (something we do a lot in our house, especially when one iPad dies, or even to see when someone’s playing something in the car while I’m at my desk) is something I missed while trying every other service. But most importantly, it… just works. There are no weird bugs that stop me from discovering an artist’s discography or outright stop me from playing music. It’s far from perfect, but it comes a lot closer to perfect than the competition.

So I was about to end this experiment by cancelling all of the subscriptions I’ve been testing and decide, reluctantly, to continue paying for Spotify — a conclusion I wasn’t at all happy about. This prompted me to give one last service a try: Qobuz, the one billed for audiophiles and fans of Classical music. I’d dismissed it based on its marketing materials, but figured it was fair to give it a shot.

And I’m so glad I did.

The surprise twist: Qobuz is pretty damn good

I’m very happy to be publishing this blog post with a conclusion that feels morally right: I’ve cancelled our Spotify Premium Family plan and moved us over to the Family plan on Qobuz. It’s not perfect, but it does get most things right.

To be honest, it’s not the high fidelity sound (Qobuz’s main selling point) that really interests me; it’s more the thoughtful approach to the service as a whole. Plus, it’s customisable, and this is important because I must admit I’m not in love with its design out of the box. But modified to use the Qobuz Theme v1.3 by Jon Hicks, the desktop app is subtly but significantly better.

Screenshot of the Qobuz music service Left: the Qobuz macOS app, out-of-the-box. Right: the beta version of the app, using Jon Hicks’ Qobuz Theme v1.3.

Please note that the screenshots that follow all show this customised version, sporting Jon’s CSS. Is it fair to compare the other services to a version of Qobuz that isn’t actually representative of the company’s own vision for their product? Probably not, if I’m being honest. However, the fact that it is theme-able, and that you can get this UI with very little tinkering required, is one of the many benefits of Qobuz over the others.

Here are some things that stand out to me about this service over the others:

Qobuz Connect: Working exactly like Spotify Connect, you can move your music between devices with ease. It’s a little buggy in that one of my work Mac seems determined to return to the in-built speakers when I’ve paused music for a while, but it works well enough. I can’t understand how it’s only Spotify and Qobuz that have this output-swapping functionality — it should be on every single music service.

Screenshot of the Qobuz music service Qobuz Connect gives you a lot of choice when it comes to outputting the audio.

Releases: Qobuz calls them what they should always be called: releases. You can’t group all music as ‘albums’, as so many services do, despite them being EPs or singles or compilations. Okay, it’s a small point, but these things add up to show that they care about music.

Screenshot of the Qobuz music service The Discover (i.e. ‘home’) tab. The navigation is considerably more condensed (for the better) in the beta version of the app, and again, this also has Jon’s custom CSS on top of it.

Record labels: like Apple Music, they’re all clickable, which not only takes you to a label page, but also means they can be saved to your library, so they exist on the same hierarchical level as artists, releases or playlists — and can be followed. This is such a great way of discovering music.

Screenshot of the Qobuz music service The label page for Ghostly International — navigated to by clicking on the label name within a release page.

Magazine: With a strong focus on editorial content, Qobuz’s own digital magazine is built right into the experience. I didn’t see the benefit of that at first, but when magazine content related to artists started showing up on their profiles or on release pages, it all made sense.

Screenshot of the Qobuz music service The Magazine’s homepage. Screenshot of the Qobuz music service Note the magazine content showing up on PJ Harvey’s artist page.

Catalogue vs. library: If you’re on a release page that’s been saved to your library, and then click on the artist name, it’ll initially only show you releases from that artist in your library, and my first reaction was this is bonkers! Why would anyone want that? but then realised that you can then toggle to view the full catalogue, and this makes so much sense. This is exactly the approach Apple Music should’ve taken to overcome the confusion around local files, treating the release as the primary object, with metadata attached to it, rather than the other way around.

Screenshot of the Qobuz music service Left: Nils’ Frahm’s artist page with the “Catalogue” toggle on; right: the same with the “Library” toggle active. Screenshot of the Qobuz music service A close-up of the “Catalogue” / “Library” toggle on Queens of the Stone Age’s artist page.

Of course, Qobuz isn’t immune to metadata weirdness, and actually this is the only service I’ve noticed this on: all music ever made by Dominick Fernow is attributed to his main alias Prurient, rather than to his respective monickers, such as Vatican Shadow (Muslimgauze-esque techno) or Rainforest Spiritual Enslavement (dark ambient). It might seem like a nitpick, but I’m sure it’s not what the artist would want, given that he uses those distinct identities to release music across totally different genres.

Screenshot of the Qobuz music service This release should be credited to Rainforest Spiritual Enslavement, not Prurient (even though they were composed by the same musician).

Beyond this metadata niggle, there are some other points that work against Qobuz, too:

These irks are not small. But, in my opinion, Qobuz does a far better job at being a very capable music streaming service, with more solid apps across various platforms, than Deezer, Tidal, YouTube Music, Amazon Music, and yes, Apple Music. And it’s a family-run business, based in France, that clearly cares about music, paying artists 4× the industry average. In terms of simply trying to do something different, it’s hard to fault chez Qobuz.

There are certain things I miss deeply about Spotify. In fact, I’d go as far as to say that I think Spotify is actually the best music streaming service that currently exists. But if, like me, you feel morally uncomfortable paying for a Spotify subscription, then consider Qobuz as a worthy replacement that — perhaps surprisingly — is way ahead of the more established competition.

Read the whole story
emrox
1 day ago
reply
Hamburg, Germany
Share this story
Delete

Play snail racing simulator online 🏁🐌

1 Share

Pick a snail and get comfortable. It's a long race and overtakes are rare, but the snails are taking it extremely seriously, so the least you can do is watch. Unless, of course, you happen to know how to encourage one.

Need to settle something?

The real thing

Snail racing is a genuine sport, and a wonderfully British one at that. Somewhere between a village fête, a sporting tradition and something invented because it was raining, people have been gathering to watch numbered garden snails cross damp cloth for decades.

The World Snail Racing Championships have been held in Congham, Norfolk, since the 1960s. Competitors are common garden snails, Cornu aspersum if you're being formal. Each gets a number painted on its shell and starts in the middle of a damp cloth. First to cross the circle 13 inches away wins. That's it. That's the sport.

The record belongs to Archie, who covered the course in exactly two minutes in 1995, a blistering 0.006mph. More than thirty years later, nobody has caught him. Heikki managed 3 minutes 2 seconds in 2008, Terri 2 minutes 49 the year after, and Sammy got it down to 2 minutes 38 in 2019. The dream remains alive.

Over in Cambridgeshire, the Grand Championship Snail Race at Snailwell has been running since 1992 and can attract up to 400 spectators, more than doubling the population of the village. The starting call, "Ready, steady, slow", came from the 1999 Guinness Gastropod Championship and remains the best thing anyone has ever said to a damp cloth.

The snails here race the same distance at roughly the same pace, with approximately the same understanding of what's happening. None of them has ever failed a drugs test. Mostly because nobody has tested them.

Know your snail

Snails are molluscs, distant cousins of the octopus, though you wouldn't guess it from watching them. They breathe through a hole in their side called a pneumostome, their blood is faintly blue, and they eat using thousands of microscopic teeth arranged on a ribbon called a radula.

Their eyes are on the ends of the long tentacles. The shorter pair are used for smelling and feeling their way around, which seems sensible when your top speed is measured in thousandths of a mile per hour. They don't have ears either, so they can't hear a thing, cheering included. Please cheer anyway. It's good for morale, probably yours. The shell is mostly calcium carbonate, the same stuff as chalk. A snail hatches with a tiny shell already attached and adds to it as it grows. Most land snails are both male and female. Given the choice, they'd do most of their moving at night or after rain, which goes some way to explaining the times.

There's more on Wikipedia, all of it apparently true.

There are snail racing achievements to be had, if you're the collecting type.

Read the whole story
emrox
1 day ago
reply
Hamburg, Germany
Share this story
Delete
Next Page of Stories