4036 stories
·
4 followers

What's new in Node.js 27

1 Share

On October 29, 2026, the Node.js team published v27.0.0-alpha.0.0.0. If you have been using Node.js for a few years, that version string alone probably made you do a double take. Where is the usual October v27.0.0 Current release?

Node.js 27 is the first release to follow the new annual schedule. Under the old schedule, October brought a major release that reached end of life six months later without entering Long Term Support (LTS). October now starts a six-month Alpha phase, ahead of the 27.0.0 Current release in April 2027 and LTS promotion in October 2027.

In this first Alpha, V8 moves from 14.6 to 15.6, adding Iterator.zip(), Iterator.zipKeyed(), Iterator.prototype.join(), Iterator.prototype.includes(), and Math.sumPrecise(). There is a promises API for node:net, along with async-iterable TCP servers. The Virtual File System (node:vfs) is now unflagged, the Permission Model gains --allow-env, and HTTP and memory defaults change too.

We’ll start with the JavaScript and Node.js APIs you can use in everyday code, comparing them with the older approaches. Then we’ll cover runtime changes and what to check before upgrading.

Quick Answer: what’s new in Node.js 27

The main additions in Node.js 27 so far:

  1. New Iterator helpers (zip, zipKeyed, join, includes) pair sequences, join their values into strings, and search them without collecting intermediate arrays.
  2. Math.sumPrecise() sums an iterable of numbers without rounding each intermediate addition.
  3. node:net/promises and async-iterable net.Server let you use async/await to set up TCP servers and sockets.
  4. Virtual File System (node:vfs) is unflagged, making in-memory file systems and --vfs-load available without --experimental-vfs.
  5. Core upgrades across fs, permissions, test runner, and http, including atomic temp files with fs.mkstemp(), --allow-env, Jest-style mock helpers, and a 65-second HTTP keepAliveTimeout.
  6. V8 15.6 and OpenSSL 4.1 update sorting and cryptography, and the default heap limit rises to 4 GB on an 8 GB machine.

For example, we can format a list of products and total their prices:

const items = ['Keyboard', 'Mouse', 'Monitor']

const prices = [129.99, 49.99, 349.95]

const lines = Iterator.zipKeyed({ item: items, price: prices })

.map(({ item, price }) => `${item} ($${price.toFixed(2)})`)

.join(', ')

console.log(`${lines} -> Total: $${Math.sumPrecise(prices)}`)

// Keyboard ($129.99), Mouse ($49.99), Monitor ($349.95) -> Total: $529.93

If you want to experiment locally, check your current Node.js version before running the snippets below.

New Iterator superpower: zip, zipKeyed, join, and includes

This is the part of the release I’m most excited about. I love seeing how far we can push streams, iterators, and generators. Our article on JavaScript async iterators should give you an idea of what I mean.

In What’s new in Node.js 26, we used Iterator.concat() to consume multiple iterables one after another. Node.js 27, through V8 15.6, lets us consume them side by side, pairing values at the same position.

Pairing sequences lazily with Iterator.zip()

Suppose you are checking a weather forecast against the temperatures recorded over the same four days. The predictions come from your model, while the actual values come from observations. To calculate each day’s error, you need to pair the values at the same position. Both sequences must cover the same days in the same order.

In Node.js 26 and earlier, if both sequences were arrays, you would typically use .map() with an index lookup:

// Node.js 26 and earlier

const predicted = [18, 21, 20, 23]

const actual = [19, 20, 22, 21]

const errors = predicted.map((prediction, i) => actual[i] - prediction)

console.log(errors) // [1, -1, 2, -2]

That works well for arrays. But what if observations come from a generator, or your model returns an iterator of predictions? Index lookups won’t work on those inputs, and converting them to arrays means loading both sequences into memory first.

In Node.js 27, Iterator.zip() takes an iterable of iterables and returns a lazy iterator of pairs. We can calculate the errors with the same pipeline whether the inputs are arrays or iterators:

const predicted = [18, 21, 20, 23]

const actual = [19, 20, 22, 21]

const errors = Iterator.zip([predicted, actual])

.map(([prediction, observation]) => observation - prediction)

.toArray()

console.log(errors) // [1, -1, 2, -2]

Each pair contains a prediction and its corresponding observation. A positive error means the day was warmer than predicted; a negative error means it was cooler. The pairing and mapping happen one item at a time. Only the final .toArray() collects the errors into an array so we can print them together.

Another common use is the dot product of two vectors: multiply matching components, then add the products. This operation appears in graphics, machine learning, and numerical computing:

const a = [1, 2, 3]

const b = [4, 5, 6]

const dotProduct = Iterator.zip([a, b], { mode: 'strict' })

.map(([x, y]) => x * y)

.reduce((sum, product) => sum + product, 0)

console.log(dotProduct) // 32 (1 * 4 + 2 * 5 + 3 * 6)

Here we never collect the pairs or products into an intermediate array. We also use mode: 'strict' because a dot product requires vectors of equal length: silently ignoring extra components would hide an input error.

Combining endless iterators: solar generation and household consumption

So far, our inputs have been arrays. But Iterator.zip() also works with iterators that have no end. Imagine a home with two power meters: one measures solar generation, and the other measures household consumption. Each meter gives us its current reading in watts whenever we poll it. Subtracting consumption from generation tells us whether the house has surplus power to export or needs to import power from the grid (assuming there is no battery).

We can wrap each meter in an endless generator. Here we simulate the readings with random values so the example runs without hardware:

function* powerReadings(readWatts) {

while (true) {

yield readWatts()

}

}

// Simulated meters: each call produces a fresh reading in watts.

const solar = powerReadings(() => Math.round(Math.random() * 4000))

const household = powerReadings(() => Math.round(Math.random() * 3000))

const netPower = Iterator.zip([solar, household]).map(

([generation, consumption]) => generation - consumption,

)

for (const watts of netPower.take(5)) {

if (watts > 0) {

console.log(`Exporting ${watts} W`)

} else if (watts < 0) {

console.log(`Importing ${-watts} W`)

} else {

console.log('Generation matches consumption')

}

}

Neither generator reads anything until we request a value from netPower. Each request polls both meters once and calculates the difference. Both input iterators can keep producing readings forever, but .take(5) limits this demo to five pairs. Collecting either input with [...solar] or .toArray() would never finish and would eventually exhaust memory.

These are synchronous, on-demand readings: the two meters are polled sequentially, close together, rather than at exactly the same instant. The loop takes five readings immediately; zip() does not add a polling interval. With real hardware, the callbacks would read the meters instead of generating random numbers.

Turning columns into objects with Iterator.zipKeyed()

Tuple arrays like [prediction, observation] are easy to read for two or three items, but once you have four or five parallel sources, positional destructuring gets easy to mix up.

Iterator.zipKeyed() accepts an object whose values are iterables. Each step yields an object with the same keys, so you can refer to values by name instead of position:

const columns = {

id: [101, 102, 103],

user: ['alice', 'bob', 'charlie'],

role: ['admin', 'editor', 'viewer'],

}

const rows = Iterator.zipKeyed(columns)

for (const row of rows) {

console.log(`${row.user} (#${row.id}) has role: ${row.role}`)

}

// alice (#101) has role: admin

// bob (#102) has role: editor

// charlie (#103) has role: viewer

If an API returns each field as a separate array, like user IDs, names, and roles, Iterator.zipKeyed() lets you process them together as a lazy sequence of row objects. The arrays must describe the same records in the same order.

Finishing pipelines with Iterator.prototype.join() and includes()

In Node.js 26, a common way to format a lazy iterator pipeline as a string was to call .toArray().join(', ') at the end. The final .toArray() allocated an array of strings that .join() consumed and discarded.

V8 15.6 adds two terminal helpers directly onto Iterator.prototype:

  • Iterator.prototype.join(separator): consumes the iterator and joins items into a string directly.
  • Iterator.prototype.includes(value): consumes the iterator until it finds a matching value (using SameValueZero equality, just like Array.prototype.includes()) and short-circuits immediately.

For join(), let’s return to our sensor readings. This time we only need one temperature sensor, and we want to format five readings as a comma-separated string. As before, we simulate the hardware so you can run the example locally:

function* temperatureReadings() {

while (true) {

yield 18 + Math.random() * 6

}

}

const readings = temperatureReadings()

.take(5)

.map((temperature) => `${temperature.toFixed(1)}°C`)

.join(', ')

console.log(readings)

// For example: 21.3°C, 19.8°C, 23.1°C, 20.0°C, 22.4°C

.take(5) makes the endless source finite, .map() formats each reading, and .join() builds the string without collecting an intermediate array. These five readings are taken immediately, with no delay between them. Without .take(5), joining this endless iterator would never finish.

For includes(), imagine checking whether a commit message references a particular issue. String.prototype.matchAll() already returns an iterator, so we can extract the complete references and search them directly:

const message = 'Fixes APP-142. Follow-up work tracked in APP-208.'

const references = message.matchAll(/\bAPP-\d+\b/g).map((match) => match[0])

console.log(references.includes('APP-142')) // true

includes() stops as soon as it finds APP-142, without extracting the later reference. Matching complete references also avoids the false positive you would get from message.includes('APP-14'), which matches part of APP-142. The search consumes the iterator, so create a fresh one for another search.

More accurate sums with Math.sumPrecise()

Beyond iterator helpers, V8 15.6 also brings a useful addition for numerical calculations: Math.sumPrecise(). To see why it matters, let’s look at a familiar floating-point surprise.

// Node.js 26 and earlier - floating-point drift in action

const cartPrices = [129.99, 49.99, 349.95]

const naiveTotal = cartPrices.reduce((sum, price) => sum + price, 0)

console.log(naiveTotal)

// 529.9300000000001 (!)

// Even worse: catastrophic cancellation when large and small numbers mix

const ledger = [1e20, 0.1, -1e20]

console.log(ledger.reduce((sum, n) => sum + n, 0))

// 0 (the 0.1 completely vanished!)

When you sum numbers with .reduce((a, b) => a + b, 0), each addition rounds its intermediate result to the nearest representable 64-bit float. Over dozens or thousands of additions, those tiny rounding errors accumulate. Worse, if you add a small number (0.1) to a huge number (1e20) and later add -1e20, the 0.1 is lost completely during the first addition because a 64-bit float doesn’t have enough mantissa bits to hold both magnitudes at once.

In Node.js 27, V8 15.6 enables Math.sumPrecise() by default. It accepts any iterable of numbers, computes the sum using an internal high-precision accumulator, and rounds only once at the very end:

const cartPrices = [129.99, 49.99, 349.95]

console.log(Math.sumPrecise(cartPrices))

// 529.93

const ledger = [1e20, 0.1, -1e20]

console.log(Math.sumPrecise(ledger))

// 0.1 (no precision lost!)

Math.sumPrecise() accepts any iterable, so it also works with the iterators from the previous section. You can pass the result of .map() directly into Math.sumPrecise() without calling .toArray() first:

const orderLines = [

{ item: 'USB-C Hub', qty: 2, unitPrice: 39.99 },

{ item: 'Mouse', qty: 1, unitPrice: 49.99 },

{ item: 'Monitor', qty: 1, unitPrice: 249.95 },

]

const total = Math.sumPrecise(

orderLines.values().map((line) => line.qty * line.unitPrice),

)

console.log(`Order total: $${total}`) // Order total: $379.92

node:net/promises and async-iterable TCP servers

The core node:net module gets iterator support too.

For years, node:fs, node:dns, node:stream, node:timers, and node:readline have all had .promises sub-modules. Yet node:net remained purely callback- and event-driven. If you wanted to spin up a TCP server on an ephemeral port in a test or connect a client socket using async/await, you had to wrap 'listening', 'connect', and 'error' events by hand.

In Node.js 26 and earlier, setting up a TCP server and client with async/await looked like this:

// Node.js 26 and earlier - manual event-to-promise wiring

import { createServer, createConnection } from 'node:net'

import { once } from 'node:events'

const server = createServer((socket) => {

socket.end('Hello from TCP server\n')

})

server.listen(0, '127.0.0.1')

await once(server, 'listening')

const { port } = server.address()

const client = createConnection({ port, host: '127.0.0.1' })

await once(client, 'connect')

for await (const chunk of client) {

console.log('Received:', chunk.toString().trim())

}

server.close()

Node.js 27 introduces the experimental node:net/promises module with two helpers, listen() and connect(), and makes net.Server itself an async iterable.

Let’s try something fun and build a small TCP chat server. Each connected client can send a line of text, and the server forwards it to every other client, prefixed with the sender’s connection ID:

import { listen } from 'node:net/promises'

import { createInterface } from 'node:readline'

const ac = new AbortController()

const server = await listen({

port: 8124,

host: '127.0.0.1',

signal: ac.signal,

})

server.maxConnections = 10

const clients = new Map()

async function handleConnection(socket) {

const clientId = `${socket.remoteAddress}:${socket.remotePort}`

const lines = createInterface({ input: socket, crlfDelay: Infinity })

clients.set(clientId, socket)

// Close the line iterator even if the connection ends abruptly.

socket.once('close', () => lines.close())

socket.on('error', (error) => {

console.error(`${clientId}:`, error.message)

lines.close()

})

socket.write(`Connected as ${clientId}\n`)

console.log(`${clientId} joined`)

try {

for await (const message of lines) {

for (const [otherId, otherSocket] of clients) {

if (otherId !== clientId && !otherSocket.destroyed) {

otherSocket.write(`${clientId} > ${message}\n`)

}

}

}

} finally {

clients.delete(clientId)

lines.close()

socket.destroy()

console.log(`${clientId} left`)

}

}

process.once('SIGINT', () => {

ac.abort()

for (const socket of clients.values()) socket.destroy()

})

console.log('Chat listening on 127.0.0.1:8124. Press Ctrl+C to stop.')

for await (const socket of server) {

// Each handler stays active for the lifetime of its connection.

void handleConnection(socket).catch((error) => {

console.error('Connection handler failed:', error)

socket.destroy()

})

}

Run the server from the companion repo:

node 03-net-promises/net-promises.js

Then open two or three other terminals and run this command in each (with netcat installed):

Each terminal receives its connection ID, for example Connected as 127.0.0.1:54321. Type a message and press Enter. The other terminals receive a line such as 127.0.0.1:54321 > Hello everyone!. The server does not echo messages back to their sender. Press Ctrl+C in a client terminal to disconnect, or in the server terminal to close the chat and all active connections.

With three netcat clients connected, each terminal receives the other clients’ messages:
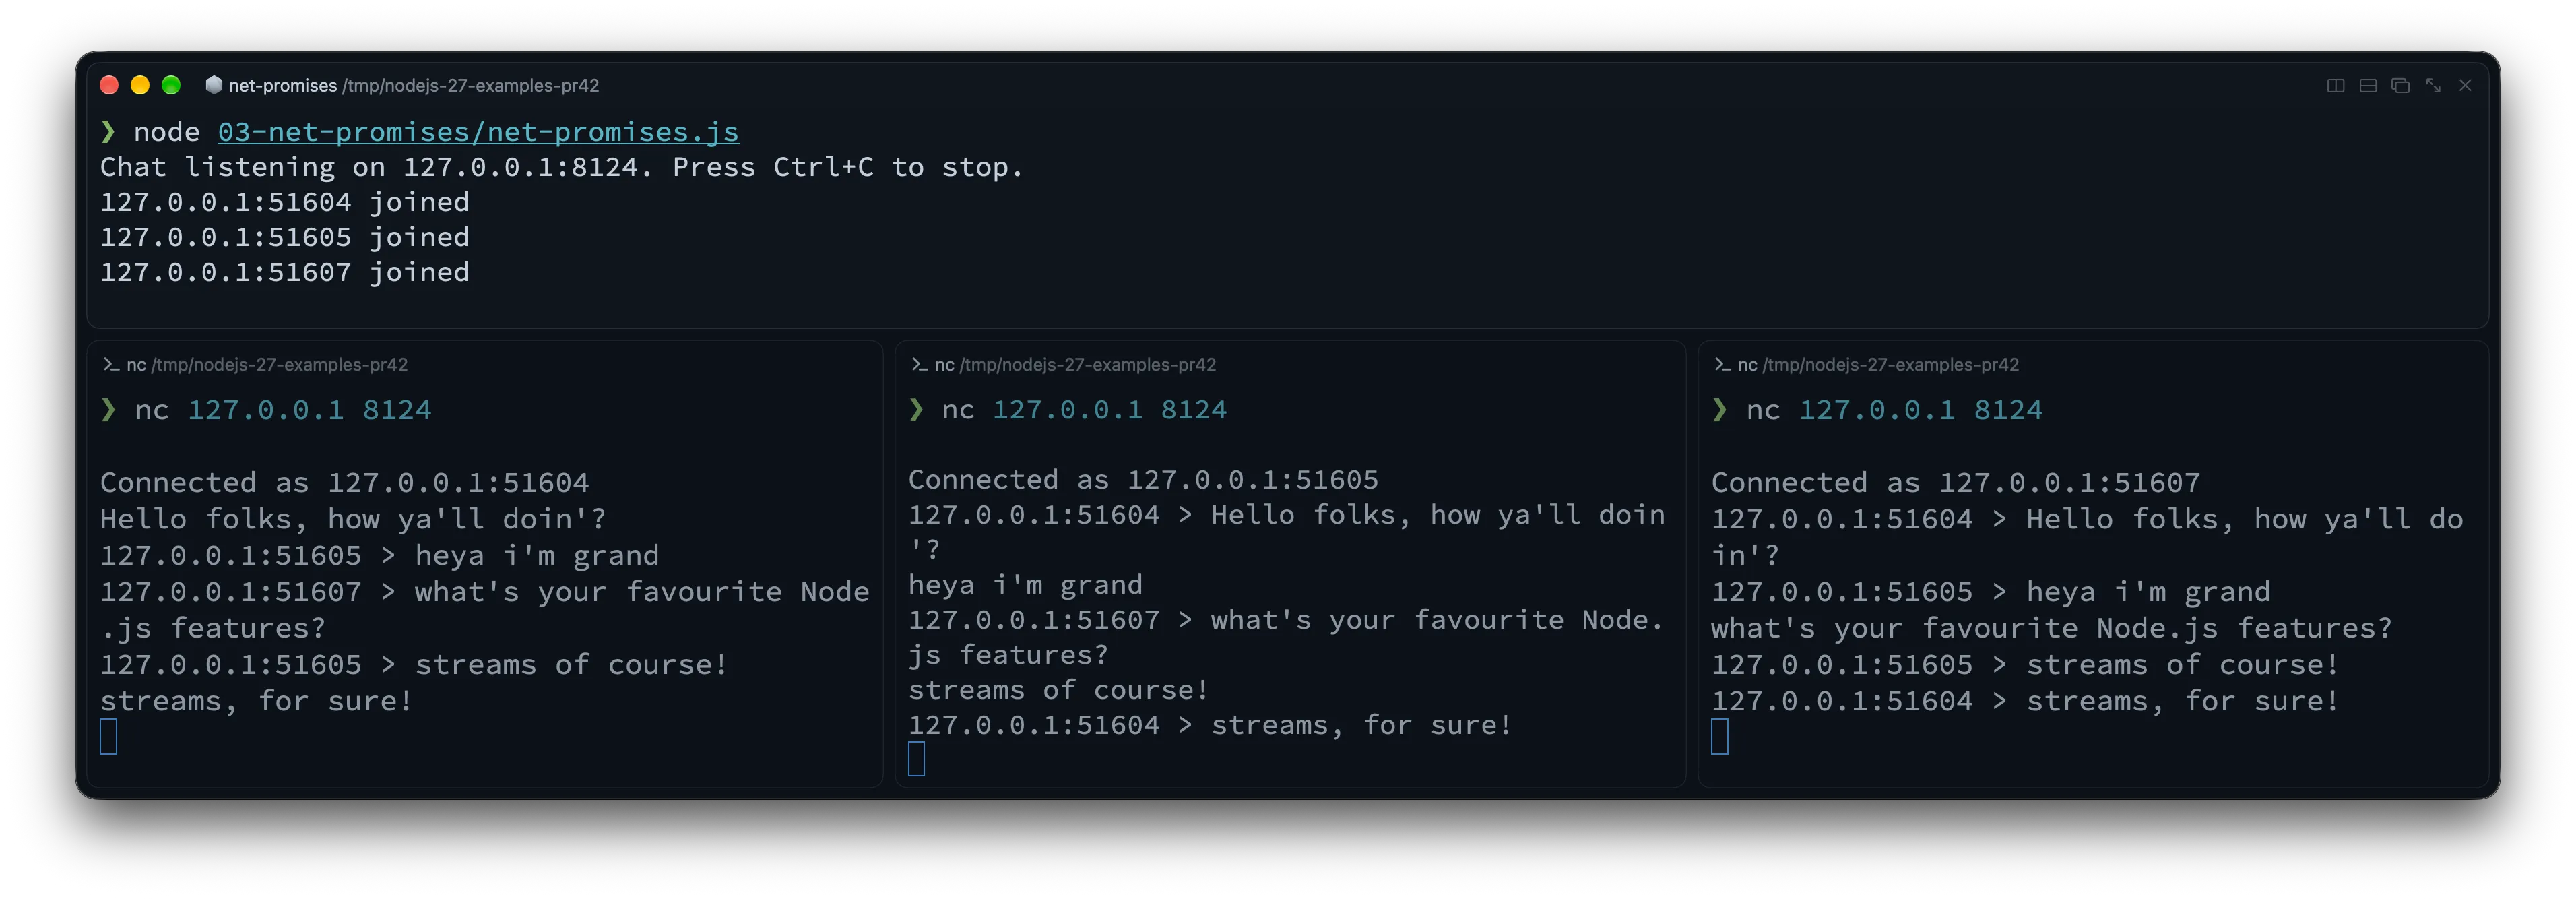
A TCP chat server above three netcat clients exchanging messages, with each received message prefixed by the sender's address and port

listen() resolves once the server is listening. The clients map tracks active sockets by their remote address and port, which distinguish connections to this server. These are connection labels, not permanent user identities: reconnecting can give a client a different port.

Inside each handler, readline turns the socket’s byte stream into lines. TCP chunks do not correspond to messages: a line may arrive in several chunks, or one chunk may contain several lines. Each completed line is broadcast to every other active socket. The finally block removes disconnected clients and closes their resources.

The outer connection loop starts each handleConnection(socket) call without awaiting it. That lets it accept the next client while earlier handlers wait for messages. Each handler still awaits its own incoming lines, so clients can remain connected and chat concurrently. The .catch() handles rejected handler promises; socket errors are handled separately, and server.maxConnections = 10 caps open connections for this demo.

Virtual File System (node:vfs) is now unflagged

Testing code that reads configuration files often means mocking node:fs or creating temporary directories and cleaning them up afterward. Bundling assets or templates into an archive poses a related problem: how can your application read them through its usual node:fs calls?

The new node:vfs (Virtual File System) module was originally introduced behind --experimental-vfs, and in Node.js 27 it is unflagged and available out of the box (though still marked Experimental Stability 1 while the API settles).

With node:vfs, you can create an isolated, in-memory file system with vfs.create(), populate it using standard fs-style methods, and mount it so regular node:fs operations (and import / require()) can read from it directly. VirtualFileSystem also supports Explicit Resource Management (using), which unmounts it when execution leaves the block:

import { readFile } from 'node:fs/promises'

import { join } from 'node:path'

import vfs from 'node:vfs'

async function loadAppConfig(configDir) {

const raw = await readFile(join(configDir, 'app.json'), 'utf8')

return JSON.parse(raw)

}

// Create an in-memory VFS that automatically unmounts at the end of the block

{

using memoryFs = vfs.create()

memoryFs.mkdirSync('/etc/myapp', { recursive: true })

memoryFs.writeFileSync(

'/etc/myapp/app.json',

JSON.stringify({ env: 'test', featureFlags: ['vfs'] }),

)

// Mount into Node's reserved virtual namespace (e.g. /dev/null/vfs/1)

const mountPoint = memoryFs.mount()

// Regular node:fs functions can now read from the mounted path!

const config = await loadAppConfig(join(mountPoint, 'etc/myapp'))

console.log('Loaded from VFS:', config)

}

// memoryFs is automatically unmounted here!

memoryFs.mount() mounts the virtual file system under a reserved namespace (path.join(os.devNull, 'vfs'), such as /dev/null/vfs/1 on POSIX), so a virtual mount can never accidentally shadow or overwrite real files on your disk. If you want to compare this with working on real files, check out our guide on reading and writing files in Node.js.

You can also use node:vfs through --vfs-load on the CLI without an experimental flag:

node --vfs-load=04-vfs/bundle

# Hello from the VFS bundle

That command mounts the companion repo’s 04-vfs/bundle directory and runs its index.js, which prints Hello from the VFS bundle. You can also pass a ZIP archive; Node.js runs its package.json "main" or index.js entry point from the mounted archive. And if you use Single Executable Applications (SEA), vfsArchive is now mounted at layer 0 and automatically available inside Worker threads too.

More Node.js Core upgrades: fs, Permissions, Test Runner, and HTTP

There are changes across the standard library too, from temporary files to HTTP server defaults.

Atomic temporary files with fs.mkstemp() and native fs.glob()

Until now, if you needed a temporary file in Node.js, your safest built-in option was fs.mkdtemp() to create a temporary directory, and then opening a file inside it. Creating a random filename yourself and calling fs.open() was error-prone and required a retry loop in case of collisions.

Node.js 27 adds APIs modeled on POSIX mkstemp(3): fs.mkstemp(), fs.mkstempSync(), and fsPromises.mkstemp(). It atomically generates a unique filename (appending six random characters to your prefix) and opens the file in a single step, returning both the path and the open FileHandle (or file descriptor fd):

import { mkstemp, rm } from 'node:fs/promises'

import { tmpdir } from 'node:os'

import { join } from 'node:path'

const prefix = join(tmpdir(), 'export-')

const { path, handle } = await mkstemp(prefix)

try {

await handle.writeFile('id,status\n1,ok\n', 'utf8')

console.log(`Wrote temporary report to ${path}`)

} finally {

await handle.close()

await rm(path)

}

The built-in fs.glob() (introduced in Node.js 22) was ported from JavaScript to native C++ in Node.js 27. The maintainers’ benchmarks show substantial speedups for some workloads, but gains vary by API and options, and one synchronous exclude-pattern workload regressed. Benchmark your own patterns before assuming a speedup.

Permission Model gets --allow-env

As we covered in our guide to environment variables in Node.js, process.env is where most applications keep their most sensitive secrets (API keys, database URLs, signing tokens). It is also the very first place a compromised dependency looks when trying to exfiltrate credentials.

Node.js 27 adds --allow-env to the Permission Model (--permission). When --permission is enabled, every environment variable not explicitly matched by --allow-env is scrubbed at process startup before any JavaScript runs (except runtime variables like PATH, HOME, LANG, and NODE_OPTIONS, plus variables explicitly loaded via --env-file):

# Only allow variables starting with PUBLIC_ or APP_

SECRET_KEY=super-secret APP_PORT=3000 \

node --permission --allow-env='PUBLIC_*,APP_*' 05-core-upgrades/permissions-env.js

# { port: '3000', secret: undefined }

Node.js also scrubs disallowed variables from the underlying OS environment block and restricts access to /proc/self/environ on Linux. Native code loaded by Node.js sees the reduced environment too. This reduces accidental exposure; the Permission Model is not a sandbox for malicious code. You can remove a variable after reading it with process.permission.drop('env', 'VARIABLE_NAME'). Keep NODE_ENV explicitly if your application uses it, since it is not preserved by default.

Built-in Test Runner: stable watch mode and Jest-style mock helpers

The built-in node:test runner has three updates:

  • Watch mode (node --test --watch) is now officially stable (Stability 2).
  • --test-forbid-only fails the test run if any test is marked with { only: true } or test.only(), so CI can catch accidental .only commits.
  • Shorthand methods on mocks: instead of wrapping simple return values or promises inside fn.mock.mockImplementation(() => ...), MockFunctionContext now has mockReturnValue(), mockResolvedValue(), mockRejectedValue(), and mockThrownValue():

import { test, mock } from 'node:test'

import assert from 'node:assert/strict'

test('mock shorthand helpers in Node.js 27', async () => {

const getDiscount = mock.fn()

getDiscount.mock.mockReturnValue(0.15)

assert.strictEqual(getDiscount(), 0.15)

const fetchUser = mock.fn()

fetchUser.mock.mockResolvedValue({ id: 42, name: 'Luciano' })

assert.deepStrictEqual(await fetchUser(), { id: 42, name: 'Luciano' })

const failSync = mock.fn()

failSync.mock.mockThrownValue(new Error('Invalid token'))

assert.throws(() => failSync(), /Invalid token/)

})

Smarter HTTP & HTTP/2 defaults

These three HTTP changes affect production web servers:

  1. http.Server keepAliveTimeout increased from 5 seconds to 65 seconds: Running a Node.js HTTP server behind an AWS Application Load Balancer (ALB), Nginx, or Cloudflare can produce intermittent 502 Bad Gateway errors when the proxy keeps an upstream connection available longer than Node.js keeps it open. AWS ALB, for example, defaults to a 60-second idle timeout, while Node.js historically set keepAliveTimeout to 5 seconds (5000 ms). If Node.js closes an idle socket just as the proxy reuses it, the forwarded request can fail with a 502. The actual socket timeout also includes keepAliveTimeoutBuffer (1 second by default). The new default keepAliveTimeout of 65 seconds (65000 ms) exceeds a 60-second proxy timeout. Check your proxy’s actual idle timeout and configure Node’s timeout to exceed it; 65 seconds does not cover every proxy configuration.
  2. req.headers and req.trailers now have a null prototype: The header dictionaries on incoming requests no longer inherit from Object.prototype (Object.getPrototypeOf(req.headers) === null), matching the existing behavior of req.headersDistinct and req.trailersDistinct. Only these header objects lose their prototype: req itself is still a regular IncomingMessage. We explain the reasoning just below, and the breaking changes section shows what to do if your code calls req.headers.hasOwnProperty(...).
  3. Larger HTTP/2 window sizes: node:http2 increased its default flow-control window sizes and trimmed per-request callback overhead, improving throughput on high-bandwidth HTTP/2 connections without manual tuning.

If you are curious why this change was made: it seems a bit weird on the surface, right? Why would Node.js remove the prototype from an otherwise ordinary object?

req.headers is a dictionary: the keys are header names chosen by whoever sent the request, and the values are whatever they sent. An ordinary JavaScript object is a poor fit for that kind of data, because it inherits properties from Object.prototype that have nothing to do with what you stored in it:

const ordinary = {}

console.log(ordinary.constructor === Object) // true

console.log(ordinary['__proto__'] === Object.prototype) // true

const headers = { __proto__: null }

console.log(headers.constructor) // undefined

console.log(headers['__proto__']) // undefined

headers['__proto__'] = 'some header value'

console.log(headers['__proto__']) // 'some header value'

console.log(Object.getPrototypeOf(headers)) // null

Our empty ordinary object already “has” a constructor, inherited from its prototype. __proto__ is even more surprising: Object.prototype defines an accessor with that name, so reading it returns the prototype, and assigning to it tries to change the prototype instead of storing a value. Both names are already lowercase, which matters here because Node.js lowercases incoming header names. A client can send a constructor or __proto__ header, and it arrives under exactly that key.

Notice that the example uses __proto__ in two different ways. { __proto__: null } is special object-literal syntax that creates the object with no prototype at all (Object.create(null) does the same thing, and the new Node.js code uses the literal form). The later headers['__proto__'] = ... is an ordinary assignment: with no inherited __proto__ setter to intercept it, it simply stores an own property, like any other key.

That’s the motivation in PR #62900, by Matteo Collina. Besides consistency with the *Distinct APIs, its commit message says the change “Fixes prototype pollution concerns where headers like __proto__ could be interpreted as prototype manipulation.” My reading is that the goal is clean dictionary semantics: a key exists in req.headers only if the request sent it.

The March 2026 security releases already included a real bug of this kind. CVE-2026-21710 was a denial-of-service flaw in req.headersDistinct, and it went like this:

  1. A request arrives with a header named __proto__.
  2. The application accesses req.headersDistinct.
  3. While building the dictionary, the lookup dest['__proto__'] resolves to the inherited Object.prototype instead of undefined.
  4. The accumulation logic calls .push() on that value, which isn’t an array.
  5. The resulting TypeError can crash the process if nothing catches it.

Because the exception is thrown synchronously inside a property getter, an 'error' event listener can’t catch it. The fix initialized the headersDistinct and trailersDistinct objects with { __proto__: null }, which is the behavior PR #62900 later extended to headers and trailers. The advisory covers headersDistinct only, so it doesn’t mean req.headers had the same crash. The bug also stopped at crashing the process: a header couldn’t use it to modify Object.prototype globally. And a null-prototype object removes inherited-property hazards only where the headers are created. If you merge headers into an ordinary object, that target still has the inherited __proto__ accessor.

Under the hood: V8 15.6, the 4 GB Heap Default, and OpenSSL 4.1

Node.js 27 also updates its engine and bundled dependencies. Most of the V8 details below come from Joyee Cheung’s Notable V8 changes from Node.js 26 to 27 (Alpha) on the Node.js blog, which is worth reading in full if you maintain performance-sensitive code or native tooling:

  • Default Heap Limit up to 4 GB on mid-sized machines: When --max-old-space-size is not specified, V8 now sets the default old-generation heap limit to half of physical memory (or container cgroup memory), clamped between 256 MB and 4 GB. Previously, machines with less than 15 GB of RAM were capped at 2 GB. On an 8 GB container or VM, the default old-generation limit therefore rises from 2 GB to 4 GB (and on a 6 GB machine, from 2 GB to 3 GB). These are old-generation limits, not limits on the process’s total memory use.

  • Buffer and ArrayBuffer memory affects garbage collection scheduling: Memory held by Buffer and ArrayBuffer instances is now included in V8’s global allocation limit. If your app allocates large off-heap buffers (for example, image processing or large file buffers), this affects when garbage collection is scheduled. The global allocation limit is distinct from the old-generation heap limit and does not impose a hard cap on the process’s total memory.

  • Slightly more memory per worker and per native object: Each V8 isolate (the main thread and every worker thread) uses about 180 KB more for property lookup caches, and every JavaScript object that wraps a native resource (a socket, file handle, stream, hash, or blob) may use about 16 bytes more on the heap and about 50 bytes more outside it. That’s negligible for most apps, but it adds up if you spawn many workers or hold many open sockets.

  • Fewer hard crashes on fatal errors: More fatal V8 errors now go through Node.js’s fatal error handling before aborting, so --report-on-fatalerror can produce a diagnostic report in cases that previously aborted without one. Some extreme inputs (overly long template literals, classes with too many elements, a regexp too large to compile) now throw a RangeError instead of crashing the process. The V8 post is explicit that this isn’t guaranteed, so don’t build program logic around it.

  • V8 15.6 performance improvements:

    • Array.prototype.sort() now uses PowerSort instead of TimSort for large arrays (still stable, with better performance on tricky input distributions).
    • await on an already-fulfilled Promise is faster and allocates less, and async generators are around 6% faster on the async-fs JetStream3 benchmark.
    • Reading properties from objects with many (or deleted) properties is about 10% faster on JetStream3’s richards and about 20% faster on espree-wtb.
    • JSON.parse() is faster on some inputs, such as payloads with many strings or arrays of objects that share the same shape.
    • Worst-case garbage collection pauses dropped from about 45 ms to about 10 ms in V8’s benchmarks.
    • Regexps are now compiled to machine code the first time they run instead of after a warmup. Regexps that run many times can get faster, while one-off regexps may get slower because they pay the compilation cost up front.

    These numbers come from V8’s own benchmarks, and the impact varies with platform, workload, and build configuration. Measure your application before counting on a speedup.

    • Intl.Locale.prototype.variants is now available to inspect locale variants (for example, new Intl.Locale('sl-rozaj-biske').variants returns 'biske-rozaj').
  • OpenSSL 4.1.0, Undici 8.12, SQLite 3.54, and npm 12.1.0: Node.js 27 upgrades its bundled cryptography to OpenSSL 4.1.0, strips out all legacy OpenSSL 1.x compatibility shims and engine APIs, bumps npm to 12.1.0, and updates NODE_MODULE_VERSION to 153.

Heads-up: Node.js 27 breaking changes

The Alpha window gives you time to check for breaking changes before the stable release. Most applications won’t encounter all of these, but check your code and dependencies for the following changes.

As we saw in the HTTP section, the header dictionaries no longer have a prototype. Normal property access (req.headers['content-type']), destructuring, and Object.keys() work as before. What breaks is calling methods inherited from Object.prototype: req.headers.hasOwnProperty('authorization') now throws a TypeError (and calling a method looked up on a dictionary of external data was never a good idea anyway).

Replace it with Object.hasOwn(req.headers, 'authorization'), which doesn’t rely on the object’s prototype and works on both Node.js 26 and 27. Please don’t “fix” this by restoring Object.prototype on the headers object. The in operator still works on null-prototype objects, but the updated Node.js docs advise against using it here, and Object.hasOwn() expresses the own-property check you actually mean.

This runnable example shows both the failure and the fix. Keep in mind that checking for a header’s presence does not authenticate its value:

import { createServer } from 'node:http'

import { once } from 'node:events'

import assert from 'node:assert/strict'

const server = createServer((req, res) => {

assert.strictEqual(Object.getPrototypeOf(req.headers), null)

assert.throws(() => req.headers.hasOwnProperty('authorization'), TypeError)

// Check for the header without relying on Object.prototype.

const hasAuthorization = Object.hasOwn(req.headers, 'authorization')

res.end(

hasAuthorization

? 'Authorization header present'

: 'No authorization header',

)

})

server.listen(0, '127.0.0.1')

await once(server, 'listening')

try {

const { port } = server.address()

const response = await fetch(`<a href="http://127.0.0.1:" rel="nofollow">http://127.0.0.1:</a>${port}`, {

headers: { authorization: 'Bearer example' },

})

console.log(await response.text()) // Authorization header present

} finally {

server.close()

}

2. Memory limits for multi-process deployments

If you run multiple Node.js processes on a 6 GB or 8 GB machine and relied on the old implicit 2 GB heap cap to keep them from starving each other, pass --max-old-space-size=2048 explicitly. Similarly, if your application holds hundreds of megabytes of Buffer data in memory alongside a large JS heap, be aware that Buffer allocations now influence V8’s global allocation limit and garbage collection scheduling.

3. V8 serialization format and larger heap snapshots

  • v8.serialize(), structuredClone(), and postMessage() use a new V8 serialization format (which adds support for TypedArrays and resizable ArrayBuffers larger than 4 GB in structuredClone() and postMessage()). Node.js 27 can still read data serialized by older Node.js versions, but older Node.js versions cannot deserialize payloads produced by v8.serialize() in Node.js 27. Watch out if you store v8.serialize() blobs in Redis or a database shared across mixed Node.js versions during a rolling upgrade!
  • Heap snapshots are ~2x larger and include full script source: v8.writeHeapSnapshot() and v8.getHeapSnapshot() now always include internal objects, numeric values, and the complete source code of scripts (instead of truncating at 1024 characters). As always, treat .heapsnapshot files as sensitive data because they may contain secrets present in your source or memory.

4. V8 behavior changes that can break tests and caches

Most V8 changes are invisible, but a few can break code that depends on exact results:

  • Math results can differ in the last bit: V8 now uses LLVM’s libm for some Math functions. For example, Math.log(3) returns 1.0986122886681096 in Node.js 26 and 1.0986122886681098 in Node.js 27. Tests that compare floating-point results against hard-coded values may fail, so compare with a tolerance instead.
  • Math.random() produces a different sequence for the same --random-seed: the generator now runs xorshift128+ directly without a cache. If your tests or fixtures pass --random-seed to get reproducible values, expect new ones (with --random-seed=42, the first value changes from 0.6159659788862542 to 0.22876995452731475).
  • Array.prototype.sort() calls your comparator a different number of times: as we saw in the previous section, V8 switched to PowerSort for bigger arrays. Sorting with a consistent comparator gives the same result, but tests that count or record comparator calls, or comparators with side effects, can behave differently.
  • Code caches are invalidated more often: v8.cachedDataVersionTag() now changes whenever Node.js applies its own patches on top of V8, not only on V8 upgrades. The built-in module compilation cache and cached data from vm.Script or vm.Module can be invalidated across Node.js patch and minor releases, so expect more cache misses if you persist that data between upgrades.

The V8 changes post lists more edge cases, including fractional getTimezoneOffset() values for historical dates and stricter take()/drop() limits on iterators.

5. Deprecations, removals, and platform changes

  • node:domain is now runtime-deprecated: Importing or using node:domain emits a runtime deprecation warning (and its internals have been ported to AsyncLocalStorage).
  • Private _http_* modules deprecated and _tls_* removed: Undocumented internal modules (_http_agent, _http_client, _http_common, _http_incoming, _http_outgoing, _http_server) are deprecated, and _tls_common / _tls_wrap have reached End-of-Life. Always import from node:http and node:tls.
  • OpenSSL engines and OpenSSL 1.x dropped: Building from source requires OpenSSL 3.0 or newer (bundled binary builds ship OpenSSL 4.1.0), and custom OpenSSL engine APIs (clientCertEngine, privateKeyEngine, crypto.setEngine()) are gone.
  • Calling Hmac.digest() multiple times is runtime-deprecated.
  • --no-experimental-websocket removed: The global WebSocket client is permanent and can no longer be disabled via CLI flag.
  • Intel macOS (darwin-x64) downgraded to experimental: Apple Silicon (darwin-arm64) remains Tier 1, while Intel macOS support is now experimental.

Should you use Node.js 27 today?

For production, the release date matters. For library authors and local experiments, there is already code to try:

  • For production workloads: If you are reading this before April 2027, keep using an LTS release. Node.js 27 is still in its Alpha testing phase during that period. It is scheduled to enter Current in April 2027 and become LTS in October 2027 (with support until April 2030). Once a stable release is available, evaluate it against your application’s support requirements.
  • For open-source library and framework authors: Add it to your CI now. As we explained in our article on the new release schedule, the Alpha channel lets maintainers catch breaking changes (like null-prototype req.headers, V8 15.6 changes, or native add-on ABI updates) months before users upgrade. The Node.js team patched npm engines checks in this Alpha so CI can accept the -alpha prerelease tag.
  • For local experimentation and learning: Try Iterator.zipKeyed(), Math.sumPrecise(), node:net/promises, and node:vfs in a side project to get familiar with the APIs.

If you want to install the Alpha side by side with your stable LTS runtime without messing up your system setup, check out our guide on 5 ways to install Node.js using version managers like fnm or nvm.

Wrapping up

Node.js 27 starts the annual release schedule, with every major version going on to LTS. Its first Alpha includes V8 15.6, node:net/promises, an unflagged node:vfs, fs.mkstemp(), and --allow-env.

I’d start by trying Iterator.zipKeyed() and Iterator.prototype.join() in a data-transformation script. They let you process parallel collections lazily without collecting intermediate arrays.

For the full list of commits and low-level details, check out the official Node.js 27.0.0-alpha.0.0.0 release notes and the companion post on Notable V8 changes from Node.js 26 to 27 (Alpha).

Thanks to the Node.js releasers, V8 maintainers, and contributors who worked on this first Alpha and the new release schedule.

See you in the next article!

Frequently Asked Questions

Why did Node.js 27 start with an Alpha release in October 2026?

Node.js 27 is the first version under the new Node.js release schedule. Instead of two major releases per year, Node.js now ships one major release every April, preceded by a six-month Alpha testing phase starting in October.

Will Node.js 27 become an LTS release even though 27 is an odd number?

Yes. Under the new release schedule, the old odd/even rule is gone and every yearly major release becomes LTS. Node.js 27 will enter Current in April 2027, move to LTS in October 2027, and be supported until April 2030.

What are the biggest JavaScript features in Node.js 27?

Thanks to V8 15.6, Node.js 27 ships Iterator.zip(), Iterator.zipKeyed(), Iterator.prototype.join(), Iterator.prototype.includes(), Math.sumPrecise(), and Intl.Locale.prototype.variants enabled by default.

How did the default memory limit change in Node.js 27?

When --max-old-space-size is not set, V8 now defaults to half of physical memory clamped between 256 MB and 4 GB (meaning an 8 GB machine gets a 4 GB heap instead of 2 GB). Additionally, memory held by Buffer and ArrayBuffer instances now counts toward V8’s global allocation limit, affecting when garbage collection runs.

Should I run Node.js 27 in production?

If you are reading this before April 2027, keep production workloads on an LTS release. Node.js 27 is still in its Alpha testing phase during that period, intended for library authors, CI pipelines, and experimentation. It is scheduled to enter Current in April 2027 and LTS in October 2027. Once a stable release is available, evaluate it against your application’s support requirements.

Read the whole story
emrox
6 hours ago
reply
Hamburg, Germany
Share this story
Delete

I Go to Olympics of 4KB Coding. - Invidious

1 Share
Read the whole story
emrox
3 days ago
reply
Hamburg, Germany
Share this story
Delete

Kugelblitz

1 Share

The Earth and its neighbors as a 3D globe and atlas for the Mac – maps and open geodata on real terrain.

Kugelblitz shows the Earth and its neighbors as a globe and as an atlas you fly over smoothly like a pilot, even on an M1. Imagery, road map and topographic map lie on real terrain, joined by thousands of open maps from the Library. Everything comes from freely available geodata, straight from its publishers, OpenStreetMap from the Kugelblitz tile server; you need no account.

Everything loaded stays in the cache, and Kugelblitz instances in the same network share it with each other if you wish. Status windows tell how far the view has loaded, where you are looking and where its data comes from, and every source is listed with its license in “Sources and Licenses”. Kugelblitz speaks German and English and uses the units of your choice.

Drawn maps on real terrain

The Earth on three kinds of map, as a globe and as an atlas: Imagery, road map and topographic map. The two drawn ones do not lie flat beside it but on the globe's terrain, with buildings in 3D. A scene brings back a ready-made view in one move.

More about Maps

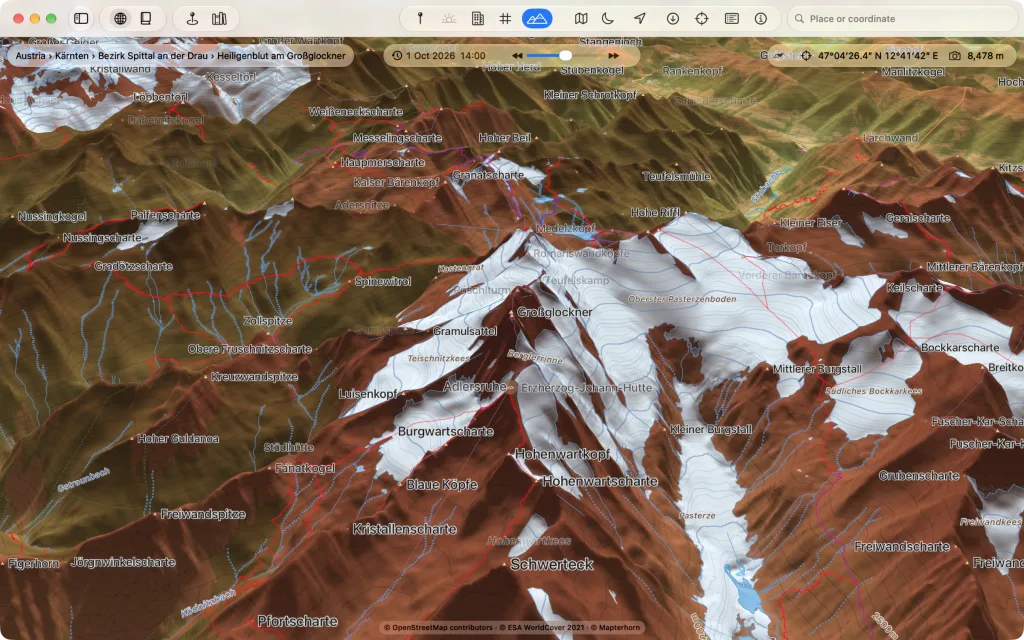
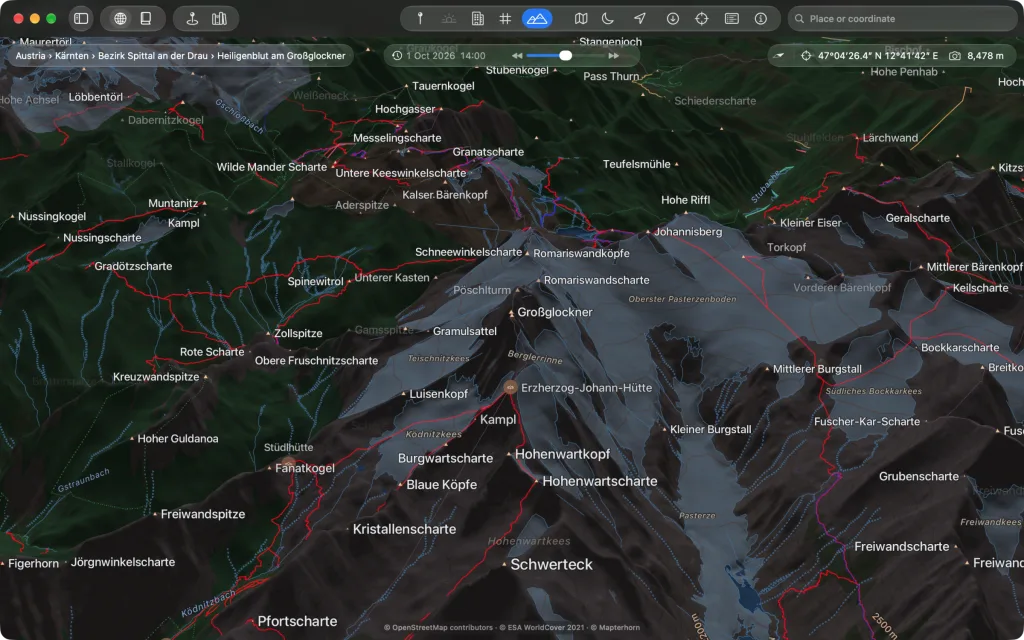
The topographic map at the Grossglockner seen at an angle, hillshading, elevation tints and contour lines lie on the terrain, glaciers white, slopes red-brown, the green lowlands behindThe topographic map at the Grossglockner seen at an angle, hillshading, elevation tints and contour lines lie on the terrain, glaciers white, slopes red-brown, the green lowlands behind

Every body flat as a printed map

Beside the globe Kugelblitz shows every body as an atlas: the same data flat in five projections, from the whole sheet to the finest images. You switch in the title bar or with ⇧⌘A.

More about Atlas

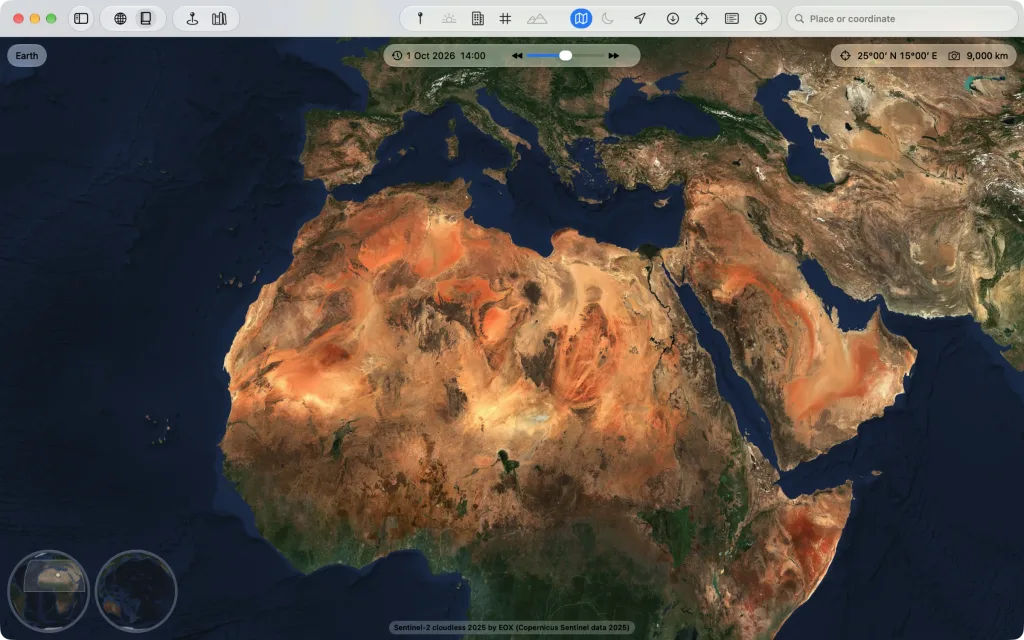
North Africa, Europe and Arabia in the atlas in Equal Earth, in the corner the two hemispheres with the area the window showsNorth Africa, Europe and Arabia in the atlas in Equal Earth, in the corner the two hemispheres with the area the window shows

Search, view and add the world's open geodata

The Library (⇧⌘B) opens directories and geoportals with map services from all over the world: aerial images, satellite images, elevation models, maps and buildings in 3D. “On the Globe” shows any service at once, and one click adds it to “My Places”.

More about Library

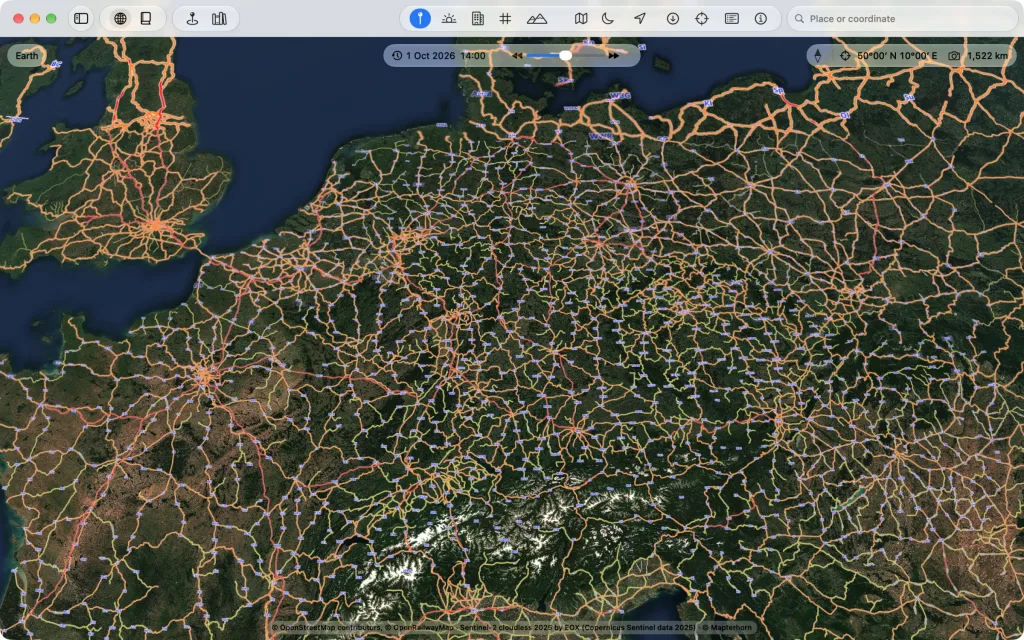
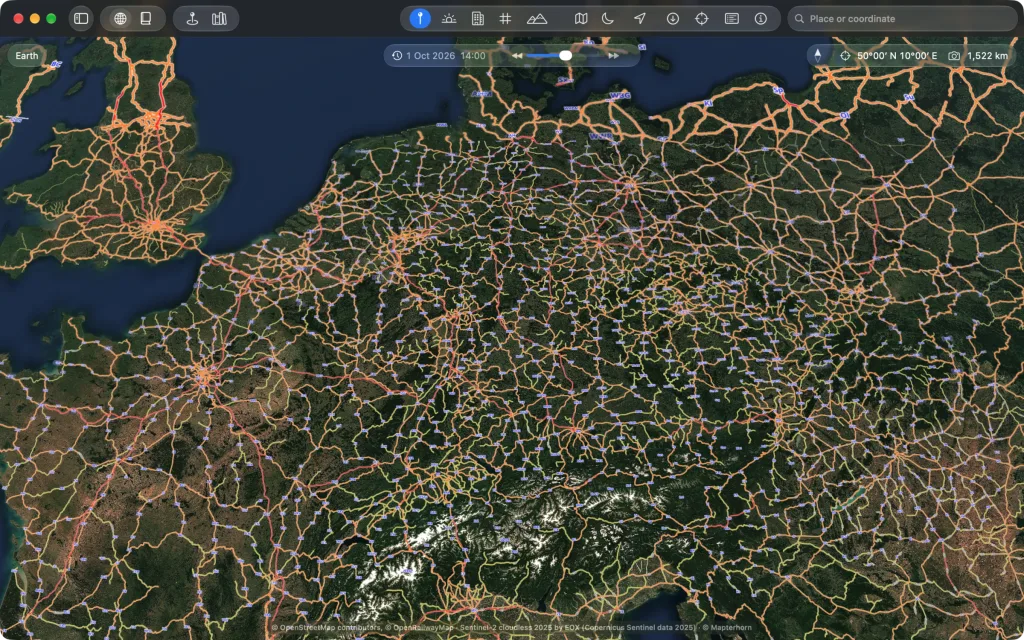
Central Europe with the railway network from OpenRailwayMap over the satellite imageCentral Europe with the railway network from OpenRailwayMap over the satellite image

All of OpenStreetMap, without a download and without regions

OpenStreetMap comes from Kugelblitz's own tile server: the whole planet, prepared for Kugelblitz, in tiles only for the area you see, at the level the distance asks for. No regions, no large download, the same everywhere on Earth.

More about Tile server

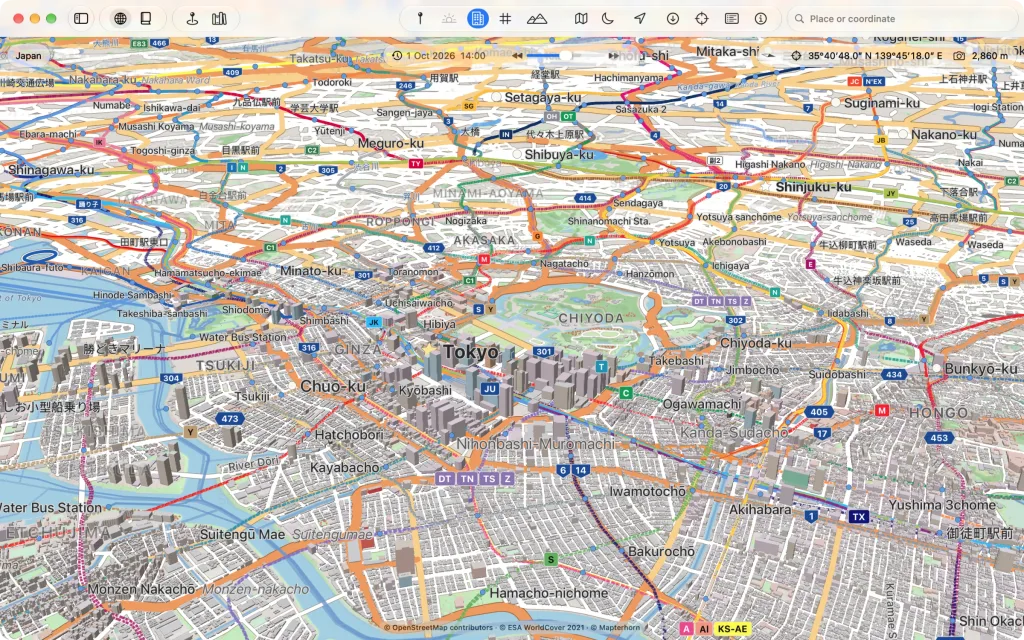
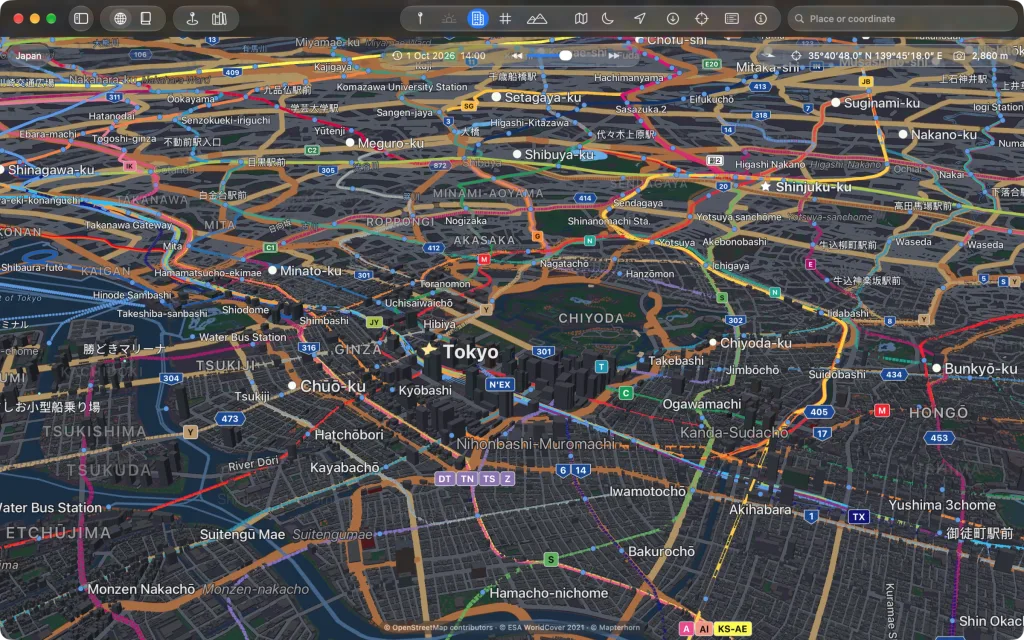
Tokyo seen at an angle on the road map with streets, railway lines, buildings and namesTokyo seen at an angle on the road map with streets, railway lines, buildings and names

Fly like a pilot with a SpaceMouse

The SpaceMouse from 3Dconnexion is Kugelblitz's control stick: all movements at once, as fine as you move the cap, without a driver. Keyboard, trackpad and mouse work as well, all at once too.

More about Flying

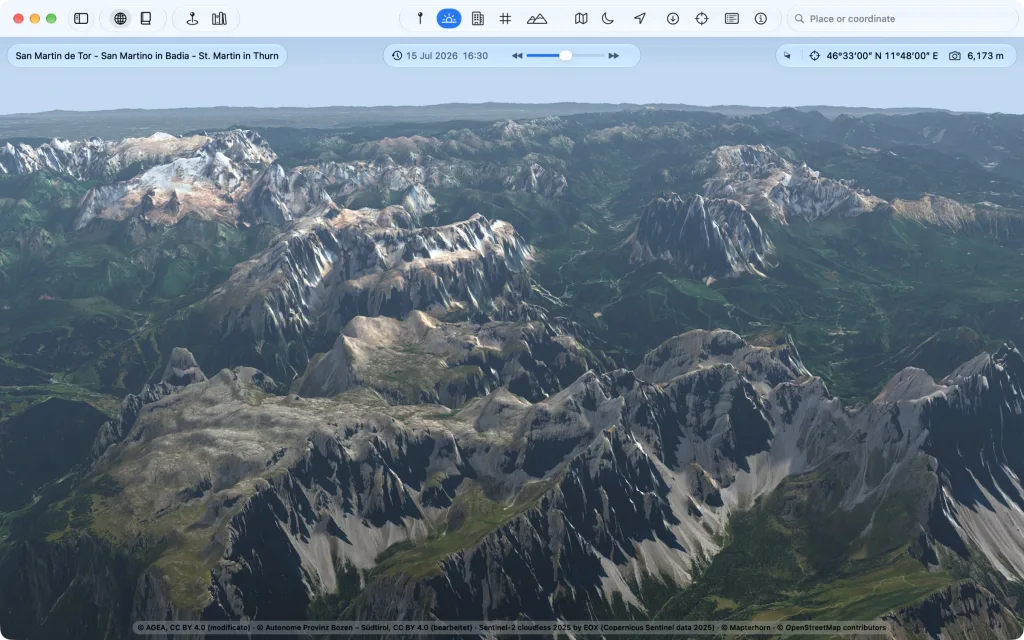
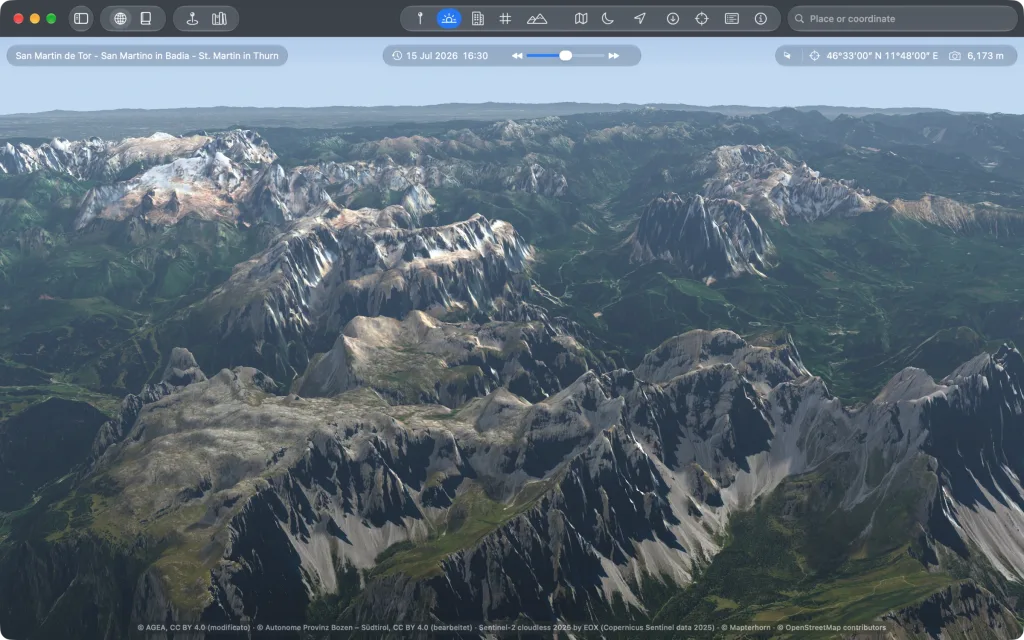
Low flight over the Puez group in the Dolomites, mountains and valleys up to the horizonLow flight over the Puez group in the Dolomites, mountains and valleys up to the horizon

Smooth, even on an M1

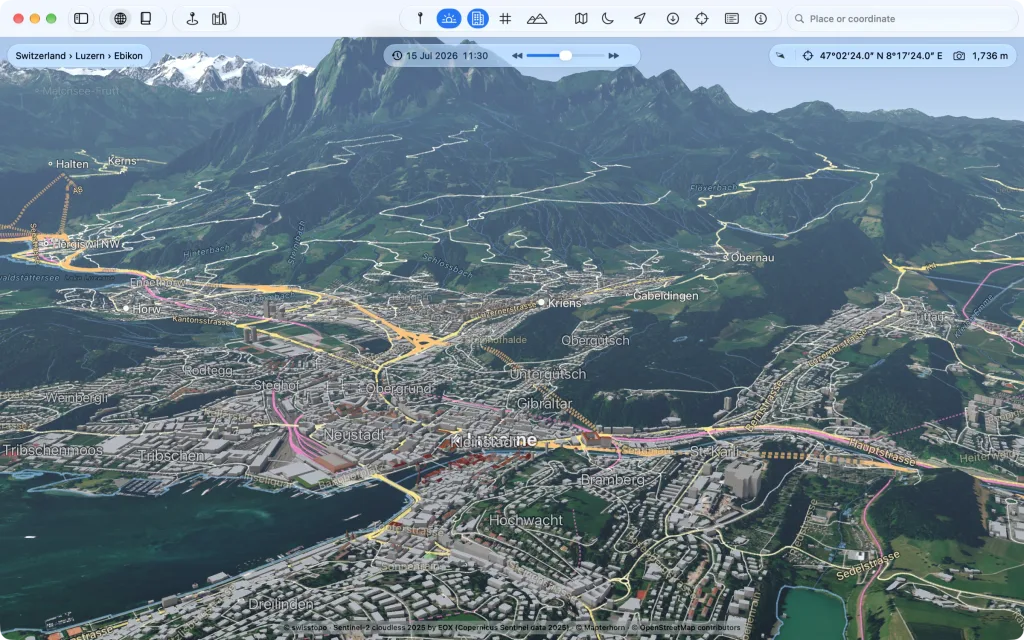
Aerial image, terrain, buildings, roads and names at once, and the flight stays smooth. Kugelblitz is made and measured on a Mac mini with M1 and 16 GB.

More about Performance

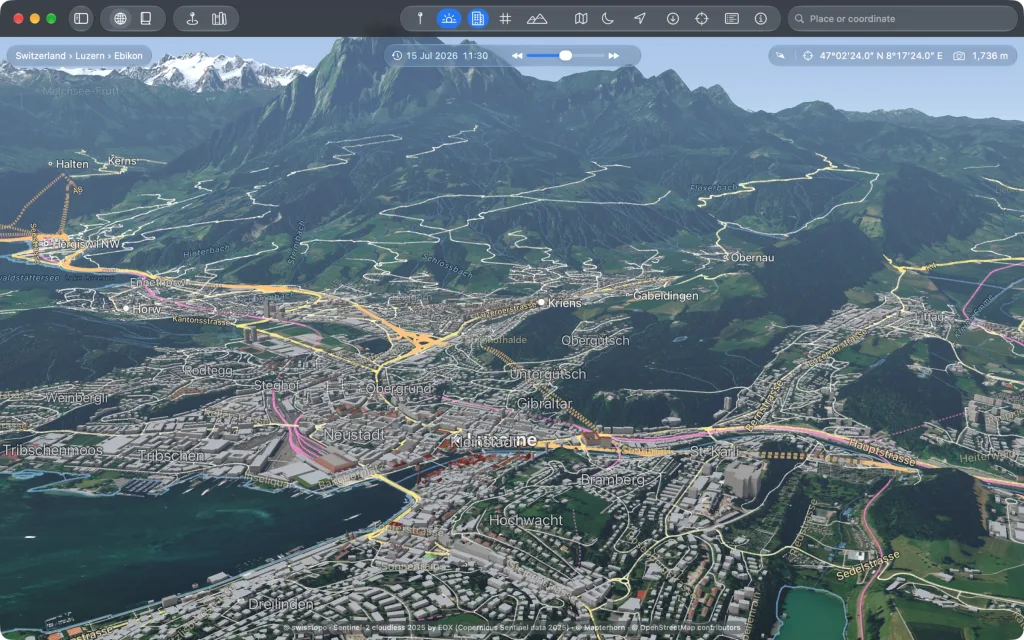
Low flight over Lucerne towards Pilatus with aerial image, terrain, buildings, roads, railway lines and names at onceLow flight over Lucerne towards Pilatus with aerial image, terrain, buildings, roads, railway lines and names at once

The Mac streams the globe into the headset

The Mac draws, the headset shows: View → “Show on Vision Pro…” (⌥⌘V) brings the globe all around you, without an app on the headset, from an M1 too. Checked with Mac and headset on 27.2.

More about Apple Vision Pro

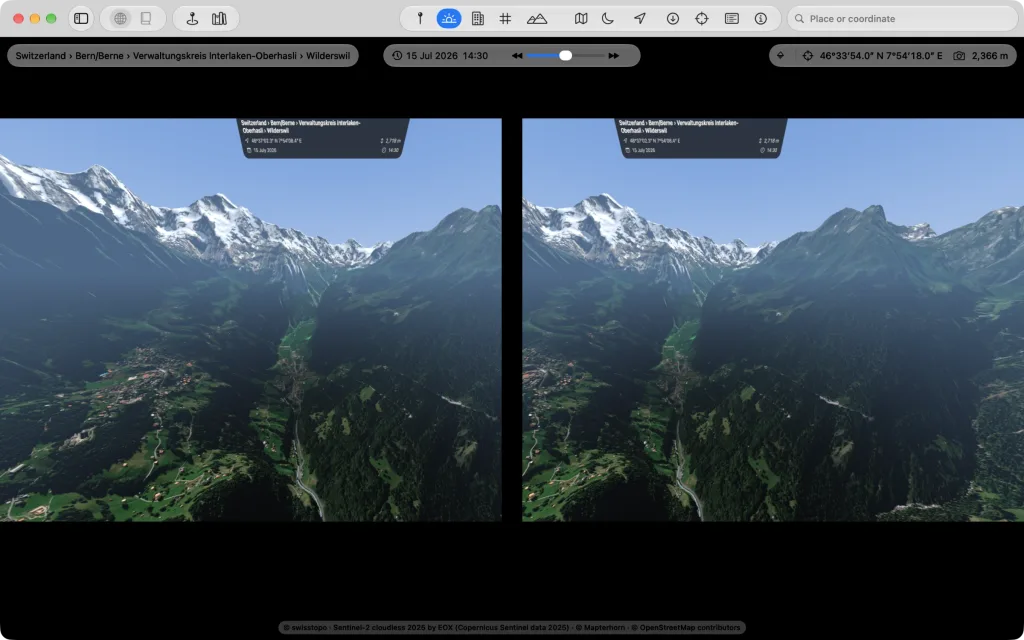
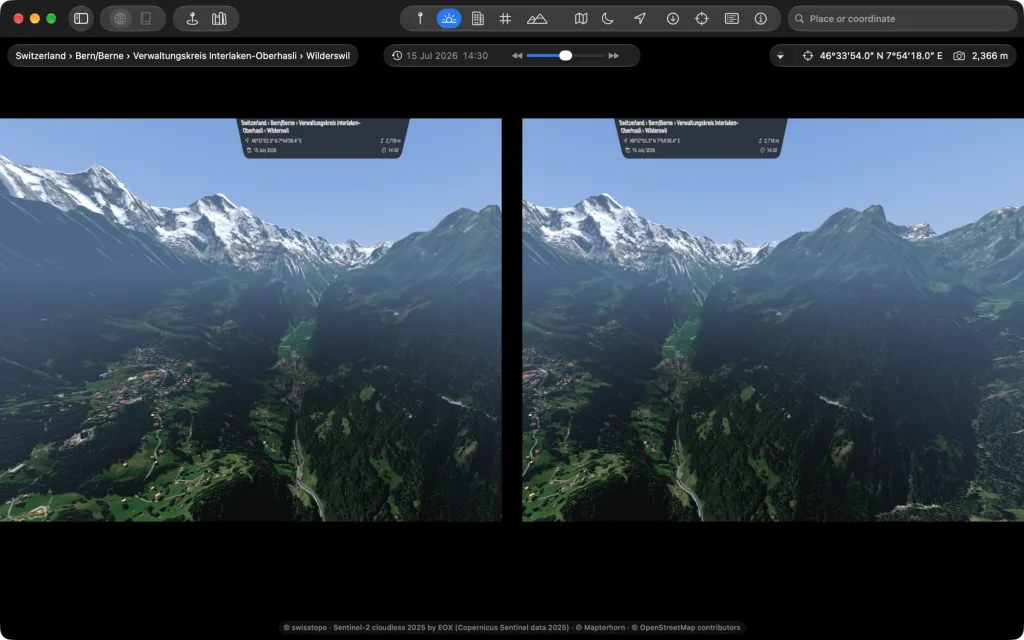
Both eyes side by side, as the Mac's window shows them while streaming, the view up the Lauterbrunnen valley to the glaciers at its head, at the top the navigation in the room; not a recording from the headsetBoth eyes side by side, as the Mac's window shows them while streaming, the view up the Lauterbrunnen valley to the glaciers at its head, at the top the navigation in the room; not a recording from the headset

What happened, where and when

Eclipses over 5,000 years, computed rather than read from tables, as well as earthquakes, eruptions, tsunamis and fireballs at their place and time. Let the time shuttle run and you see them come and go.

More about Events

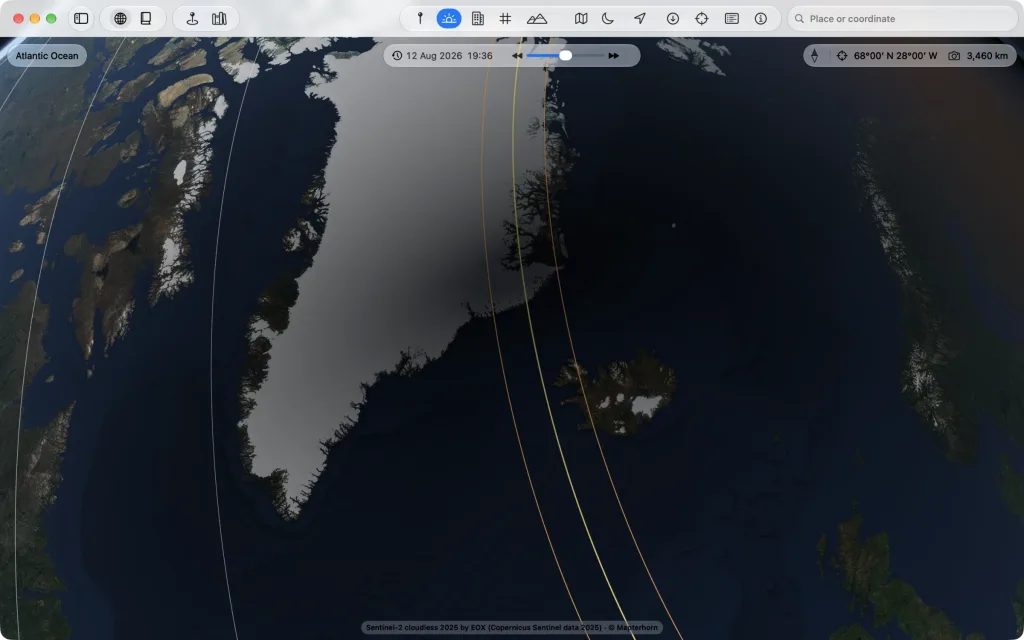
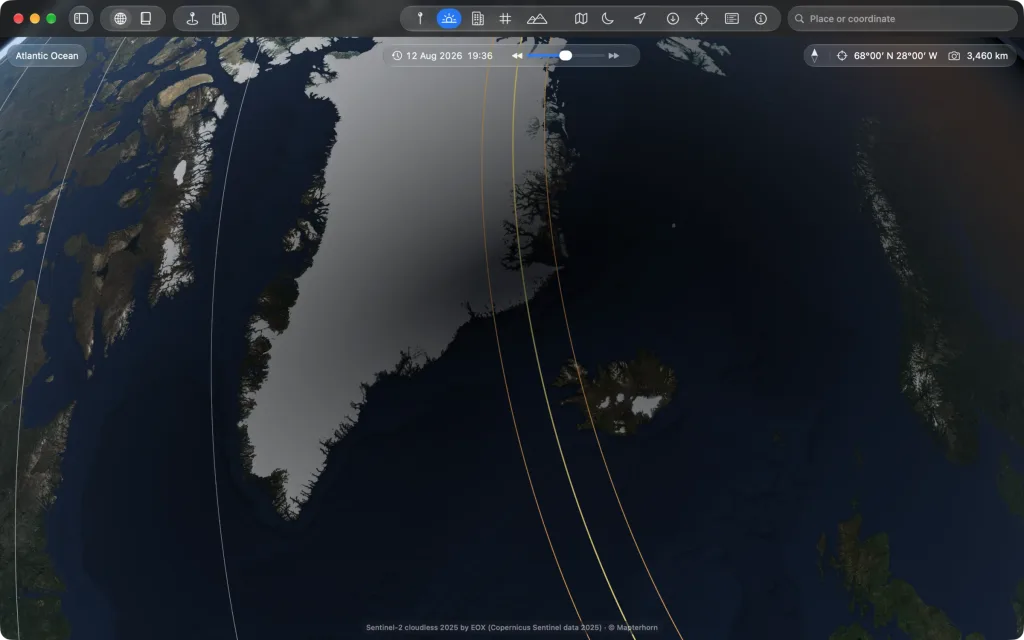
The total solar eclipse of 12 August 2026, the Moon's shadow on Greenland's east coast, with the central line, the limits of totality and the lines of equal coverageThe total solar eclipse of 12 August 2026, the Moon's shadow on Greenland's east coast, with the central line, the limits of totality and the lines of equal coverage
Read the whole story
emrox
3 days ago
reply
Hamburg, Germany
Share this story
Delete

Tree Feelings

1 Share

Tree Feelings

And more trees.

Read the whole story
emrox
3 days ago
reply
Hamburg, Germany
Share this story
Delete

Tokenizer Mono

1 Share

• ~6,000 words • 30 minute read

tokenizer-cycle-labeled

There are many tools out there that help you visualize tokens and better understand how tokenization works with large language models. OpenAI has a pretty nice one, and there are a half-dozen other ones that are also great.

They generally work by passing text through an actual tokenizer, retrieving the resulting token boundaries, and highlighting them in the browser. It's a fast, accurate and perfectly reasonable approach.

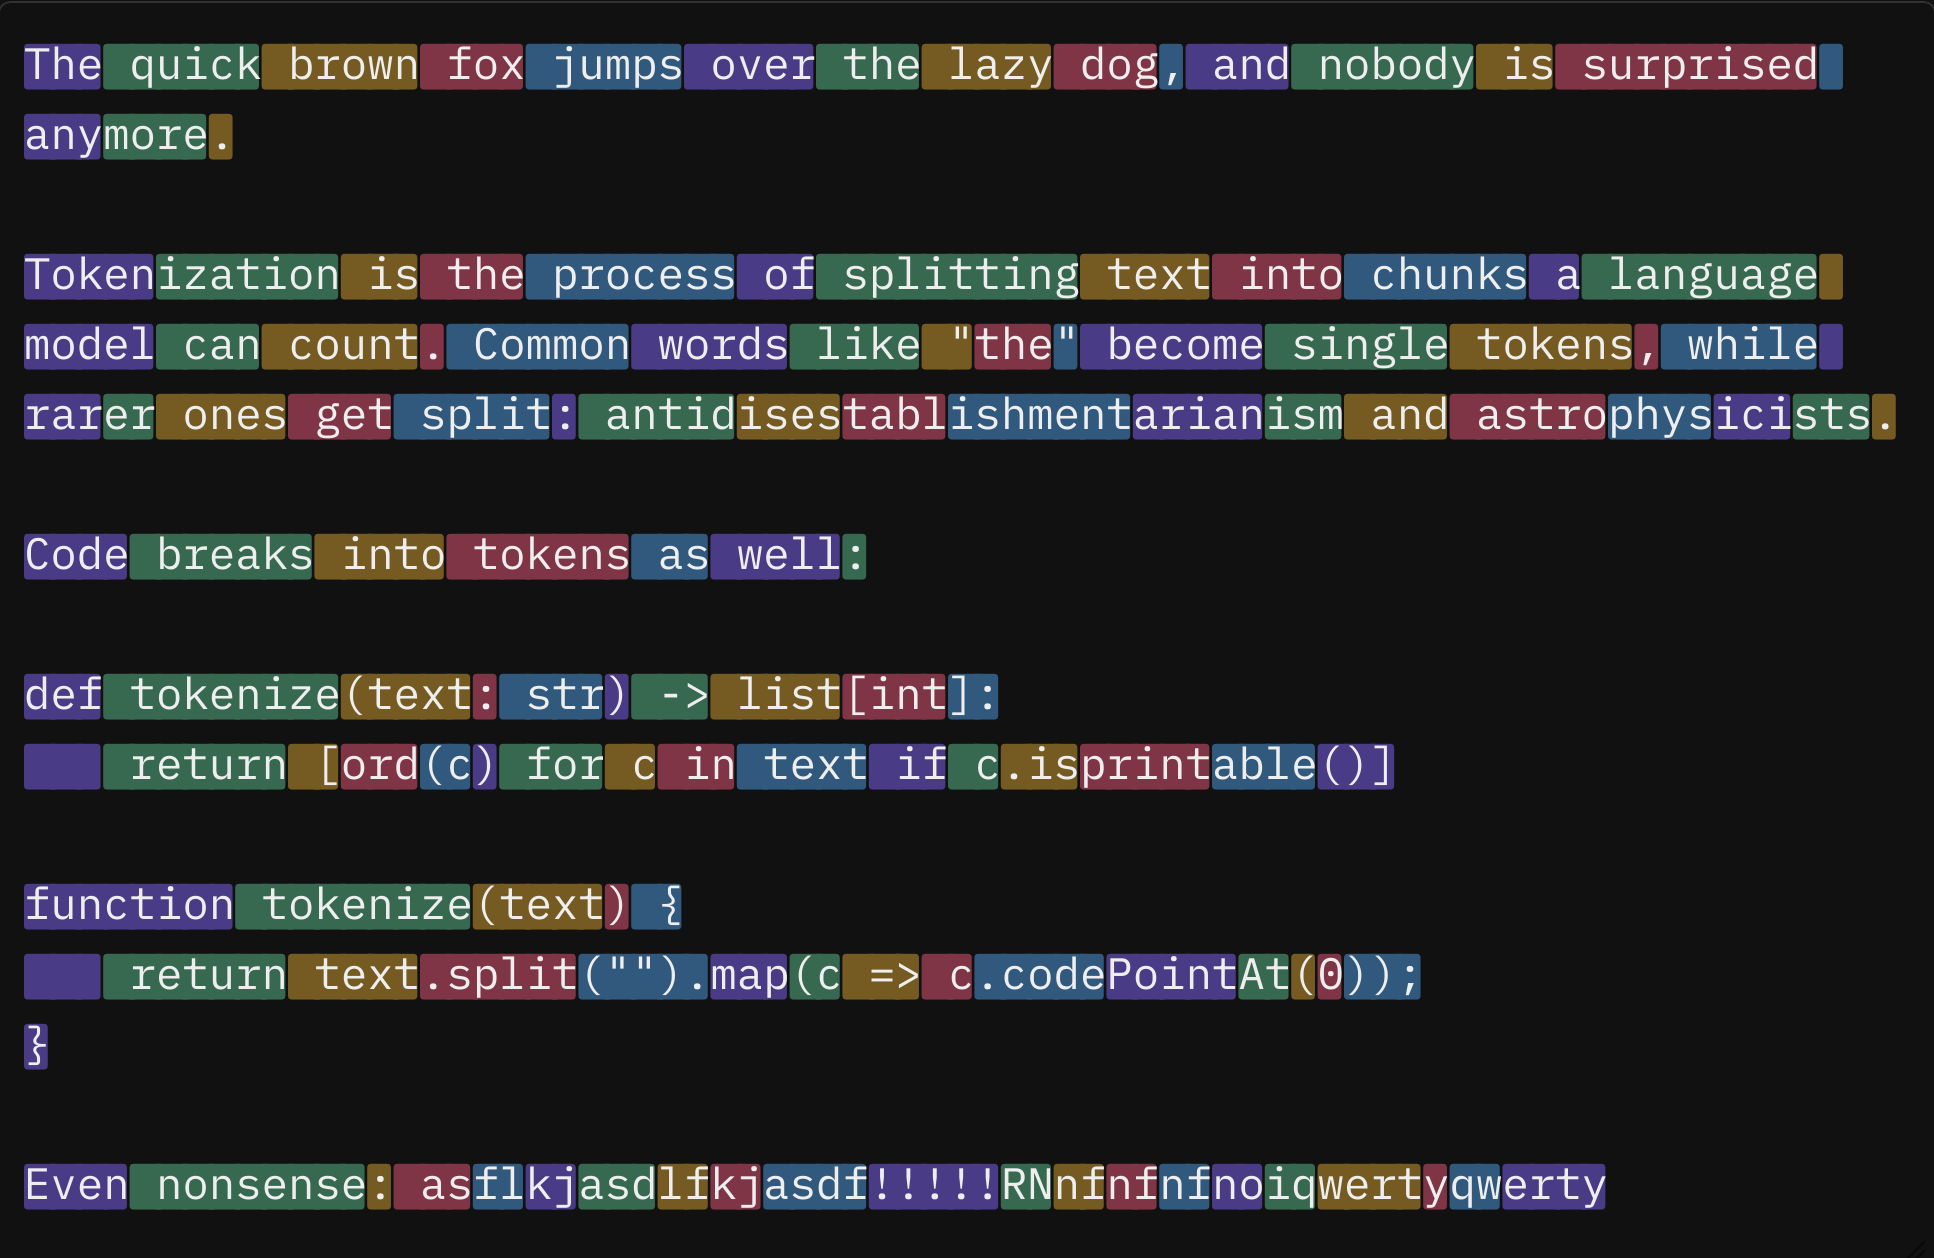
So I did the slightly unreasonable thing and made a font that uses modern font witchcraft to visualize tokens as you type them, without actually tokenizing. The code is at:

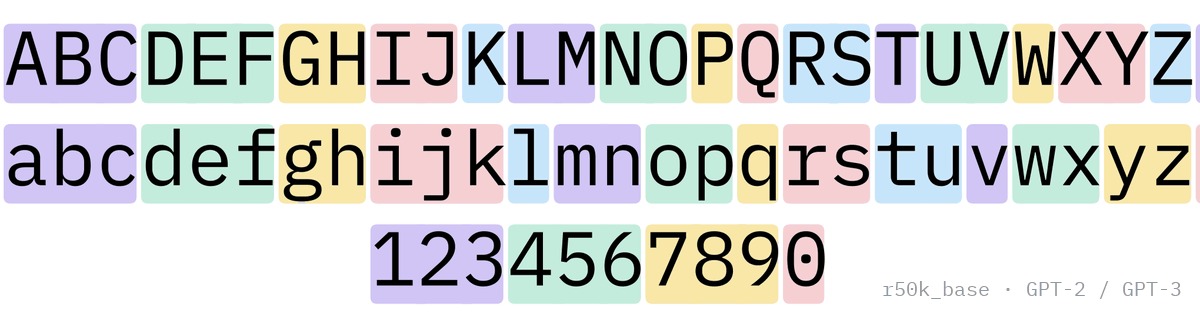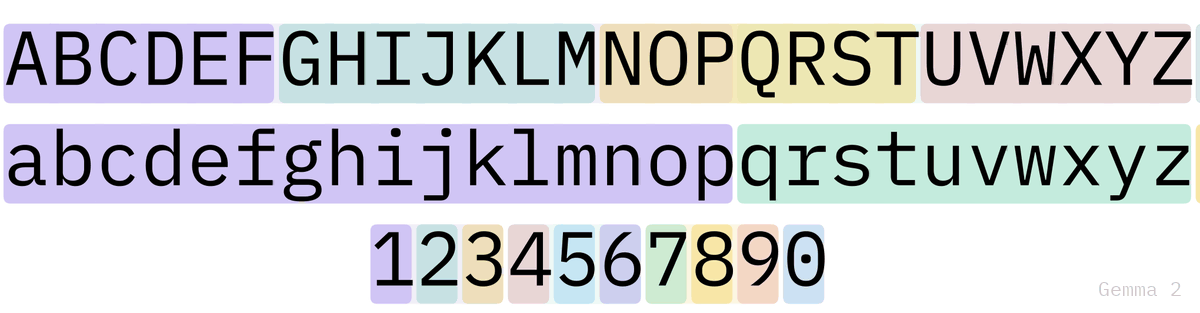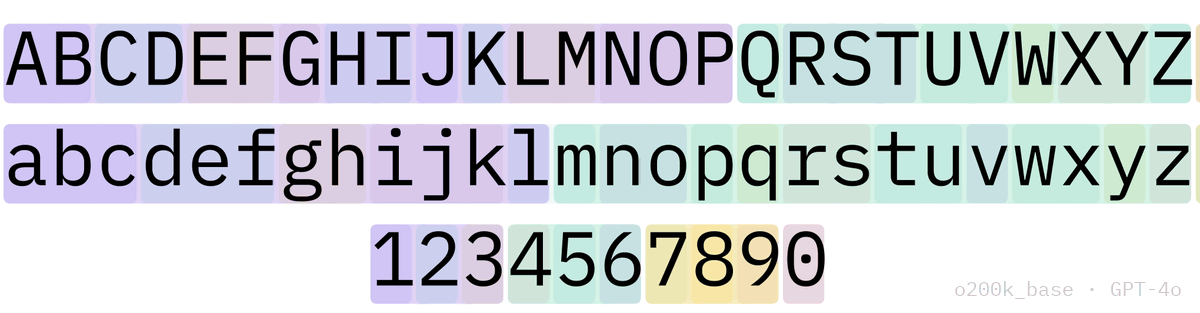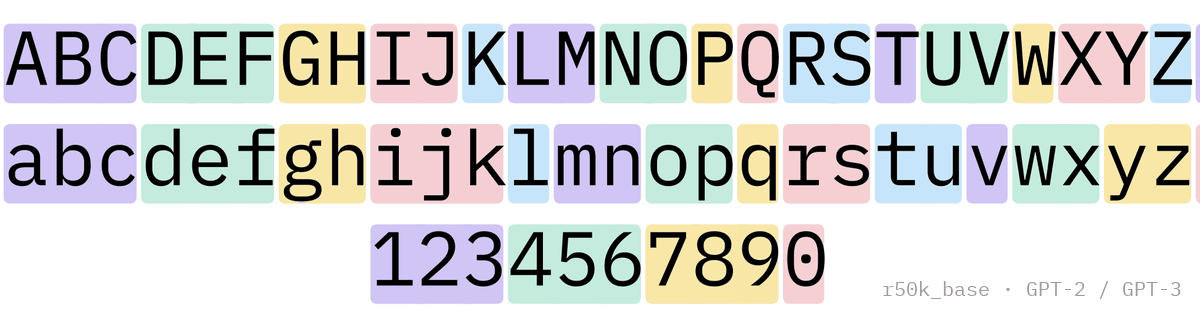
You can play with it below. Every highlight is drawn by the font. No scripting! The only JavaScript here is swapping which face is loaded.

OpenAI GPT-4, GPT-3.5, text-embedding-3; also Phi-4, OLMo 2, IBM Granite 4

Pasted image 20261101225003

What is a token?

A token is the basic unit of currency for a language model. It’s what the model actually reads and produces.

A token is generally a chunk of text: a character, word, word-part, or occasionally a longer sequence. Many modern LLM tokenizers have a fixed vocabulary of these chunks, typically somewhere between 50,000 and 250,000 entries.

And that vocabulary isn’t necessarily exclusively made up of conventional words. Common combinations of characters, punctuation, whitespace, and even sequences spanning multiple words can all earn their own entries.

Where does a vocabulary come from? Nobody writes it by hand. Almost every tokenizer in this post uses some form of byte-pair encoding (BPE), which builds the vocabulary by counting. In a simplified version of BPE, start with every character (or byte, in byte-level tokenizers) as its own token. Look through a big pile of training text for the pair of adjacent tokens that appears most often, say "t" followed by "h", and merge it into a new token "th". Now look again: maybe "th" followed by "e" is the most common pair, so "the" becomes a token.

Rinse and repeat this many thousands of times over. Every merge adds one entry to the vocabulary, and the list of merges, in the order they were learned, is saved along with it. To tokenize new text, the tokenizer breaks it into characters and replays those merges in the same order, so common words collapse into a single token and rare words stay in pieces. The exact split of a word depends on which merges rank higher, which matters later.

Over a long enough timeline, does the entirety of Alice in Wonderland become a single token? Every published version of something like the Bible? Interesting thought exercise.

While they aren't incorporating entire novels or religious texts as tokens yet (and I suspect there's a better technique that enters the room well before we push things to that scale), these vocabularies have been getting bigger! GPT-2 had 50,257 tokens; GPT-4's tokenizer has 100,277; GPT-4o's has 200,019.

Part of that growth reflects increasingly ambitious multilingual support: OpenAI's GPT-4o announcement shows the same Gujarati sentence dropping from 145 tokens to 33 under the new tokenizer, while English barely moved.

Sidenote: Rest of World has a nice article on the cost of AI for non-english languages which touches on this idea of multilingual support, tokens and how this manifests visually. I think not discussing Chinese at all—which can be more token efficient than latin script languages sometimes!—was kind of a miss.

So when something like Meta’s Muse product boasts giving you 1 billion tokens for free, that’s what we’re talking about: a billion units of text processed, not a billion words (The rule of thumb seems to have settled around 0.75 words per token, so if it helps you can multiply any token count by that and read it as words.). And depending on which tokenizer is doing the counting, that same text might consume a surprisingly different number of tokens!

Writing this makes me want to start charging in tokens (i.e. words) in my day-to-day life. Hm.

Further reading on tokens: the BPE paper, Sennrich et al. 2016; SentencePiece, Google's take, used by Llama 2, Gemma and T5; and Hugging Face's tokenizers library, which reads most of the open ones.

What is Tokenizer Mono and how does it work?

Tokenizer Mono is a font family with different faces mapped to different tokenizers. This lets you visualize the tokens as you type without an additional computation and reassembly step.

It's one big typographic family—"Tokenizer Mono" based on IBM Plex— with a style per tokenizer model. Font Book on macOS should register them as one family with twenty-eight styles.

VendorFaceUsed by
OpenAIcl100kOpenAI GPT-4, GPT-3.5, text-embedding-3; also Phi-4, OLMo 2, IBM Granite 4
o200kOpenAI GPT-4o, o1, o3, GPT-4.1, gpt-oss
p50kOpenAI Codex, text-davinci-002/003
r50kOpenAI GPT-2, GPT-3
clipOpenAI CLIP, Stable Diffusion prompts (lowercases; no whitespace tokens)
Metallama4Meta Llama 4
llama3Meta Llama 3 / 3.1 / 3.2 / 3.3; also SmolLM 3
llama2Meta Llama 2 (SentencePiece)
Googlegemma3Google Gemma 3
gemmaGoogle Gemma 1 / 2
t5Google T5 (SentencePiece Unigram, not BPE)
bertGoogle BERT (WordPiece; ## continuations approximated)
MistralmistralMistral 7B v0.3 (SentencePiece)
tekkenMistral Nemo, Mistral Small 3 (Tekken); also NVIDIA Nemotron-H, Swiss AI Apertus
AlibabaqwenAlibaba Qwen 2 / 2.5 / 3
DeepSeekdeepseekDeepSeek V3 / R1
ZhipuglmZhipu GLM-4.5
TencenthunyuanTencent Hunyuan
BaiduernieBaidu ERNIE 4.5 (SentencePiece)
ByteDanceseedByteDance Seed-OSS
01.AIyi01.AI Yi (SentencePiece)
IBMgraniteIBM Granite 3 and Granite Code (StarCoder vocabulary); also StarCoder
TIIfalcon3TII Falcon 3
falconTII Falcon
EleutherAIneoxEleutherAI GPT-NeoX, Pythia
BigSciencebloomBigScience BLOOM (multilingual)
UWsuperbpeUW SuperBPE for OLMo 2 (tokens cross word boundaries)
MoonshotkimiMoonshot Kimi K2 (tiktoken-format vocabulary)

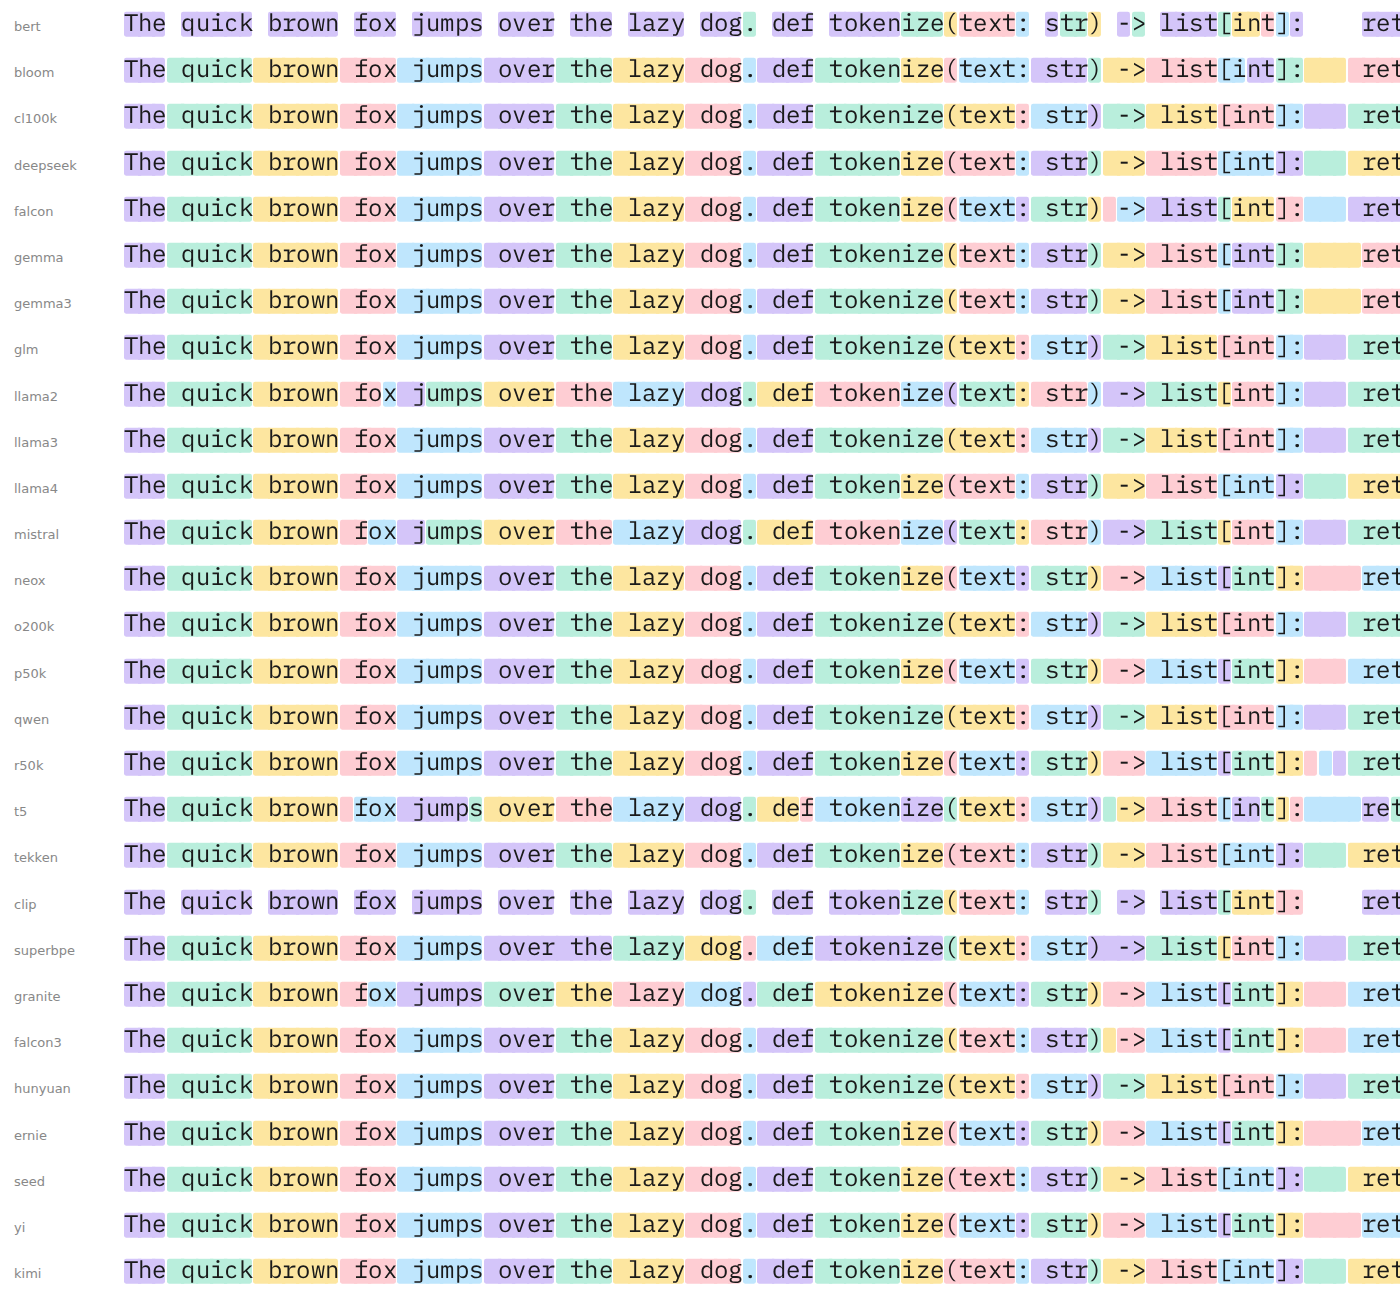
Here's the same sentence visualized in all of these different tokenizers.

tokenizer-mono-gallery

It's subtle, but you can spot some fun differences. Llama 2 splits "fox" and "tokenize" where OpenAI (among others) doesn't. BERT doesn't tokenize whitespace at all (it will never be good at Python, alas). And while we're on whitespace and Python: cl100k takes the four-space indent before return and makes one token of the first three spaces, then folds the fourth into " return", while Gemma keeps all four spaces as a single token.

Note on vendors and models: Anthropic's tokenizer isn't public, as far as I can tell, so there's no Claude face. Neither is Gemini's, though I wouldn't be shocked if it's some evolution of Gemma? OpenAI publishes its encodings through tiktoken, and its model table maps everything up to GPT-5 onto o200k_base, so the o200k face covers those. I'm not sure about the newest models like Astra (GPT-6).

The weird thing fonts can do: substitution

This entire project was an exercise in seeing how far I could push OpenType glyph substitutions—something I knew existed and understood conceptually, but had never played with.

Microsoft's OpenType spec pages explain this elegantly, in my opinion.

In a nutshell, the Glyph Substitution table (GSUB) is the part of an OpenType font that holds rules for replacing one or more glyphs (the drawn shapes, as opposed to the characters underneath them) with other glyphs. The spec numbers eight lookup types; seven of them substitute something, and the eighth is a wrapper you'll meet in the list. The examples below are in Adobe's .fea syntax, which is how most type designers write them.

  • Single substitution (type 1): a straight one-for-one swap. The slashed zero in coding fonts is this: sub zero by zero.slash;. Small caps are the same trick, just 26 times over.
  • Multiple substitution (type 2): one glyph becomes several. The usual job is taking a ligature or precomposed glyph apart so other rules can see its pieces: sub f_i by f i;.
  • Alternate substitution (type 3): one glyph has several interchangeable forms, and the app or the user picks. The canonical example is a font with a drawer full of ampersands: sub ampersand from [ampersand.1 ampersand.2 ampersand.3];.
  • Ligature substitution (type 4): several glyphs become one, while the underlying characters stay put, so you can still select and search them: sub f i by f_i;. Fira Code's !== arrows are this. This is the thing I half-remembered about fonts and went to look up before any of this started, i.e. "how do ligatures actually work?", and here we are, one weird font and a blog post later.
  • Contextual substitution (type 5): match a sequence of glyphs and run a lookup on any of them: sub [a e o]' r' lookup connect;. Every glyph in the match is fair game, but there's nothing to look at outside the match.
  • Chained contextual substitution (type 6): the one powering Tokenizer Mono. Like type 5, but now the rule can also require glyphs before and after the match without touching them, the regular-expression equivalent of lookbehind and lookahead: sub @letter f' i' r' e' lookup toRed; only fires when a letter precedes "fire". That's how the font tells " hello" from " hellos".
  • Extension (type 7): not a substitution at all. It's a wrapper that lets a lookup point past the 16-bit offset limit, so a font with huge tables can keep using one of the other types inside it. Tokenizer Mono is that font: the cl100k face wraps 194 of its chained-contextual subtables this way.
  • Reverse chaining substitution (type 8): a chained single substitution that runs backwards, from the last glyph in the run to the first, so a glyph can depend on what comes after it has already been decided. It exists for Arabic Nastaliq, where a letter's shape depends on the letters to its left: rsub e' space by e.final;.

Rules are written in Adobe's feature-file language, .fea. The warm-up font in the repo turns the word "fire" red, and only the whole word, in eight lines:

@letter = [a-z A-Z];

lookup toRed {
  sub f by f.red;  sub i by i.red;  sub r by r.red;  sub e by e.red;
} toRed;

feature calt {
  ignore sub @letter f' i' r' e';        # not "misfire"
  ignore sub f' i' r' e' @letter;        # not "fired"
  sub f' lookup toRed  i' lookup toRed  r' lookup toRed  e' lookup toRed;
} calt;

The tokenizer font is that idea pushed to a silly extreme. One rule per vocabulary token, longest first, keyed on the first glyph. When the shaper matches one it rewrites the letters to start / middle / end variants and skips past the match. That skip is what makes it greedy longest-match. In .fea terms, the rule for " hello" would be:

sub space' lookup toStart  h' lookup toMid  e' lookup toMid  l' lookup toMid  l' lookup toMid  o' lookup toEnd;

(At this scale the .fea compiler can't cope, so the rules are built directly as table data with fontTools. Same thing, no text form.)

A 22-rule state machine then paints the colors (yes, fonts can have colors; that's the next section!), looking one glyph to the left:

# continuation inherits its neighbor's color (k = 0..4)
sub [@S0 @M0] @M' lookup toM0;
sub [@S0 @M0] @E' lookup toE0;
# a new token takes the next color after a token end
sub [@E0 @X0] @S' lookup toS1;
sub [@E0 @X0] @X' lookup toX1;
# ...same four lines for colors 1 to 4, wrapping 4 -> 0...
# first token in the run
sub @S' lookup toS0;
sub @X' lookup toX0;

Colors in fonts

A few years ago I discovered Google's Noto Color Emoji font and learned you can put colors in fonts. What a neat trick! For this endeavor, while I figured substitution rules might be able to mark where the tokens start and stop, color would make it even snazzier and start to look and feel like the tools I shared toward the top.

Color in OpenType involves two tables working together. COLR says "this glyph is these layers, drawn in this order," and CPAL holds the palettes those layers pick their colors from.

COLR comes in two versions. Version 0 is flat fills, one palette color per layer, and is all I needed for Tokenizer Mono. Version 1 adds gradients, transforms and compositing, which is what Noto Color Emoji's web build uses. Chrome's COLRv1 announcement is a good explainer if you want to go further. Twemoji and Microsoft's Segoe UI Emoji ship COLR builds too.

In Tokenizer Mono every colored letter is two layers: a rounded box filled from palette slot k, and then the original letter on top in "whatever the text color is" (palette index 0xFFFF, a special value meaning "use the current foreground"). With fontTools the whole thing looks like this:

from fontTools.colorLib.builder import buildCOLR, buildCPAL
font["CPAL"] = buildCPAL([
[(0.83, 0.77, 0.98, 1), (0.73, 0.93, 0.86, 1), ...], # palette 0, light backgrounds
[(0.30, 0.23, 0.54, 1), (0.12, 0.42, 0.31, 1), ...], # palette 1, dark backgrounds
])
font["COLR"] = buildCOLR({
"a.s0": [("box.start", 0), ("a", 0xFFFF)], # box in color 0, then the letter
"a.m0": [("box.mid", 0), ("a", 0xFFFF)],
# ... 1,001 characters x 4 shapes x 5 colors
})

A CPAL table can hold more than one palette. Each index in the list in the example above maps to a layer you can refer to by slot number (i.e. index). So the same box glyph that fills from slot 0 can be pale lavender in one palette and deep purple in another, with nothing else in the font changing. Tokenizer Mono ships two: pastels for light backgrounds and darker, more saturated versions for dark backgrounds. The page on this demo picks between them with the CSS font-palette property depending on if you have dark mode enabled:

@font-palette-values --tok-dark {
font-family: "Tokenizer Mono cl100k";
base-palette: 1;
}
@media (prefers-color-scheme: dark) {
textarea { font-palette: --tok-dark; }
}

It fails pretty elegantly too. Anywhere COLR isn't supported (which isn't that many places these days; it's widely supported), like most terminals and a lot of native text fields, the boxes simply don't draw and you're left with plain, colorless IBM Plex Mono.

The fiddly bits

Greedy longest-match is not BPE. Remember that a BPE tokenizer splits text by replaying its merges in the order they were learned. The font can't do that. A substitution rule matches a fixed run of glyphs, so the best it can do is take the longest token that fits and move on. Usually that lands in the same place, which is why this font felt fun-enough to share. Sometimes it doesn't.

Take "antidisestablishmentarianism" in cl100k. In the middle of a sentence the word arrives with a leading space, and the font grabs " antid" because it's the longest token that fits there. BPE's merges for " ant" and "idis" rank higher, so the real split is ant|idis|establish|ment|arian|ism and the font's is antid|ises|tabl|ishment|arian|ism. At the start of a line there's no leading space, " antid" can't match, and the font gives a third answer: anti|dis|establish|ment|arian|ism, which looks the most sensible of the lot. (You'll see that one in the demo whenever the word is long enough to wrap onto its own line; see Known gaps.) BPE isn't trying to match how a person would break the word. It only reflects which character pairs were common in its training data, and "ant" was more common than "anti".

The fix was to hard-code answers. The build script uses the 60,000 most common English words from wordfreq and runs them through the real tokenizer and adds a whole-word rule wherever greedy would have gotten it wrong. It's goofy, but a whole-word rule is longer than any token inside it, so it works. Nothing is emitted where greedy was already right, so common words cost nothing. A second pass adds rules for any longer word a shorter rule would otherwise shadow, so " byte" can't fire inside " bytes". In other words, the word rules are a hard-coded answer key

Couldn't you keep going and add every word the greedy matcher gets wrong until it's perfect? In theory, yes! A big enough list would make the font exact on every word in it and it would work.

A few things make this impractical:

The first is cost. The cl100k face went from 4.4 MB to 10.9 MB as a TTF when the 60,000-word list added about 92,000 rules (I started with 10,000 words), so roughly 70 bytes per rule, or about 7 bytes in WOFF2. Each word gets up to four forms (leading space, capitalized, line-initial, all caps), and about half of those turn into rules. A million-word list would mean something like a million and a half rules, so on the order of 100 MB as TTF and 10 MB as WOFF2 per face. I am slightly tempted, and I won't rule out turning this into a 100 MB+ font someday, but a demo is better for now.

A more interesting challenge is performance. I bet nobody thinks about performance variance between fonts! Rules are grouped by their first glyph and tried longest-first, so the work the shaper does at each character grows with the number of rules that start with that letter. Today that's about 50 microseconds per character. Fifteen times the rules wouldn't be 15x times slower, since HarfBuzz indexes the rules rather than scanning them, but typing would start to feel it.

The third is that the words run out before the misses do. wordfreq's English list goes a few hundred thousand entries deep before it turns into noise, and the long tail is names, misspellings and concatenations, which the tokenizer treats like code anyway. Past a certain point you're spending megabytes on rules that fire almost never, and the remainder, identifiers, URLs and other languages, is the same size no matter how long the list is. Greedy plus a frequency-ranked cheat-sheet gets you to 98% coverage on this 60,000-word list, the last 2% is rare words (antidisestablishmentarianism didn't even make the list) and code, and no amount of hard-coding reaches 100% because the input isn't a closed set.

The real fix would be a font that replays merges instead of matching longest-first, which is what the SuperBPE pass does in miniature. A full replay needs one lookup per merge rank, applied in order, and OpenType caps a font at 65,535 lookups. cl100k has about 100,000 merges.

Every tokenizer treats a run of spaces differently. tiktoken keeps the last space for the next word. Gemma keeps the whole run and gives the next word no space. T5 collapses the run to one token. BERT doesn't tokenize whitespace at all! Rather than hard-code this, the build script probes each tokenizer with a real sample and picks the rule shape from the answer.

The vocabulary files lie a little. Gemma stores its whitespace tokens as "added tokens" in a separate list from the main vocabulary. Byte-level tokenizers report empty offsets for whitespace-only tokens. Both bit me, and both showed up the same way: a face scoring 40% or 70% for no visible reason.

SuperBPE broke greedy matching outright. Its tokens cross word boundaries, so the vocabulary has entries like ", h", and "one, half" became ", h" + "alf". " fan of" won over " of the" where real BPE does the opposite. The fix was to do what BPE does: shape the single words first, then re-shape the superwords in rank order as merges of tokens that already exist, matching the exact shape pattern of their parts. One rule per way of building a superword from smaller ones, so "By the way" can form on top of " the way". That took it from 86% to 93% boundary agreement, and the hand-picked sentences from the SuperBPE playground in my testing now match.

Testing by eye against a playground is slow. tools/compare.py superbpe "any sentence" prints both splits side by side, and the corpus check lists the font tokens that most often disagree with the real tokenizer.

How is accuracy measured?

When I claim "98% accuracy" for some of these, what does that even mean?

The corpus is about 200 lines of mixed text that live in the repo as fonts/tokenizer/corpus-large.txt: a few paragraphs of prose, the text of the SIL Open Font License, 120 lines of Python from the standard library, some JavaScript and SQL, and a few lines with curly quotes, accented words and currency symbols. Nothing in it was used to build the font. Our word rules come from a frequency list, not from this corpus.

The method is to shape each line with HarfBuzz, the same engine Chrome and Firefox use, and read back which glyphs came out as "start of token" variants. That gives the font's set of token boundaries as character positions. Then run the real tokenizer (tiktoken or the Hugging Face tokenizers library) on the same line and take its boundaries and compare the two sets.

Precision is the share of boundaries the font drew that the real tokenizer agrees with; a face that over-splits has low precision. Recall is the share of the real boundaries the font drew; a face that under-splits has low recall. Most faces are within a point of each other on the two, which means the errors are "different split" rather than "too many" or "too few".

Why boundaries and not token IDs? The font doesn't know IDs. It only draws where tokens start and stop, so that's the only thing it can be right or wrong about. I'm also completely new to all of this and am curious if there are other/better techniques with OpenType for this weird problem I've created (though I kind of like what a brute-force solution this ended up being).

A few caveats: Line breaks are hard boundaries for both sides, since each line is tokenized alone. The corpus is English and code, so a multilingual tokenizer like BLOOM is being judged on the part of its vocabulary it uses least. A different corpus would move the numbers by a point or two. The measurement script is tools/tokcheck.py, and CI prints the table for every face on every push.

So the reader can see what the missing 2% looks like, here are two misses. cl100k splits " antidisestablishmentarianism" as ant|idis|establish|ment|arian|ism; the font draws antid|ises|tabl|ishment|arian|ism. Same word, same letters, different seams. In code it's identifiers: xMinYMax is x|Min|Y|Max to cl100k and x|Min|YM|ax to the font.

Known gaps

A few things the font can't do, and one thing browsers do to it.

  • Browsers re-tokenize at soft wraps. The font's rules can only see the glyphs on the line as the browser laid it out, and in Chrome, Firefox and Safari alike the line is broken before the font gets its say. (I'd assumed Chrome shaped the whole paragraph and then wrapped it. It doesn't, at least not in a way the font can see: a narrow paragraph and a textarea both re-shape at the break.) So a word pushed to the start of a line loses its leading space, which makes it a different token, which is why "antidisestablishmentarianism" splits one way mid-sentence and another way after a wrap. A SuperBPE token that spans several words, like " By the way", is cut into its single-word pieces if the line breaks inside it. Resize the window and the colors shift as words move across the wrap. Nothing in the font can fix this; it's a layout decision made before shaping. If it bothers you, give the text a wide container, use white-space: nowrap and scroll sideways, or insert hard line breaks where you want them.
  • Trailing spaces at the end of a line come out as single tokens. OpenType has no "end of text" lookahead, so the font can't tell a trailing space from one that's about to start a word.
  • T5 is Unigram, which picks splits by likelihood rather than length. No longest-match scheme reproduces that, so T5 is the least accurate face by design.
  • Only characters the font knows get highlighted: everything Plex Mono has a glyph for, which is 1,001 characters.
  • Terminals and most native editors won't show the colors. It degrades to plain monospace, which is the graceful failure described earlier.

By the numbers

Boundary agreement with the real tokenizer on the corpus above, from the CI run that built the fonts in the demo (November 3, 2026), sorted by precision.

faceprecisionrecalltokens font / realshapingTTF
bert99.5%99.3%3341 / 33484 µs/char5.0 MB
r50k98.9%98.9%3758 / 375560 µs/char8.6 MB
gemma98.7%98.6%2963 / 296546 µs/char14.5 MB
yi98.6%98.7%3209 / 320844 µs/char8.6 MB
p50k98.5%98.6%3073 / 307042 µs/char8.6 MB
gemma398.5%98.5%2975 / 297645 µs/char13.8 MB
neox98.4%98.2%3004 / 301143 µs/char8.8 MB
granite98.3%98.2%3108 / 310954 µs/char9.7 MB
ernie98.0%98.1%3050 / 304748 µs/char9.8 MB
qwen98.0%97.9%2861 / 286446 µs/char11.1 MB
cl100k98.0%97.9%2823 / 282645 µs/char10.9 MB
hunyuan98.0%96.6%2824 / 286545 µs/char10.8 MB
llama397.9%97.8%2825 / 282648 µs/char11.3 MB
mistral97.8%98.4%3218 / 319950 µs/char8.6 MB
o200k97.8%97.9%2802 / 280052 µs/char13.1 MB
glm97.8%96.9%2802 / 282948 µs/char11.7 MB
llama297.7%97.8%3266 / 326551 µs/char8.8 MB
kimi97.7%97.6%2810 / 281145 µs/char10.3 MB
falcon397.5%98.6%3112 / 307541 µs/char11.4 MB
deepseek97.5%97.6%2924 / 292146 µs/char9.9 MB
falcon97.3%98.3%3225 / 319243 µs/char9.1 MB
llama497.3%97.4%2815 / 281355 µs/char13.6 MB
seed97.2%97.5%2925 / 291647 µs/char10.5 MB
tekken97.1%97.2%2977 / 297551 µs/char11.2 MB
clip96.7%96.9%2984 / 29785 µs/char9.0 MB
bloom94.5%95.0%2893 / 287758 µs/char12.9 MB
superbpe93.0%94.5%2384 / 234653 µs/char15.4 MB
t585.7%94.1%3605 / 328035 µs/char7.1 MB

Most faces land between 97% and 99%. BERT tops the table because WordPiece really is greedy longest-match under the hood, so it needs no word rules at all! r50k (GPT-2) is next; its small vocabulary leaves fewer ways to be wrong. The three at the bottom are explained by their algorithms: BLOOM is multilingual and its English vocabulary collides with tokens from other languages, SuperBPE's tokens cross word boundaries, and T5 is Unigram.

The fonts run from 5 to 15 MB as TTF and roughly a tenth of that as WOFF2. SuperBPE is the biggest at 15.4 MB, with its superword rules stacked on a 200k vocabulary, then Gemma 2 at 14.5 MB. BERT is the smallest at 5.0 MB; its 29k-token vocabulary is a fraction of the others.

Shaping costs 40 to 60 microseconds per character for the BPE faces on the CI runner, and a few microseconds for BERT and CLIP, which have far fewer rules. A 10,000-character document re-shapes in well under a second, and browsers only re-shape the paragraph being edited.

Hilariously, at 40 to 60 microseconds per character, I started wondering whether this is actually any faster than sending the text to a service that tokenizes it, returns the pieces, and having the client reassemble and highlight them. All that work only to arrive at something that might be less accurate and slower.

As that thought landed I ran a quick check, on my laptop, same 12,265-character corpus for both, line by line:

per character500-char paragraph10,000-char document
the font, shaped by HarfBuzz34 µs17 ms343 ms
tiktoken, running locally0.11 µs0.06 ms1.1 ms

So: about 300 times slower than doing it properly. I'm so proud.

Painting a span per token on the client adds a few milliseconds to the tokenizer's side, which still leaves the font two orders of magnitude behind. Against a network round trip of 30 to 100 ms it's closer to a tie: the font wins for a paragraph and loses for a document.

The one thing in the font's favor is that browsers only re-shape the paragraph you're typing in, so what you actually pay per keystroke is the 17 ms row, and nobody can probably feel that.

No regrets.

A half-baked idea to end on

Everything in Tokenizer Mono swaps glyphs for other glyphs of the same text. But a substitution rule doesn't have to. We can match a whole phrase, collapse it into one glyph, and expand that glyph into something else entirely. Good becomes evil. Up becomes down. Yes is no.

My half-baked idea after landing this was "To what degree could we be replacing glyphs with the would-be response tokens to these tokens from an LLM?" A model in a font (kinda).

So, in principle: a font where typing "What is the capital of Oregon?" could render as "Salem is the capital of Oregon." It would be deterministic, but the rule fires when the question mark lands, the answer appears in place of the question, and the document underneath still says what you typed. Select it, copy/paste it and you get the question back.

It would basically be a lookup table though, not a model. The font could only answer questions someone enumerated at build time, exactly as spelled. ELIZA packed into a font maybe. I'm putting a pin in it as the next silly font project.

If you want the real thing though, it exists! And it's wonderful. Pure OpenType substitution is a finite-state machine, which is enough for Fontemon (a playable Pokémon-style game that lives entirely inside a font). For an actual language model you need more than a state machine, and HarfBuzz has a Wasm shaper that lets a font carry arbitrary code (which is kind of insane to me): llama.ttf uses it to bundle a small Llama model and its inference engine inside a font file, so typing a prompt generates text. No browser enables that Wasm shaper, thank goodness, but the ceiling for "a font that does things" is a lot higher than you'd think.

Credits: IBM Plex (OFL), fontTools, HarfBuzz, tiktoken, Hugging Face tokenizers, wordfreq.

Sources

Every "used by" claim in the table above was checked against the vendors' own tokenizer files, not model cards or press. For public repos the tokenizer.json vocabulary and merge list were downloaded and compared directly. For gated repos (Meta, Google, Mistral, BigCode) the comparison uses the file hashes Hugging Face publishes in the repo metadata, or a public repo that ships the byte-identical file.

--

If you enjoyed reading this consider sponsoring my work on GitHub or subscribing to my newsletter.

Share this post: Hacker News • Reddit • LinkedIn • Mastodon.

Published on Wednesday, November 4th 2026. Read this post as plain-text.

Read the whole story
emrox
3 days ago
reply
Hamburg, Germany
Share this story
Delete

Resisting Cognitive Surrender

1 Share

Working Notes: a commonplace notebook for recording & exploring ideas.
Home. Site Map. Subscribe. More at expLog. — Kunal

This particular note is around exploring cognitive surrender: uncritically accepting whatever agents output without actually thinking, exploring or considering alternatives. Working this way is extremely fast, not particularly taxing, and unsurprisingly seductive.

And yet I find myself repeatedly questioning if this is actually a good way to apply agents: often enough I find myself making suboptimal decisions, accruing technical debt and reducing my familiarity with the system I’m working on instead of improving it.

As we collectively rethink how we work I’ve been finding it useful to read and share other people’s workflows, and consciously write about and examine my own. This particular post focuses on finding the right balance of trust while working with agents.

managing complexity

Cognitive surrender is seductive

One of the virtues of being a great programmer is to be lazy. After more than a decade of training myself to look for the shortest and simplest path it’s rather attractive to be able to simply hand over the problem. If I can spin up a software factory, why wouldn’t I?

There’s also a lot of peer pressure (or game theory) at work: if any of my colleagues have seemingly surrendered, then I’m only going to look worse if I spend too much time trying to do silly things like understanding what I’m working on. And, of course, while everyone else is a slop-cannon generating code faster than they can read it I can build a meticulously designed software factory manufacturing perfect designs. The sheer volume of work also appears remarkably productive – we’ve all talked about just how many more PRs we ship every day.

This tends to get compounded by the agents’ expressed confidence & conviction. Perhaps an inadvertent consequence of RLHF, but models tend to be astonishingly confident in what they recommend (and perhaps even more blasé while admitting they made a mistake). This makes it too easy to take their answers at face value, with whatever social programming I seem to have evolved with.

OSS projects – particularly those facing time pressure – seem to accrue tremendous complexity quickly, to the point that it feels like the only way to interact with a project in any sane time frame is by heavily relying on agents to navigate and modify and test the code. This is also a self-reinforcing feedback loop: broken windows multiply rapidly with agents on the loose. [1]

Technical debt and incidental complexity have a fairly attenuated feedback loop: complexity introduced by slop doesn’t bite immediately; it’s far more subtle and compounds over time when I’m not paying attention.

Beyond all of that, I have to mention the hype cycle. We all should be skipping Netflix to watch talks by Anthropic engineers on making loops (or the agentic workflow du jour). [2]

Why not surrender?

It’s not entirely obvious that it’s a bad idea to surrender: if it’s easier and better, then why not take that path? So far, my personal answer is that I need to take the easier path consciously and intentionally, with enough effort to mitigate downsides.

Part of what makes me deeply uncomfortable is suffering from a form of Gell-Mann amnesia while working with agents. When I have expertise and the overall design direction I can generally simplify the output significantly, controlling for complexity. When I don’t they seem to be the smartest engineers in existence – far beyond the more squishy, organic variety – and all I can do is follow in awe. And then the agent gets stuck creating a directory and I have to reset all my assumptions.

For the current state of the art (October 2026) I generally find maximal use of agents leads to a significant explosion in complexity: something that mostly works, with extremely surprising edge cases and bugs. These are generally the projects with hundreds of thousands of lines of code shipped rapidly, breaking the scale supported by most software development tools, so you also need to revisit those – and this compounds rapidly.

I have a strong aversion to incidental complexity, and generally refuse to build, maintain or extend it: it’s fine for a proof-of-concept, but it must end there. For systems that need to keep working, steering the design aggressively towards simplicity and modularity is what lets me build something I can actually operate (with and without agents).

As models continue to improve rapidly, I expect the previous argument to go away as the models learn and can express a broader sense of engineering taste, good design and quality. The other reason – which I unfortunately expect to persist – is that my personal understanding and mechanical sympathy for systems I maintain erode extremely rapidly, or never get a chance to develop.

In the early days when I would build things by hand I’d be able to quickly diagnose any bug or misbehavior based on my familiarity with building and maintaining the code: the more I rely on agents, the more my only option is to spin up one more session and hope; and the automated fix then further reduces my understanding in a self-reinforcing loop. Without context, I no longer have much meaningful judgement and can’t engage – or handle it in context.

The Ironies of Automation (1983) is referred to often in articles similar to this one. I’d recommend directly reading the paper if you haven’t: it’s fully relevant to the decisions we have to make today. The paper warns that it becomes even harder to deal with tasks an agent fails at because we never manage to get any practice with the easier tasks; nor do we get a chance to internalize what a system feels like under standard operating circumstances.

The Ironies of Automation

At the end of the day, I’m responsible and accountable for what I build, not the agents. Surrendering agency and not thinking basically makes me accountable without any meaningful ownership. There’s also the small matter of pride in the quality of my work.[3]

Solutions

The sombre opening shouldn’t lead you to believe that I’m not excited about the sheer potential unlocked by AI, and the opportunities to build things that I would never have been able to without it. It’s more about resetting expectations, explicitly working through the tradeoffs involved and choosing which ones are acceptable. And finding ways to maintain the quality and craftsmanship I care about.

There are still tradeoffs

The first step for me has been to internalize that I can’t truly have my cake and eat it: I can go terribly, inhumanly fast at building things but I need to accept that there’s no way to retain the mechanical sympathy, depth and confidence I used to have without putting in the effort. Time that used to be only counted as building a system also involved comprehension; agents can drive the time to build to zero but the next bottleneck – comprehension – hasn’t moved much so far.

The hype cycle occasionally can make it hard to communicate this explicitly: a lot of the communication around agentic loops tends to assume that there are no downsides whatsoever.

Choose your vibe limit & triage

Several months ago I defined my vibe limit as the complexity of the change I can make with sufficient confidence using agents. I like the risk/complexity curve enough to post it again:

Vibe Limits

The next step is figuring out where I land: there are several projects where good enough is fine, or the problem is sufficiently sandboxed that I’m happy to live with whatever the agents generated. On the other hand, if the system is important, fragile, can’t be sanity checked easily or isn’t particularly well isolated I need to directly spend my time.

Aggressive prioritization, triage, and constantly recalibrating myself become really important in this ecosystem: I should explicitly choose where to surrender agency and where to spend my time (not unlike leading a team, except the pace is much faster). Constantly reviewing my predictions and the outcomes helps a lot in recalibrating, particularly with new model drops.

Watch out for automation bias

I also find myself needing to be much more mindful while working. A warning sign I watch out for these days is if I find myself repeatedly tapping “yes, continue” in a session. At that point either I should figure out what it would take to completely delegate the problem to Claude instead of trying to micro-manage the agent – or realize that I stopped thinking and I need to check the decisions being made.

Completely delegating the problem generally means building a better sandbox or feedback loop, or figuring out ways to be able to sanity check much more easily before shipping to production. Alternatively, if I need to engage much more deeply I’ll use some of the other tactics described below.

Force yourself into the loop

The premise of augmenting myself by working in the loop with powerful thinking machines was a large part of my decision to join my current company. This generally comes down to directions you can give the model to reduce the size of the steps it takes, or explicitly choosing to drive instead of passively observing.

For projects I deeply care about, choosing to drive instead of letting the model drive is one way to intervene in every single decision. It’s much slower to type things out, but it does force me to engage with every decision and gives me an opportunity to override it. In fact, for this post I’m using a Codex session to edit: help me tighten the post, point out the small typos, punctuation errors, or half-finished sentences that tend to embarrass me after I explicitly share a post publicly – but I make all changes by hand.

In the AGENTS.md for the notebook:

Never edit files directly, always wait for the author to request or confirm changes, or let him make the edits directly.

This is reminiscent of how I used to work with Stack Overflow: never copy-paste code; instead write it out explicitly while cross-checking with documentation. Either I’d learn and internalize something new or I’d realize the Stack Overflow answer was suboptimal or outdated.

Force comprehensibility

We don’t need to limit ourselves to existing interfaces anymore: with agents it’s also possible to have them build a tremendous amount of scaffolding to support comprehension and make changes in ways that are digestible.

Often enough for larger, complex stacks I have the agents build me a custom view for the Pull Request with 4 columns: the standard 2 for the diff, a 3rd column with running commentary from the agent on why it made a particular change and finally the 4th column as a place for me to add comments and directions.

Getting the agents to make stacks of changes with the explicit direction to “Make the change easy, then make the easy change” works really well. I used to spend a lot of time trying to make my diffs easily reviewable to respect the reviewers’ time – now I can ask the agents to do the same for me.

It’s also very valuable to dive into actual execution with a debugger (or have an agent manipulate the debugger on your behalf) till you get a deep sense of how things are flowing through the program, with the confidence that this is the real execution path.

Another example is to make harnesses explain what they’re doing: I’ve built several variations of command-line helpers that transparently fit into my shell sessions (x being the last public version). In my most recent iteration, I explicitly ask the model to explain any obscure flags and commands used so that I can learn as I go.

When you do decide to delegate

Sometimes, it does make sense to hand over the problem to an agent: it could be too big, not valuable enough, time could be too short, or you just want to get a first prototype out to explore a problem end-to-end.

This one is probably an essay by itself: adapting old-school best practices when you have infinitely fast stochastic intelligence on top. The idea here is to reduce the risk in making changes, flattening the vibe-limit curve and making it possible to make bigger changes safely.

Beyond giving the agent some means to verify itself against the goal you’re aiming for, I find it very useful to:

  • Observability: Invest heavily in observability, both black-box and white-box, and make sure to keep a direct handle on the metrics instead of solely relying on the agents’ view. As a habit I prefer to triangulate onto a behavior with multiple sources of metrics, and that becomes even more important with systems rapidly becoming opaque.
  • Non-functional requirements: Don’t forget to observe resource utilization and other non-functional requirements: these can be canaries for unexpected behavior.
  • Deterministic validation: Build mechanical straitjackets for the model: have held-out pieces of code or deterministic tools for validation and observations as a hold-out against the model misunderstanding or glitching.
  • Shadow Traffic: Make it possible and cheap to run a deployed candidate against shadow traffic with no side effects: keep it as similar to production as possible, and this can be the final gate to prevent surprises.
  • Style guides: Give the model a style guide based on your existing code and work. I’ve found Claude’s output far more to my taste after having the models generate a style guide based on all the code and blog posts I’ve written in the past.
  • Fast deploys: An often maligned motto at Facebook used to be Move Fast & Break Things: that, too, is an intentional tradeoff to make. If you can’t be sure of quality, make it very easy to deploy code as well – so changes can be shipped and reverted extremely rapidly.
  • Rethink what’s possible: It’s surprisingly easy to write and rewrite systems from scratch rapidly as you learn. Build to throw, evaluate, and repeat to get something knocked into great shape – I’ve built projects in multiple iterations, giving the agent the previous iteration and its limitations as initial context and constantly finding myself able to deeply increase the quality. This doesn’t work as well when you’re punishing your code reviewers though, so make sure to align with your team, or simply don’t get the first several iterations reviewed.

Good design is a force multiplier

In Notes on the Synthesis of Form Christopher Alexander has a wonderful example demonstrating the value of decomposition – or building a lightly coupled, cohesive system to be able to succeed quickly.

No complex adaptive system will succeed in adapting in a reasonable amount of time unless the adaptation can proceed subsystem by subsystem, each subsystem relatively independent of the others.

Screenshot 2026-11-01 001757

Whether agents or humans are doing the work, a good design makes the system much easier to understand, iterate on, validate and extend. As you learn the limitations of the design, you also now have the ability to redo it much more rapidly than ever before. Regardless of how much depth you decide to maintain in your projects, I’d make sure the broader structure continues to make sense.

Additional reading

There are several interesting articles, talks and books that are relevant:

  • Addy Osmani with several additional techniques
  • Guy Levi recommending leaning into critical thinking
  • Cory Doctorow talking about handling being forced to use AI
  • Stuart Halloway emphasizing that AI is automation, and the importance of friction to build metis.
  • Elizabeth, SigNoz on skills atrophying.
  • Ricard Solé et al. on LLMs as a cognitive virus, modeling the interaction and consequences of cognitive offloading.

I’m curious if you have any other recommendations around effectively leveraging agents without losing context – I’d love to hear about additional experiments to try or workflows to adopt! Particularly if you’ve successfully recovered projects that collapsed into slop. Discuss on Hacker News.


  1. I have constantly been expecting more software to fail under the weight of its own complexity. One of my hot takes is that this hasn’t happened at the scale and magnitude I expect yet because agents became smarter fast enough to keep up with the debt introduced by the previous generation. ↩︎

  2. You’ll pry my weekly indulgence in The Great British Baking Show from my cold, dead hands. ↩︎

  3. You could argue that this is a very “Individual Contributor” approach to building things, and that managers deal with this all the time. I’ll quote Andrew Grove on management: “delegation without follow-through is abdication” – you still need to engage to get the outcome you need. ↩︎

Read the whole story
emrox
3 days ago
reply
Hamburg, Germany
Share this story
Delete
Next Page of Stories