4024 stories
·
4 followers

Biome v2.6—Support for new languages, JavaScript plugins, better Tailwind integration and the biome inspect command

1 Share
The Biome mascot next to a deck of five cards. Each card shows one of the following logos: Markdown, SCSS, YAML, Tailwind, and JavaScript The Biome mascot next to a deck of five cards. Each card shows one of the following logos: Markdown, SCSS, YAML, Tailwind, and JavaScript

- 22 min read

Biome now supports Markdown. The vast majority of the parser was implemented by @jfmcdowell , who implemented the whole parser, the testing suite, and a great harness that makes sure the HTML generated by our parser complies with CommonMark. The parser has 100% CommonMark conformance coverage. Thank you for your great contribution!

The Markdown formatter is ~92% compatible with Prettier, and we expect compatibility to be even higher in real-world projects. Thank you @tidefield for the great help. The parser supports GitHub Flavored Markdown extensions, such as task items, tables, and short links, by default.

To enable frontmatter support, use the markdown.parser.frontmatter option.

Biome can format frontmatter, HTML and fenced code blocks. This capability is enabled by default, and you can disable it with the option markdown.formatter.formatEmbeds.

Biome can analyze (lint and assist) frontmatter, HTML and fenced code blocks. This capability is disabled by default, and you can enable it with the option markdown.analyzeEmbeds.

Example:

```js

const foo = 'bar'

const foo = "bar";

```

SCSS support was written entirely by Core Contributor Member @denbezrukov @denbezrukov , who worked tirelessly to reach more than 90% compatibility with the official test suite. Most of the remaining cases involve legacy features, so we’re confident you won’t run into many bugs in modern projects.

Formatting works out of the box, and the existing CSS lint rules already work on SCSS files. Some rules can’t yet catch cases that involve SCSS constructs such as loops and mixins, because they depend on infrastructure we haven’t built yet. Refer to the documentation of each rule to learn about its current limitations.

We’ll add more capabilities in the coming months.

The Biome project owes Maintainer Member @l0ngvh @l0ngvh a lot. They implemented the GraphQL parser, and now their YAML parser is ready!

The YAML parser ships with 100% conformance coverage against the official test suite, and the formatter has 100% compatibility with Prettier, courtesy of the amazing work of Core Contributor Member @dyc3 @dyc3 .

The YAML linter ships with a single rule for now. We plan to add more nursery rules in upcoming patches, as well as dedicated rules for GitHub workflows, mostly focused on security.

Thanks to the combined efforts of Core Contributor Member @siketyan @siketyan and Core Contributor Member @ematipico @ematipico , plugins gain new capabilities in Biome v2.6.

This milestone took a lot of work, but we’re excited to announce that JavaScript plugins are now available as a developer preview, so you can start creating and shipping custom lint rules.

We designed JavaScript plugins to mirror the architecture, shape, and APIs of Biome’s Rust lint rules as closely as possible, so writing one gives you a feel for how lint rules work in Biome. Here’s what a JavaScript plugin looks like:

import { ast, defineRule, registerDiagnostic } from "@biomejs/runtime/plugin";

const RESTRICTED = new Set(["eval", "setTimeout", "setInterval"]);

export const restrictedCallee = defineRule({

query: ast("JS_CALL_EXPRESSION"),

run(node) {

const callee = node.callee;

if (callee?.kind !== "JS_IDENTIFIER_EXPRESSION") return;

if (!RESTRICTED.has(callee.text)) return;

registerDiagnostic(callee, "error", "Restricted callee");

},

});

Then add the plugin to your configuration file:

{

"plugins": [

"plugin.js"

]

}

There are some particular characteristics of Biome plugins worth mentioning:

  • You can use .js files, or .ts files. Files with either extension are valid plugins. Under the hood, Biome strips the types during the loading phase, and the files are eventually loaded as JavaScript files. This is the same strategy adopted by Node.js.
  • Biome uses a CST (Concrete Syntax Language), a particular form of syntax tree that stores all the information about a program. Working with a CST can be tedious and verbose, but it provides greater control because you can read all tokens (keywords, strings, comments, etc.).
  • Biome’s parsers are error-resilient, which means that Biome is able to format and lint a program with syntax errors. When syntax errors occur, instead of bailing, the parser is able to recover to a known good state and continue parsing. Biome uses “bogus” nodes to decorate the invalid code. While navigating the CST nodes, you’ll have access to these bogus nodes. You can decide to ignore them, or attempt to visit them. This is a completely different model from other plugin systems such as ESLint, Prettier, Stylelint, oxlint, etc. so we encourage you to take your time, and get familiar with this new model.
  • JavaScript plugins tap directly into our Rust infrastructure, which means they have access to a lot of information such as semantic model, control flow graph, file name, package manifest, module graph, type inference, and more. However, for this release, we intentionally decided to expose a subset of services. We see a lot of potential; however, this is uncharted ground for us too, so we need your feedback to build a good foundation.

Potentially, you would be able to write lint rules that use Biome’s module graph and type-inference engine.

Under the hood, Biome plugins use a JavaScript runtime built in Rust called boa. Boa is a very promising and upcoming project. The team are the authors of temporal_rs, the engine that powers the new Temporal APIs of V8 and Node.js.

Refer to the relative guide to learn about how they work, and the APIs at your disposal.

You can now distribute configuration files, GritQL plugins, and JavaScript plugins together in a single npm package. Create a biome-manifest.json file at the root of your package, and use it to share opinionated configuration files, GritQL plugins, JavaScript plugins, and rule presets.

A package can also import other Biome packages and distribute them under its own umbrella, a technique usually called aliasing.

Here’s what a biome-manifest.json file could look like. It exposes:

  • Via configs, two configuration files, one called strict and one called recommended.
  • Via plugins, two lint rules, one called useCompanyLogger implemented in JavaScript, one called noLegacyLibrary implemented in GritQL.
  • Via plugins, two presets, one called recommended, which enables the rule useCompanyLogger, and one called strict, which enables the rules useCompanyLogger and noLegacyLibrary.

{

"version": 1,

"configs": [

{ "recommended": "./configs/recommended.json" },

{ "strict": "./configs/strict.json" }

],

"plugins": {

"rules": [

{ "useCompanyLogger": "./rules/useCompanyLogger.js" },

{ "noLegacyLibrary": "./rules/noLegacyLibrary.grit" }

],

"presets": {

"recommended": ["useCompanyLogger"],

"strict": ["useCompanyLogger", "noLegacyLibrary"]

}

}

}

Users can then consume the configurations, rules, and presets in their biome.json. Assuming your package is called @org/biome-plugin, the following example enables configs/strict and presets/strict:

{

"extends": ["@org/biome-plugin/configs/strict"],

"plugins": ["@org/biome-plugin/presets/strict"]

}

Read the guide to publishing packages to learn what you can publish and how users can consume your packages.

You can still distribute a configuration file the old way, but that approach is now considered legacy.

Resolve plugins relative to shared configurations

Section titled “Resolve plugins relative to shared configurations”

Biome 2.6 introduces the resolutionKind option for object-syntax plugin entries, making plugins easier to reuse from shared configurations.

By default, Biome resolves plugin paths in a shared configuration from the directory containing the configuration that extends it. To load a plugin that ships with the shared configuration, set resolutionKind to "config":

{

"plugins": [

{

"path": "./plugins/no-object-assign.grit",

"resolutionKind": "config"

}

]

}

Then extend the shared configuration:

{

"extends": ["./biome.shared.jsonc"]

}

Biome resolves the plugin path from the directory containing biome.shared.jsonc, while includes globs are still resolved from the directory containing the extending configuration.

See plugins.<ITEM>.resolutionKind for the full option reference.

Thank you @soconnor-seeq for contributing this feature.

Biome 2.6 brings Tailwind-aware linting and class sorting closer to the way developers like to use Tailwind in their projects.

In patches leading up to this release, we’ve improved our Tailwind parser and expanded Tailwind class detection across HTML, Vue, Svelte, and Astro, and introduced new rules like useTailwindShorthandClasses and noTailwindRawColors. After lots of testing and fixing many bugs, we’re finally ready to really close the gap on our native Tailwind support.

We’ve revamped class sorting and added new rules inspired by @shadcn/lint designed to make agents produce high-quality, idiomatic Tailwind styles. We’re excited for you to try them out and to listen to your feedback as we continue iterating on them.

Tailwind CSS v4-aware sorting and stylesheet configuration

Section titled “Tailwind CSS v4-aware sorting and stylesheet configuration”

You’ve been waiting for this one for a long time, and it’s long overdue. We’re excited to finally ship Tailwind class sorting, one of our oldest and most requested features (460 👍 reactions)! The nursery rule useTailwindSortedClasses (formerly useSortedClasses) has been updated to the sorting semantics of Tailwind v4.

Tailwind v4 introduced “design systems”, where you define your application’s appearance as variables in CSS, and those automatically become available as Tailwind classes. Biome is now able to read this configuration stylesheet and it takes your design system into account when sorting classes.

{

"tailwind": {

"stylesheet": "app/global.css"

}

}

Thanks to @johncarmack1984 for the help with the sorting implementation, and Core Contributor Member @dyc3 @dyc3 for working on the Tailwind parser!

Your design system probably defines a small set of colors to use, and where to use them. How many times have you told your agent something like “make the danger button red”, and it does something silly like this:

<button class="bg-red-500">Danger</button>

You might even have a skill that tells the agent not to do that, but maybe it decided not to read it. Frustrating, right? You wanted it to use the --color-danger you have defined in your config.

In case you missed its debut in 2.5.15, noTailwindRawColors inspired by no-raw-colors, flags these cases, and points you or your agent to your design system’s existing colors.

<button class="bg-danger">Danger</button>

Now, in 2.6.0, it will actively suggest existing colors in your design system, if any are close.

src/App.jsx:1:37 lint/nursery/noTailwindRawColors ━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━

× This Tailwind CSS class uses a raw palette color.

> 1 │ export const pink = <div className="bg-pink-500" />;

│ ^^^^^^^^^^^

2 │ export const gray = <div className="hover:text-slate-100/80" />;

3 │

i Raw palette colors couple components to specific colors, making design-system changes harder.

i Use a color from your design system. These classes are the closest matches:

- bg-brand

- bg-danger

Many of you have your own component library to keep your application’s visual style consistent. Not just the colors, but the whitespace, borders, font size, and animations are all the little things that make your user experience consistent and beautiful. That consistency crumbles when your agent forces new styles on your components.

// The Button's styles are overridden

<Button className="bg-red-500 text-white rounded-none" />;

The new nursery rule noTailwindRestyledComponents, inspired by no-restyle, reports utilities that change a component’s color, typography, spacing, shape, effects, or motion.

// Use the variant the design system provides instead

<Button variant="danger" />;

You can also add exceptions, which can help with adopting this rule:

{

"linter": {

"rules": {

"nursery": {

"noTailwindRestyledComponents": {

"level": "error",

"options": {

"allow": [

{ "components": ["Card"], "categories": ["spacing"] },

{ "components": ["Button"], "classes": ["hover:shadow-lg"] }

]

}

}

}

}

}

}

Tailwind relies on string matching in order to detect tailwind classes. It scans your source code for the exact class strings, and only emits CSS for the matches. Without proper guidance, agents have a tendency to dynamically construct tailwind class strings. This causes the styles to be missing from your build output.

// Tailwind can't see the class!

<div className={`bg-${color}`} />;

The new nursery rule useTailwindStaticClassStrings, inspired by require-static-classes, flags dynamically built strings used to build class strings. It encourages using merge functions like clsx and cn instead.

<div className={active ? "bg-red-500" : "bg-blue-500"} />;

<div className={clsx(active && "bg-red-500", "text-white")} />;

All Tailwind rules will detect class strings in the exact same way, across JSX, TSX, HTML, Vue, Svelte and Astro files. The default settings should work out of the box for the majority of users, but you can configure how Biome detects class strings with the new tailwind top-level configuration:

{

"tailwind": {

"mergeFunctions": ["clsx", "cn", "twMerge"],

"variantFunctions": ["cva", "tv"],

"attributes": ["class", "className"]

}

}

The new command biome inspect is the first step towards having better debugging tooling for both maintainers and users.

This command allows you to inspect the whole configuration or single values inside your project. What’s powerful about it is that this command is able to resolve extended configurations via extends, path overrides, configuration files inside monorepos, and you can also inspect single fields using the dot-notation style.

You can start by running the default command from the root of your project, and you’ll receive the final representation of your configuration file:

biome.jsonc configuration ━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━

i Resolved configuration from biome.jsonc.

Configuration files used (merge order):

- biome.jsonc

{

"formatter": {

"lineWidth": 100

},

"overrides": [

{

"formatter": {

"lineWidth": 120

},

"includes": [

"**/*.test.js"

]

}

]

}

i Overrides are included but were not evaluated because no --path was provided.

If you need to evaluate overrides, you must provide a --path to a file.

biome inspect config --path ./src/components

You can also inspect portions of the configuration file, or fields, using the dot-notation style. To inspect arrays, you must provide a number. Here are a few examples:

biome inspect config formatter # inspect the whole "formatter" object

biome inspect config formatter.lineWidth # inspect the "formatter.lineWidth" field

biome inspect config linter.rules.suspicious.noDebugger # inspect a lint rule

biome inspect config plugins.1 # inspect the first item in the "plugins" array

This command resolves all the plugins loaded by your project and lists all the rules that are enabled in your configuration file. This is useful if you use multiple plugins and you enable rules via presets, so it provides you with a clear list of all rules.

The command also shows if rules were improved from a local source (your project) or an external source (an npm package). Here’s an example of the output:

configuration ━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━

i The configuration enables 4 plugin rules for src/app.test.ts.

@acme/accessibility

- noAutofocus (listed directly, presets/recommended)

- noPositiveTabindex (presets/recommended)

- noRedundantRoles (presets/recommended)

@acme/javascript

- noAlert (presets/recommended, presets/strict)

@acme/security

- noDocumentWrite (presets/recommended)

- noDynamicRequire (presets/recommended)

@acme/testing

- expectExpect (listed directly, presets/recommended, presets/strict)

- noConditionalExpect (presets/recommended, presets/strict)

Given a file, this command shows debugging information such as its CST, typed CST, formatter IR, and Semantic Mode (if available). We think this command might come in handy if you write a plugin, and you need to look at the shape of the CST without looking at the playground. The command must accept a path to a file:

biome inspect file path/to/file.ts

Biome v2.6 now allows you to extend configuration files and plugins from many ancestors. We still have a hardcoded depth limit of ten levels to avoid possible overflows or cycles. This means that external packages can use extends from external packages, and so on. The end user just needs to consume the final configuration file or plugin.

With this update, we added a migration path from Stylelint. Biome can now automatically migrate your existing Stylelint configuration using the following subcommand:

biome migrate stylelint --write

This command will read your Stylelint configuration and attempt to port its rules and overrides to Biome, along with ignore patterns from both the ignoreFiles key in the configuration and the .stylelintignore file.

Given the following Stylelint configuration:

{

"ignoreFiles": ["dist/**"],

"rules": {

"block-no-empty": true,

"font-family-no-duplicate-names": true,

"keyframe-declaration-no-important": true

},

"overrides": [

{

"files": ["*.scss"],

"rules": {

"block-no-empty": null

}

}

]

}

Running biome migrate stylelint --write will produce the following biome.json:

{

"$schema": "<a href="https://biomejs.dev/schemas/2.6.0/schema.json" rel="nofollow">https://biomejs.dev/schemas/2.6.0/schema.json</a>",

"vcs": { "enabled": false, "clientKind": "git", "useIgnoreFile": false },

"files": { "ignoreUnknown": false },

"formatter": { "enabled": true, "indentStyle": "tab" },

"linter": {

"enabled": true,

"rules": {

"preset": "none",

"suspicious": {

"noDuplicateFontNames": "error",

"noEmptyBlock": "error",

"noImportantInKeyframe": "error"

}

},

"includes": ["**", "!dist/**"]

},

"javascript": { "formatter": { "quoteStyle": "double" } },

"overrides": [

{

"includes": ["*.scss"],

"linter": { "rules": { "suspicious": { "noEmptyBlock": "off" } } }

}

],

"assist": {

"enabled": true,

"actions": { "source": { "organizeImports": "on" } }

}

}

The command needs Node.js to resolve the stylelint configuration file with its plugins. For now, biome migrate stylelint only supports Stylelint configurations written in JSON or JavaScript. YAML configurations are not supported yet.

By default, the command migrates identical rules only. Pass the --include-inspired flag to migrate inspired rules as well.

Promoted 59 nursery rules to stable groups.

Promoted the following rules to the correctness group with error severity. All of them are recommended:

Promoted the following rules to the suspicious group:

Promoted useIframeSandbox to the security group with error severity.

Promoted the recommended rule useDomNodeTextContent to the performance group with warning severity.

Promoted the following rules to the complexity group:

Promoted the following rules to the style group with information severity:

You can now install Biome on any platform using our new standalone installer:

# Linux or macOS

curl -fsSL <a href="https://biomejs.dev/install" rel="nofollow">https://biomejs.dev/install</a> | bash

# Windows PowerShell

irm <a href="https://biomejs.dev/install.ps1" rel="nofollow">https://biomejs.dev/install.ps1</a> | iex`

Among other things, Biome has undergone a very substantial rewrite of its architecture.

The main problem to solve was responsiveness in editors. Even though Biome is written in Rust and is superfast, working with an editor requires a completely different mindset from working with the CLI. In an editor, you need to provide a lot of information and a snappy DX as the user types, such as by reporting errors immediately.

This problem has surfaced multiple times for users with large files who have experienced delays in seeing diagnostics while typing. Not only that, but many of Biome’s internal operations were also repeated rather than cached, including the Node.js resolver, type inference, internal settings, and so on. This would result in a slowdown and a poor DX.

That’s where salsa comes into play. salsa is a framework for on-demand, incrementalized computation. Salsa is currently maintained by some members of the Astral team, and it currently powers the type inference system of ty.

Let’s use the computation of the semantic model with salsa as an example. When the semantic model of a JavaScript file is requested a second time and it hasn’t changed since the last operation, we get the semantic model from the salsa database. We avoid recomputing the same information every time.

salsa also provides a cancellation system that allows in-flight operations to be cancelled. Think of it as an advanced debounce. This is a very useful feature in editors. As you type, the LSP-based client (your editor) sends requests to the language server (Biome) with every keystroke, such as requests for diagnostics and code actions. Ordinarily, you wouldn’t see any problems with files of ~2k LoC, but at a larger scale, even the fastest language server would start having problems. With salsa’s cancellation system, we are guaranteed that an in-flight reading operation is cancelled if a writing operation changes the source code and that the latest operation is always executed.

The rewrite has been challenging. salsa has a completely different model that didn’t fit with how Biome used to work. Biome has the concept of a thread-friendly workspace server, which means that it can be sent across different threads and modified by them. On the other hand, salsa uses a model in which snapshots of its database are sent across different threads, and write operations can be performed only when those threads have gone out of scope.

Secondly, Biome must offer the same DX in both the CLI and the LSP. However, the two clients work differently from an architectural perspective. For example, the CLI is a one-shot operation, while the LSP is a long-running process in which different requests can come from different clients at different times in the process’s life cycle. The CLI is stateless, while the LSP is stateful and must keep track of information between operations.

After weeks of whiteboards and retries, we eventually found the perfect architecture for the new Biome. The CLI has become slightly faster and less noisy; it doesn’t have to recompute the settings every single time. The LSP is now snappier and faster, uses less memory, and can take advantage of the cancellation engine provided by salsa.

In the previous architecture, Biome would have recomputed semantic model, control flow, types at every lint request. Now all this information gets memorized and cached for every single file.

We have now completely rewritten our type inference engine.

Previously, Biome scanned the whole project and built all the types in one go before you could even use it. This meant that Biome built types for files that might not have needed to be analyzed. This was clearly more work—work that didn’t need to be done until a request arrived.

Now, with salsa, inference - specifically operations such as normalization, substitution, or transformation - is done on demand. When you run the noMisusedPromises lint rule, we first inspect a candidate expression and then try to infer and normalize the types from that expression. If a rule happens to inspect the same expression and request the same type, we get the memoized value, so we don’t do the same work twice.

The memoization strategy can work at the type level too. For example, let’s start with the premise that the engine wants to infer the return type of a function. Consider two functions that return Foo and Bar, respectively. The first time Biome needs to infer their types, it does so for both functions. If you edit Foo to Lorem, the next time Biome attempts to infer the types of those two functions, only the first function is inferred, while the type of the second function is retrieved from the salsa database because it hasn’t changed.

Editing value in source.ts re-runs only the queries that depend on it. If the type of value hadn’t changed, salsa would stop there, and the type of result in index.ts would be reused too.

As mentioned before, all the types were inferred and normalized after the scanning phase. Additionally, we didn’t have in place a proper system to track the normalization. As a result, we had a lot of issues tracking down what parts of the engine were slower than the others.

With the rewrite, we also introduced a predictable way to measure the different parts of the inference engine. Biome v2.6 ships a new CLI argument --profile-type-inference that you can pass to the lint or check commands. Here’s an example of the output:

profiler ━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━

i Type inference profile (Biome <version>)

src/index.ts

Requests (top 5 of 12 groups; 28 source records; 46 executions)

1. Promise classification <- nursery/noFloatingPromises

...

Queries (top 8 of 25 groups; 61 source records; 94 executions)

1. Promises / infer_expression_is_promise

...

Whole-module inference (top 1 of 1 group; 1 source record; 1 execution)

1. Import depth limit

...

68 files omitted.

ℹ To show all the information, use the --verbose option. The output might be very verbose, so it's advised to analyze a single file.

$ biome lint --profile-type-inference --verbose ./path/to/file.ts

This will help both maintainers and end users triage bugs in the inference engine.

This blog post highlights the changes that we deem most exciting; however, many more changes await you, such as a Git-aware init command, new lint rule options, and more. Consult the detailed changelog to discover all changes.

I like where this is going, how can I help?

Section titled “I like where this is going, how can I help?”

I want to remind you that Biome is a project led by volunteers who enjoy programming, care about open source, and embrace the Biome philosophy, so any help is welcome.

Join our Discord server, and grab the @team-testers role. We will ping you from time to time, and we will ask you to test preview releases before they are released.

If you are familiar with Biome and would like to contribute to its outreach, you can assist us by translating the website into your native language. In this dashboard, you can check the supported languages and whether they are up-to-date.

Join our Discord server, and engage with the community. Chatting with the community and being part of the community is a form of contribution.

If you like the technical aspects of the project, and you want to make your way into the Rust language, or practice your knowledge around parsers, compilers, analysers, etc., Biome is the project for you!

There are numerous aspects to explore; I assure you that you won’t get bored. Here is a small list of the things you can start with:

If you believe in the future of the project, you can also help with a financial contribution via Open Collective or GitHub Sponsors.

Additionally, the project provides an enterprise support program where you as a company can employ one of the core contributors to work on a specific aspect of the Biome toolchain.

Copyright (c) 2023-present Biome Developers and Contributors.

Read the whole story
emrox
5 hours ago
reply
Hamburg, Germany
Share this story
Delete

Introducing TanStack Redact

1 Share
A smaller replacement for React and React DOM in the browser. Keep your application code and ship less JavaScript.

Read the whole story
emrox
1 day ago
reply
Hamburg, Germany
Share this story
Delete

CSS-Tricks has a new owner!

1 Share

Yes, I've got the keys to the castle, so to speak. And, even after 12 years of working on the site, I'll admit I'm a little overwhelmed and nervous about that.


CSS-Tricks has a new owner! originally handwritten and published with love on CSS-Tricks. You should really get the newsletter as well.

Read the whole story
emrox
1 day ago
reply
Hamburg, Germany
Share this story
Delete

The Mythical Man-Month in the age of AI

1 Share

Last weekend I watched four people desperately trying to get a laptop to connect to a screen. I was happily observing their efforts, with zero intent to join in.

But someone nudged me: can't you have a look at it?

My reply: "Haha sorry no! My experience is that adding more people will not solve this problem any quicker".

I was of course -- indirectly -- referring to Brooks's Law:

"Adding manpower to a late software project makes it later."

It was formulated by computer scientist Frederick P. Brooks Jr. in his 1975 book The Mythical Man-Month, based on his experience managing the IBM OS/360 project.

However I got to thinking. Does this still hold up in the age of AI agents and LLMs?

At first glance, you’d think no. The traditional bottlenecks -- onboarding time, endless stand-ups, and office politics -- disappear overnight. An AI agent is up to speed in milliseconds and doesn't demand a coffee break.

But when you look closer, and the law hasn't vanished. It just mutated.

The famous "Baby Problem" remains: nine agents still can’t deliver a baby in one month. Sequential tasks are still sequential.

Overhead hasn't disappeared; it shifted: instead of managing people, you are now managing agents. Someone still needs to define "done", review the code, catch hallucinations, and stitch the pieces together.

That someone is you.

Throw nine autonomous agents at a single codebase without crystal-clear orchestration, and they will happily rewrite each other's work in a high-speed loop.

Maybe the 2026 update to Brooks’s Law should be:

"Adding agents to a project with unclear requirements gets you the wrong answer faster."

Read the whole story
emrox
2 days ago
reply
Hamburg, Germany
Share this story
Delete

Blurry before beautiful: image previews for the web

1 Share

Abstract illustration of a multi-color blur with a line passing through it, extending past the blur, with colored dots along it.

You've probably already seen this common pattern in action: blurry versions of the images of a site appear immediately and, moments later, their full versions replace them.

This pattern has become so common that many image CDNs, frameworks, and libraries support it out of the box. But every implementation has to do the same thing:

  • Fetch both the preview and the final images.
  • Display the preview while the final image loads.
  • Swap the preview and final images.
  • Clean up after the transition.

Below is an example of the effect, which shows a blurry preview image. Click the button below to load and display the final image:

The Louvre pyramid in Paris.

Lorem ipsum dolor sit amet, consectetur adipiscing elit. Vestibulum volutpat accumsan tristique. Phasellus sit amet mauris odio. Aenean urna felis, laoreet vel ipsum ut, dignissim fermentum mi. Fusce posuere efficitur laoreet. Donec lacinia massa cursus eros ultrices maximus. Proin sit amet vestibulum nibh. Nulla luctus eleifend nisl. Aliquam vel orci a nisl maximus bibendum ut sit amet turpis. Curabitur sodales risus placerat nulla congue bibendum. Aliquam ut mi et dui efficitur semper. Donec tempus nibh eget est aliquet bibendum. Pellentesque habitant morbi tristique senectus et netus et malesuada fames ac turpis egestas.

We are proposing to make this a built-in capability of the web, and we'd love to know if this is worth pursuing and what the exact scope should be.

Before diving into the proposal, let's take a look at how this pattern is typically implemented today.

How to do this today?

There's currently no standard way to provide a preview for an image, so the solution depends on the framework or library you're using.

For example, Next.js can generate a blurred placeholder when an image is imported, by using the placeholder=blur property:

import mountain from "./mountain.jpg";

<Image src={mountain} alt="A mountain" placeholder="blur" />

Libraries such as blurhash encode a tiny preview as a short string, which your application can then decode to show the preview while the real image is loading:

// First, create blurhash strings for your images.
import { encode } from "blurhash";
async function encodeImageToBlurhash(width, height, imagePixelData) {
  return encode(imagePixelData, width, height, 4, 4);
};
// At runtime, while the image is loading, decode the string to display a preview.
import { decode } from "blurhash";
const pixels = decode("<the blurhash string>", 32, 32);
const canvas = document.createElement("canvas");
const ctx = canvas.getContext("2d");
const imageData = ctx.createImageData(width, height);
imageData.data.set(pixels);
ctx.putImageData(imageData, 0, 0);
document.body.append(canvas);

You can also use write your own custom implementation, for example by creating image previews at build-time, and sending them as data URLs used in CSS background images, while the final image is loading:

<div class="image" style="background-image: url(data:image/png;base64,....)">
  <img src="image.jpg" alt="A mountain">
</div>

These approaches differ, but they all have to coordinate the preview and final image themselves.

Why a native solution?

This preview effect is well established, and for good reasons. It allows your UI to come to life much sooner, giving the impression of a more responsive site which lets users access the rest of the content while images are still loading.

We don't want to change this pattern, but instead implement it in the browser so that you don't need to write, maintain, and run as much code. With a solution that's built-in, you let the browser handle most of the complexity.

What's in the proposal?

For now, our proposal focuses only on loading, displaying, and replacing the preview image. To achieve this, we propose to introduce a new attribute for the <img> element called previewsrc:

<img previewsrc="tiny-blurry-preview.png" src="full-image.avif">

With the previewsrc attribute, the browser would:

  • Load the preview and final images, always giving priority to the final image.
  • Display the preview.
  • Replace the preview with the final image when it becomes ready.

This already simplifies the process of handling image previews a lot because you don't need to use or write code to load the preview, handle cases where the preview doesn't exist or fails to load before the final image is ready, and handle the image swap yourself.

We'd love your feedback on this initial proposal: do you consider this a valuable addition to the web platform? Is it enough on its own for you to use it?

Possible future enhancements

If you're using a library or framework to handle previews today, your solution might also support the following features:

  1. Customize the transition between the preview and the final image, for example by adding a fade effect, to make the swap look nicer.
  2. Support compact formats such as blurhash directly, without needing to write additional code.

Our initial proposal doesn't support these features. When the final image becomes ready to paint, the browser directly replaces the preview with the final image, with no customizable transition. Also, it doesn't natively support compact formats such as blurhash.

We're currently considering them as optional enhancements that could be added in the future, but your feedback on their importance would help us prioritize them: would you use previewsrc alone or would you require support for these optional enhancements (and if so, which ones) before adopting it?

Let us know!

Let us know how you feel about this proposal.

Is the problem worth solving at the web platform level? What would consitute the minimal viable solution for you to adopt the API?

Please send your feedback by opening a new issue on our GitHub repository.


Common questions

You might be wondering about the following questions, so let me provide some answers below.

Doesn't a preview image create a second request?

Sure, if you set previewsrc to another image URL, then an additional network request will be made, which potentially will consume bandwidth. However, consider this:

  • The final image loading would never be delayed by the preview.
  • The browser would always treat preview loading as "best effort".
  • The browser would assign a lower priority to preview fetches and decodes.
  • The browser would, in fact, completely skip previews when they are unlikely to be useful.
  • And you could still continue to use blurhash strings or data URLs for previews, avoiding a second network request altogether.

It's important to keep in mind that this is not a replacement for proper image optimization, and not a performance feature.

Does this avoid abuse?

It doesn't. There is actually no enforcement mechanism in the proposal for ensuring that developers use the previewsrc attribute responsibly.

The proposal depends on developer discipline, the same discipline they apply when using existing image preview techniques.

However, this is important: the browser may skip the preview altogether if it determines that it is unlikely to be useful before the final image is loaded or if resources are constrained. That's definitely a plus compared to today's solutions.

Why not use progressive image delivery instead then?

JPEG images can be progressively delivered, whereby the image is loaded in multiple passes, gradually increasing in quality. This allows users to see a low-quality version of the image almost immediately, while waiting for the full-quality image to load.

In the end, this depends on your use case. A progressive JPEG may be preferable for sites where more fidelity is required, where seeing the real image, even if in low quality, is more important than having an instant, but very blurry preview.

Generally speaking, blurred placeholders seem to be favored for providing a quick visual indication, responsiveness, and layout stability. I feel like developers have mostly moved away from progressive images.

But also, not all sites generate progressive image versions at all.

What about responsive images?

They keep working as before.

An <img> inside a <picture> element can still use the previewsrc attribute. The existing <picture>, srcset, and sizes algorithms continue selecting the final image.

Why not just display the preview as a background-image of the <img> instead?

Using CSS to paint a background-image on the <img> element while it loads is a common technique, as described in How to fake Progressive WebP Images.

The advantage of a browser-provided previewsrc attribute over this are:

  • Both the preview and final URLs are directly associated with the <img> element.
  • The previewsrc attribute would get reflected as an HTMLImageElement property.
  • The browser would manage error handling, sizing and positioning, synchronizing updates, and best-effort scheduling
Read the whole story
emrox
5 days ago
reply
Hamburg, Germany
Share this story
Delete

The rise and fall of Jev hype

1 Share

The rise and fall of Jev hype

What can we learn about the hype engine that declared war on rational and critical thinking?

This is a quick note on how the industry’s reaction to Jev reveals the desperate state of AI. I’ll dissect:

  • What is Jev, how was it hyped and why it spread like mass hysteria? Jev isn’t dead but its hype cycle is. Decision models are on the rise.

  • What are the noteworthy innovations since ChatGPT brought “AI” to the mainstream?

  • Why is the industry starved from real innovation and what high impact problems are still unsolved after 4 years of revolution incremental improvements?

The point is to use Jev’s hype cycle to call out the manipulative marketing that are too familiar with at this point.

Jev

You probably don’t need an intro to Jev at this time because since its introduction 33 days ago, it has been all the rage!

But if you were clever enough to ignore it, here’s what actually matters:

Jev is basically a general purpose classifier (e.g. quick judgement). What makes it interesting is that you don’t have to train it with a lot of data (although that lack of special-purpose training negatively impacts its utility).

Calling it a “decision model” is a bit far fetched especially since it cannot even see (rival open-weight models have multi-modal features) or reason (that’s how it’s so cheap).

The idea behind Jev isn’t new! The idea of non-autoregressive decision models with RL goes back more than a year ago. The original author is pissed but as we’ll see drama is an inseparable part of AI hype.

Hype

I want to walk you through the emotional roller-coaster I went through when I read their announcement via hackernews:

At OpenAI, I helped build the methods that made language models useful at following instructions and talking with people. That work ended up as the research behind ChatGPT.

😎 So the founder was behind ChatGPT, one of the fastest-growing products in history. I’m listening…

At the time, I thought maybe chat models would lead to AGI, but despite the hype it became obvious to me that there was something really big missing.

😃 Oh, my god! This is it! ChatGPT is missing something big and he’s about to reveal it! We’re one step closer to AGI if we haven’t reached it already! I’m thrilled to read more…

After two years in stealth, countless technical challenges, and research breakthroughs… I am beyond excited to announce

😱 Spit it out! I’m beyond excited to read this…

TypeSafe AI is releasing our first System One Model

😯 Wait what?!! “System one”?

Do you understand what you’re talking about? Here’s my recollection of how Daniel Kahneman defined the two systems:

  1. System one: fast, cheap (in terms of computational power), emotional, unconscious and judgmental.

  2. System two: slow, expensive (takes more brain power), logical, conscious, and more elaborate.

If Jev is system one then LM is system two? It can’t even handle logical reasoning!

Most importantly Jev came with another interesting framing:

can’t hallucinate

Hallucination is one of the biggest problems with the current generation of language models but no hallucination doesn’t mean the response is logically correct. In Jev’s context, it just means that the output matches the schema.

Technically conventional language models can gain this ability by bolting a control loop (e.g., type checker, JSON schema parser) on top. Jev does this much faster and without reasoning. It’s in the name:

We named Jev after William Stanley Jevons. We expect machine intelligence to follow a similar path to coal, after steam-engine efficiency led to an increase in demand.

I don’t know Jev’s architecture because in the true ex-"Open”AI employee tradition, not much is released (probably in the name of “safety” or “moat”). But that doesn’t stop them from dropping jargons:

We built a new […] training method we call Reinforcement Learning for Calibrated Decisions (RLCD).

Note: RLCD rhymes with the “traditional” methods:

  • RLHF: Reinforcement Learning with Human Feedback

  • RLVR: Reinforcement Learning with Verifiable Rewards

They even claim:

Jev is neither small nor an LLM, hence being off the intelligence Pareto curve.

Fortunately, there’s no shortage of similar models, some of them with even better performance (Laya, Kev, Nimble, NanoJev, etc.)

So let me sum up the marketing strategy:

  • Name dropping: former ChatGPT creator, Jevons’ paradox, Pareto curve, System one

  • Big claim: cannot hallucinate, exponentially faster and cheaper, entirely new stack, amazing benchmarks and demos

  • Ambiguity and jargon: no useful implementation details on the “new training algorithm” or RLCD dataset

  • Drama: Laya showed this idea in 1.5 years prior to Jev’s launch

OK, I think at this point we’ve seen this pattern enough to recognize it. I actually think Jev’s team kicked it up a notch to a comical level. Whether their marketing is written by LLM or not, they nailed it.

Fortunately, Jev’s initial noise died off almost at the same speed that it blew up. I can only speculate that as more people experimented with it, we realized:

  1. It cannot hallucinate, but it can still be wrong. It is even more wrong than conventional language models, and in that sense “system one” is the right naming. Although I consider all current generations of language models system one (even the reasoning models) because they do not really reason in the sense that’s expected of system two.

  2. It is cheaper, but there are open-weight models that beat it in performance/cost ratio (depending on the task). What makes Jev different than frontier-level LLMs is the fact that you can actually run it at the edge (e.g. locally) with matching quality.

Jev is not completely hype, we just went from “Peak of Inflated Expectations” to the “Trough of Disillusionment” in record time:

It’s not dead. Some companies use it while I believe the majority of use cases are addressed by open-weight rivals.

I really don’t want to bash Jev. Instead I want to use it as an example of where we are, as an industry.

Incremental improvements

I was one of the lucky few who got access to GPT-2 when it was invitation-only.

As a senior tech lead, I allocate part of my time to scout new tech and experiment in order to stay relevant. Prior to that, I had experienced IBM Watson and a bunch of other products so it wasn’t a big deal for me personally.

I was actually underwhelmed by GPT-2 because at the time it could:

  • Summarize text

  • Predict what comes after a piece of text

  • … that was it really! 😄 I don’t remember more than that. So I moved on…

Then I saw someone create a turn-based dialogue from one of these models and to spice it up, they added an avatar to it. I thought it was creepy and funny.

Then Blake Lemoine came out claiming Google’s language model named LaMDA was conscious. Unsurprisingly, this started a philosophical discussion that’s still ongoing on the side. Again, I didn’t give it too much thought.

BUT, Sam Altman, having spent a few years at the startup accelerator (Y Combinator), saw an opportunity. Specifically the chat application seems to have got his attention and soon ChatGPT was announced.

At the time, I thought it was a cool way to turn their token prediction model into a user-friendly product for the masses.

Personally, I couldn’t use it seriously because:

  1. Poor quality: it didn’t know what it didn’t know, so it just winged it (AKA hallucination). Although the rise of “prompt engineering” and “reasoning models” promised to reduce this issue.

  2. Privacy: I had been working with computers for 2+ decades at the time and live by the mantra that “if it’s possible, assume it happened”. Meaning if OpenAI is technically capable of storing my conversation, I cannot trust it enough to share any company IP or private information with it.

I vividly remember the backlash Google got for their multi-modal demo when people realized it wasn’t recorded in real-time! Those were the days when even a small deception would be a conspiracy.

When llama.cpp came out I got a gaming machine with an NVIDIA card (AI machines weren’t a thing back then) to build with AI.

Meanwhile people discovered that language models can generate code It was tedious to copy/paste it so we got the early versions of a harness.

Quickly after, we got “function calls” which allowed the models to do stuff!

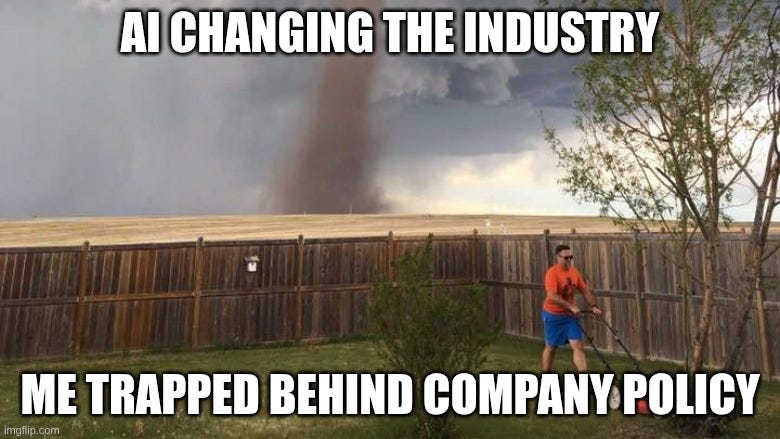
I was using VS Code at the time and the hype was hard to ignore even though my company at the time had a strict policy against using AI tools (yes! hard to believe that just 3-4 years ago companies prioritized IP over velocity).

I remember paying for a Copilot subscription out of pocket and using VS Code insider on my open source projects.

I was so frustrated that I shared this meme on the company Slack:

Meanwhile there was drama at OpenAI (Ilya was part of a coup that fired their CEO, then Satya was playing 4D chess while Elon was lawyering up). It was a sh*tshow which is exactly how it managed to capture the interest of non-techies, a trend that continues to today with “almighty rogue AI” hacking others while whistle-blowers and alarmists rise speak of existential threat!

Simultaneously premature AI products were creating dramas of their own (assisting crimes, cheating, etc.) and AI bros anthropomorphize the tool as if it had desires of its own (my read: they want to judge accountability).

There’s also circular investment, pentagon drama, chip wars, autonomous killer drones, etc. but in the spirit of brevity, let’s stick to the technical side of things.

Then Peter Steinberger, a veteran developer who was away from computers due to burnout, created an AI companion, which brought the Agents (LM that can do stuff) to the mainstream.

So far I’ve covered:

  • Instruction-tuned models

  • Function calls

  • Coding harnesses

  • AI agents

Let’s speed through the other incremental improvements:

  • Larger parameter size unlocks emergent properties that are hard to explain by analyzing the micro level architecture (mostly leading to sophisticated perceived behavior but also jagged alignment).

  • Larger context windows improve accuracy (although the practical limit is much smaller than the theoretical size).

  • Multimodal models enable generating voice, music, pictures, and videos while increasingly more models can understand these modalities.

  • MCP abstracts away the implementation and enables different AI products to use the tools needed to do productive work.

  • ACP, sub-agents and various orchestration techniques allow larger tasks to be planned and broken into smaller pieces.

  • Sandboxes help improve security and isolate unwanted side effects of agentic workflows and when they fall short, there’s HITL (but we still haven’t solved the approval fatigue).

  • Skills, web search and web access allow agents to access information that’s outside their training data or knowledge cut-off date.

  • Various memory architectures and consolidation techniques enable the models to recall what they learn.

  • Chinese labs showed us more efficient ways to train and run the models.

  • Feedback loops and scratchpads improve the model’s perceived quality by running part of the verification closer to the model.

This is good progress, no question about it. But I think a part of the reason AI is a hot topic is all the drama surrounding it:

  • Geopolitics: unlike the US economy which is primarily service-based, China is a manufacturing behemoth. Up until DeepSeek discovered that it can manipulate stock and AI investment by diffusing the compute equation, I don’t think China had a solid AI plan. Now they do. Good old American sanctions target their chip import but China (being run by engineers) made huge strides recently both in chip manufacturing but also in model architecture. Meanwhile AI is used in warfare from drones to intelligence (and mass surveillance back home). In the best seller How the mighty falls, Collins lists 5 stages of demise: a) Hubris Born of Success, b) Undisciplined Pursuit of More, c) Denial of Risk and Peril, d) Grasping for Salvation, e) Capitulation to Irrelevance or Death. Those same stages apply to a falling empires and in this case US has bet big on AI while China diffuses US’s massive bet with open-weight models. Consumers win for now.

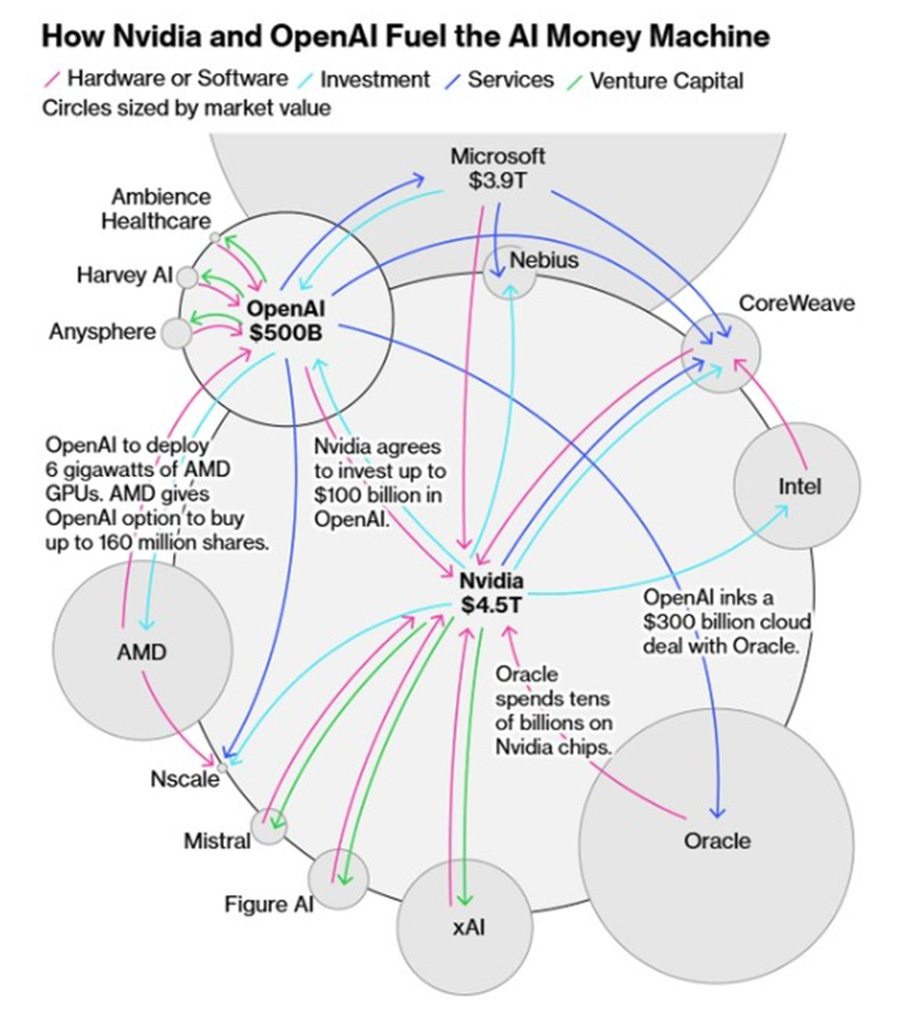
  • Debt bubble: You can read more on Bloomberg but it basically boils down to a series of interdependent bets that is so large it impacts the national GDP. It has to work regardless of how much IP has to be stolen and how many lies have to be told. The stakes are too high at this point.

  • Safety: we got used to the “rogue AI” narrative where the AI vendors aren’t held accountable for breaking into other companies and government institutes. Why would we? It’s an open secret that the training data wasn’t legally obtained anyway (and there are multiple class action lawsuits to prove that). On top of it, there have been multiple cases where people lost their lives due to AI — and I’m not even counting “vibe war”. (yes, I actually put an em-dash there!) 🙃

  • Impact on jobs: software engineering is low-hanging fruit for AI automation due to its nature (there’s plenty of training data, and the tools are often on a language model’s home turf). There have been discussions of UBI (universal basic income) and UHI (universal high income) but looking at the benevolence of the billionaires running the show, I don’t buy it at all.

AI is hot, because it can potentially impact all of us. But we have to remember one simple fact:

Humans are fundamentally flawed when it comes to predicting the future.

Most notoriously, we have difficulty understanding the S-curve (meaning the pace of change is slow at the beginning and end).

And with prominent scientists leaving their lucrative positions to slow down the pace of development, we really cannot be sure about how long it will take for AI to really manifest the changes, if ever.

What’s missing?

With all the incremental improvements of the past few years, we still haven’t solved some fundamental problems.

Here’s a short list of what I consider truly game changing:

  • Abstract reasoning: neural networks (not just language models) are prone to making stuff up (hallucination). The state of the industry has improved a lot since hands had 5+ fingers and videos were easy to detect, but the closest we’ve come to a true system 2 is to pair the models with code and still the feedback loops and human intervention are necessary.

  • Continuous learning: auxiliary context (e.g. skills, grounding, search and various model architectures) has come a long way but we’re far from the state where the models learn in real time. By extension, the next generation of AI should learn from fewer samples, data and repetitions.

  • Embodiment: while there have been great improvements in robotic body form factor, we’re still not at a point where AI is rapid and efficient enough to be put in a robot body and react to the sensory stimuli in real time or expose fine motoric control and navigate the 3D world with enough prevision to take over “simple” human chores.

  • Economics of running AI: Jensen Huang talks about installing “Gigawatts” of compute as if it’s normal to measure temperature in kilometers/hour!!! The truth is: our brain delivers AGI level intelligence at 20 Watts and until we solve that problem, there is not enough water, power and data centers that can realistically make massive change in workforce. Unfortunately, we live in a post-truth world where hysteria, personalized propaganda and mass psychosis have an oversized impact on the dominant discourse so we’re all supposed to be scared and distracted. The economics makes even less sense if we expect embodied AI (robots) to replace even a fraction of human population. Unlike bots, our organic bodies return to nature and participate in the nature’s recycling system much faster than metals and plastic that build a robot. Sometimes I feel we forgot that we’re living on a tiny rock with finite resources which get increasingly harder to extract.

All of this, is not to say that AI won’t be used to:

  • Robosoldiers and robocops

  • Generate new diseases

  • Connect mass surveillance to personalized propaganda

  • Corporate espionage and mass penetration into computer systems

  • etc.

The truth is: you don’t need AGI-level of intelligence to cause destruction. The current generation of AI, paired with harness, tools and skills is plenty capable of causing damage in the wrong hands.

And if you think this is not happening already, I know a guy who gives free ice cream in his basement! 🙃

Recap

I think Jev is a good example of how great marketing fizzed out in the face of reality.

  • Is it useful? Yes.

  • Is it relevant? Yes.

  • Is it dead? Just its hype.

  • Is it revolutionary? Depends on your cost, quality, speed triangle.

  • Is it as big as it was claimed? I hope you have the answer by now.

If I had a magic wand, I would want us all to step back and see the holistic arc of recent events and calm down a little. The red flags are easy to see:

  • Name dropping: builds a bridge between the new unknown to the trusted known.

  • Jargon: makes you feel stupid for not having the context.

  • Ambiguity: lets your brain fill in the blanks and if you’re an optimist, you’re at risk of getting overly excited and eventually disappointed

  • Inflate expectations: big claims require big evidence. Don’t trust the isolated benchmarks that do not resemble how YOU would actually use it, especially if the benchmark is coming from the same entity that has a conflict of interest.

  • Drama: engages human emotion to what would otherwise be a logical technical decision. “All publicity is good publicity”.

Unfortunately, I think that ship might have already sailed and in the age of mass-produced synthetic content and personalized propaganda, maybe we’re too stressed to think straight.

Maybe LLMs are “system two”, after all, if we collectively lose our critical thinking and let our emotions be manipulated with the kind of marketing and manipulation we’ve seen too much lately.

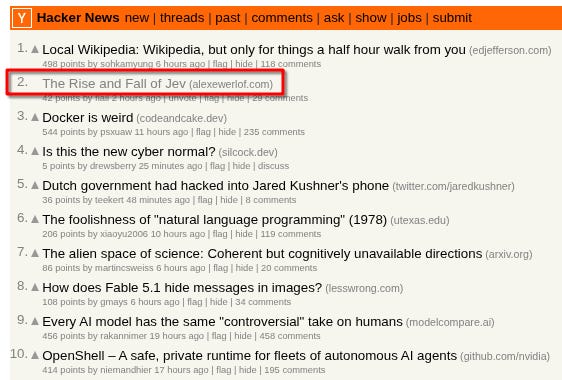
Someone shared this on Hackernews (thank you 🙌) and it went all the way up to 2nd position. The early comments came at agentic speed but apparently didn’t bother to read through.

Generally I find HN comments to be quite useful but there seems to be a botnet actively trying to take it personal and derail the conversation to marketing Jev even further. Weird. 🤔

If you found this piece insightful, please share it in your circles and on social media to inspire others.

Share

My monetization strategy is to give away most content for free but these posts take anywhere from a few hours to a few days to draft, edit, research, illustrate, and publish. I pull these hours from my private time, vacation days and weekends. The simplest way to support this work is to like, subscribe and share it. If you really want to support me in lifting our community, you can consider a paid subscription. If you want to save, you can get 20% off via this link. As a token of appreciation, subscribers get full access to the Pro-Tips sections and my online book Reliability Engineering Mindset. Your contribution also funds my open-source products like Service Level Calculator. You can also invite your friends to gain free access or save via a group subscription.

And to those of you who already support me, thank you for sponsoring this content for the others. 🙌 If you have questions or feedback, or you want me to dig deeper into something, please let me know in the comments.

Subscribe to Alex Ewerlöf Notes

Technical Leadership, Reliability Engineering, Growth

Discussion about this post

Ready for more?

1Password menu is available. Press down arrow to select.
Send this story to NewsBlur
Shared stories are on their way...
Read the whole story
emrox
5 days ago
reply
Hamburg, Germany
Share this story
Delete
Next Page of Stories