3971 stories
·
4 followers

Reversing Factorio's RNG

1 Share

Introduction

With the release of the Space-Age DLC in Factorio several new mechanics were introduced. One major mechanic was the new concept of different items and building qualities. By default, items are created with common quality. If quality modules are used in the crafting machine we gain a small chance to obtain items of higher quality.

What does that entail? In short: Items and buildings gain improved stats, such as faster crafting speeds, modules providing stronger buffs, power poles having an increased range and inserters swinging faster. Thats pretty neat – hence we are interested in obtaining the highest possible quality on our items and buildings. To source a large number of such items the devs essentially said that this randomness boils down to “basically statistics”,1 i.e. if the volume high quality items one obtains is sufficiently large, then the observed distribution of qualities will be close to the expected distribution.

But is it the only way to scale? Thinking about it, one might ponder:

How is it possible for a deterministic game like Factorio to have a random mechanic?

The short answer is: It isn’t random.

Instead – as is common in computing – the simulation makes use of a pseudo-random number generator (PRNG). A PRNG is a deterministic algorithm which produces a sequence of numbers which for all intents and purposes appears to be random. In particular this means properties like it following a well defined distribution of outputs, which contains no discernable patterns. Normally in computer science one can get away with treating the PRNG as just a black box function which can yield random numbers, without concerning oneself with how it actually works. Yet by taking a look under the hood we can do something funny.

The Funny: What happens if we know the exact algorithm and its internal state?

Then we could just run the same algorithm on the state and obtain the same outputs, which will also be seen by the game internally. Its necessarily always the same outputs, as otherwise the chosen algorithm would not be deterministic. As such we can run the same computations simultaneously to the game and predict the future outputs of the PRNG, allowing us to predict the future “random” events which will occur in the game, such as which crafts will observe an increase in quality.

In the following sections I’ll build up to that point, starting from what RNG the game uses, how it is breakable and how it can be abused ingame. The entire background should be understandable if you have a rudimentary understanding of linear algebra. That should be the only prerequisite.

Starting from Nothing

Soooo, how does one figure out what PRNG algorithm Factorio uses? Afterall, there are several different implementations out there they could have chosen from.

To figure this out, my first step was a rudimentary internet research. As the Factorio community is quite large and filled with many technically inclined individuals, surely someone must have asked this question before. After digging around a bit I found a post on the Factorio forums asking basically the same thing I wanted to know, though 11 years have passed since then. In that thread, we also find the following answer by Cube, a former developer at Wube. They wrote:

[…] We chose taus88 mainly because it is the fastest from boost’s generators. I was thinking of removing one of the three LFSRs (that should make it about 40% (?) faster), but there is no point, since the ran[d]om numbers are not a bottleneck for us.

This already gives us a lead on where to look next: the Boost.Random library. There we find the following (abbreviated) implementation for the taus88 generator:

typedef xor_combine_engine<
  xor_combine_engine<
    linear_feedback_shift_engine<uint32_t, 32, 31, 13, 12>, 0,
    linear_feedback_shift_engine<uint32_t, 32, 29, 2, 4>, 0>, 0,
  linear_feedback_shift_engine<uint32_t, 32, 28, 3, 17>, 0> taus88;

template<class UIntType, int w, int k, int q, int s>
class linear_feedback_shift_engine {
  // w = word size (e.g. 32 for 32 bit uint)
  // k = number of bits in the LFSR
  // q = feedback tap position
  // s = number of steps to do at once
  // wordmask() = 0b11...111; mask of w low bits set
  result_type operator()() {
    const UIntType b = (((value << q) ^ value) & wordmask()) >> (k-s);
    const UIntType mask = (wordmask() << (w-k)) & wordmask();
    value = ((value & mask) << s) ^ b;
    return value;
  }
}

This means that taus88 consists of 3 linear_feedback_shift_engine whose results are XORed together. Note that this linear feedback shift engine is more commonly referred to as a linear feedback shift register (LFSR).

Though when starting the project that post was already 8 years old. Hence, I wanted to cross-check the information given on the forum against the most accurate source available: The game binary.

While the game itself is closed source, the developers graciously ship a .pdb file containing the debug symbols alongside the game binary. This means we can generate a well-annotated decompilation of the binary to inspect the code and figure out what is going on under the hood. To this end, I used the open source decompilation tool Ghidra, switching to Binary Ninja later on in the project. Regardless of which tool one uses, one can rather quickly find the RandomGenerator class in the game’s code, where getInt() is implemented as follows:

uint RandomGenerator::getInt(RandomGenerator *this) {
  uint a = this->seed1;
  uint b = this->seed2;
  uint c = this->seed3;

  a = (a << 12 ^ a >> 6) & 0x1fff ^ a >> 19 ^ a << 12;
  b = (b << 4 ^ b >> 23) & 0x7f ^ b >> 25 ^ b << 4;
  c = (c << 17 ^ c >> 8) & 0x1fffff ^ c >> 11 ^ c << 17;

  this->seed1 = a;
  this->seed2 = b;
  this->seed3 = c;

  return a ^ b ^ c;
}

The first thing which stands out is that almost none of the constants used in the original taus88 definition remain. This can be attributed to the compiler performing optimizations such as constant folding to reduce the number of required operations. Yet the fact that we store 3 seeds for our RNG state is a first strong indicator that it is indeed the same generator. Likewise, the states are updated independently of one another, with the final result being the XOR of all three states.

To rid myself of all remaining doubt about whether the two implementations are equivalent, I rewrote both variants in Python so they can be run using sympy, a Python library for symbolic manipulation. Advancing both variants by a single step confirms that all bits of the corresponding registers update in the exact same fashion. I used sympy here because doing these equivalence checks by hand () would have been quite tedious. The corresponding code can be found here.

Ok, with all that established, we are certain that the RNG used in Factorio is indeed the taus88 generator, which itself is a combination of 3 LFSRs. This is a very interesting result, as LFSRs are known to be quite weak PRNGs – in the literature one even finds the statement that they are trivially breakable.2

To understand what makes them ”weak” and how we can exploit this weakness to predict the future RNG calls, we first need to look at the underlying mathematics of LFSRs, which is the subject of the next section.

LFSR Maths Review

To begin, we need to understand what the linear feedback shift register (LFSR) actually models. First, consider a simple register. It describes a collection of bits, aggregated into a single value :

Each individual bit can be seen as a binary variable with . While it is common to consider this register value to represent a number in the range , it is more useful in our case to instead consider the register to actually describe a vector of individual bits, i.e. . Additionally, we consider two operations which operate on each individual bit:

  1. : The XOR operation takes 2 bits and returns 1 if the bits differ and 0 if they are equal. Note that this is equivalent to addition modulo 2.
  2. : The AND operation takes 2 bits and returns 1 if both bits are 1, otherwise it returns 0. This is equivalent to multiplication modulo 2.

Now extend that notion of a register into a shift register. To shift, move all bits in the register downwards by taking each higher bit and shifting it 1 position down, dropping the lowest bit as the output. Here we follow the convention that the most significant bit (highest bit) is the leftmost bit and the least significant bit is the rightmost bit .

You can interact with this kind of register below. Tap the individual bits to toggle them, and use the controls to start, stop and step the registers.

Well… This is boring! We converge pretty quickly to the same value of 0 regardless of the initial state. This does not seem random at all! To keep our shift register from always just discarding all information we will add another component, namely some feedback. The first idea is to just loop the discarded lowest bit back into the highest bit, as it previously had no preceding bit from which it could obtain (new) information, while we discard information in the lowest bit. Doing this we have basically implemented a bit roll operation:

Hmmm… At least we no longer always arrive at an empty register. But the sequence when the last bit lights up is very predictable. This is due to the fact that the information that we observe repeats every steps – each bit remains unmodified after all! Thanks to the low cycle length, one can again quickly spot the pattern produced by our current feedback shift register. To combat this we insert some linear feedback, by adding the feedback not only to the first bit, but also some intermediate bits. Note that addition here means XOR, as we are working with individual bits:

Unlike the last steps it might not be immediately obvious why this step is named the way it is. It comes from the fact that the XOR operation we use to combine the feedback into the inner bits causes our bit states to be a linear combination of the previous bit states. This linearity is also the reason why we can reconstruct the internal RNG state from just observations alone, and why standalone LFSRs are cryptographically weak PRNGs.

Note that in all the cases above only the last bit was considered an output. However, in practice it is more common to output the entire register state as the result of the RNG call. This then allows one to reinterpret the number as a proper integer in producing random looking numbers.

We now know how an LFSR gets constructed. In particular, given the state at time we now know how to:

  1. Generate the next state .
  2. Generate corresponding output bits, either one at a time, or as a full integer value.

LFSRs are linear

Let us take another look at the linearity claim from above. To do that rather than considering arbitrary instantiations of , i.e. states where all bits were set to either 0 or 1, we can now consider a symbolic representation of the LFSR. We still start at an arbitrary point in time , at which we label each individual bit with an additional symbolic variable . Then we track how the bits evolve over time as we apply the LFSR transition rules. Each symbol is colored either on or off depending on the state at which the LFSR was started. As before, you can toggle individual bits by clicking on them – though only while the bit labels are in the initial state.

We see that every bit is always just a combination of the initial bit states. Note that whenever we observe the cancels out, allowing us to remove it from the equation again. While stepping, each instantiated bit will always stay equal to the parity of “on” bits in the symbolic combination depending on the state when we assigned the labels. Additionally we notice that a bit is either just the preceding bit state, or it is a combination of the preceding and the feedback state.

Now what has this got to do with linearity?

First of all, note that the set of bits joined with the operations and form a structure known as a field. This field is commonly known as the Galois field or the modular arithmetic mod 2. A field is just a math term for a set of values joined with some operations which satisfy a certain set of properties (see below).

Why do we care about this? Because having a field structure is a prerequisite for vector spaces. In particular here, we consider the vector space spanning all vectors of length over the field , which is denoted as . The operators are now applied pointwise to each coordinate of the vector using the operators from original the field . And wherever we have a vector space, we can talk about linear combinations of vectors.

Personally, after getting an introduction into linear algebra and vector spaces within that abstract framework, I subsequently only ever saw them applied to either or, if spicy, to . However, the original definition of a vector space is kept very generic on purpose! It allows any structure which satisfies the necessary properties to be manipulated in the same way, enabling us to apply well-known algorithms that you may have only seen applied to systems described by matrices to arbitrary matrices, regardless of the underlying field .3 And as luck would have it, the previously defined operations XOR and AND on the bits span a field!

Taking another look at the symbolic example, we can reformulate each individual bits transition as a linear combination of previous bit states:

Since we can write the entire state as a vector of these bits, and each transition is linear itself, this means we can write the transition between the current state to the next state as a matrix product:

where . Note that like the bits in the state vector, each individual entry in the matrix is a value in , i.e. it’s either 0 or 1. In particular this allows us to visualize this matrix as a bitmap, where a bright entry means a 1 and a dark pixel represents a 0. For the 6 bit wide toy LFSRs we saw previously, this looks as follows:

This mathematical notation allows us to start rewriting some operations in a more compact way. The most notable of them is the ability to advance the LFSR by multiple steps at once in compact notation:

Now that we have seen a bunch of theory, we can actually apply it to the above code snippets. Focusing on a single LFSR component we have:

a = (a << 12 ^ a >> 6) & 0x1fff ^ a >> 19 ^ a << 12;

This can be written out for each individual bit and evaluated. In turn we obtain a system of 32 equations, as each LFSR is defined over uint32_t words, which have 32 bits. Note that some of the bits are actually redundant due to the construction of the LFSRs in the taus88 library: the LFSR size is always chosen smaller than the word size.

Mapping the toy example process to the actual LFSRs which occur in taus88 we obtain the following 3 transition matrices which map to of one of the three generators respectively. We again can visualize these matrices as bitmaps, where a bright pixel corresponds to a 1 and a dark pixel corresponds to a 0. In them we also nicely see the independence from the lowest bits, as they appear as empty columns in the transition matrix.

Transition matrices for the 3 LFSRs.

Note that unlike the previously discussed LFSRs these change more than just the feedback bits directly. This is what the parameter does in the linear_feedback_shift_engine constructor, which essentially is the number of steps each individual LFSR is advanced in a single step.

Inverting an LFSR

Going forward quickly is already nice. Going backwards though, that is where the real shenanigans occur. Since should we then somehow observe enough outputs of the RNG, we could then infer the full state just from the observed data, which then allows us to run the LFSR in a separate process to predict the future RNG calls.

Careful observation of the original construction of the LFSRs already highlights that this transition matrix needs to be invertible. If you want to try it yourself, think about how you would step each bit backwards immediately after going one step forwards, and what the different cases are that come up. Consider the same toy LFSR as shown above:

By simply modifying the way in which the data flows, a new variant can be constructed, which allows us to run the same LFSR but in reverse. These changes originate from the following considerations:

  1. In the ”forwards mode” each step sets the topmost bit to the previous state’s bottommost bit value . As such, to get the value back into the lowest bit position, simply reverse that arrow. This means the feedback arrow now originates from the topmost bit instead.
  2. If a bit is just shifted from above with no XOR between, then this step is reversible by just flipping the direction of the shift. No further modification is necessary.
  3. However, if the bit is a combination of both the upper bit and feedback bit, then we reverse the step by computing . Visually this is consistent with the first step, where we reversed the feedback bit origin, keeping all XORs at the same locations, feeding them with the new source value. This will cancel out the feedback state added in the forwards mode, and reverse the shift as though no modification happened.

In simpler terms, this amounts to us just flipping almost all arrows from the previous LFSR diagram to obtain the following ”reverse mode” LFSR:

In mathematical terms what we have just shown is that if exists which corresponds to a single forwards step, then we can always construct another matrix which perfectly reverses the previous step. i.e. we have found an inverse:

As such, for any given originating from an LFSR we know that exists. This can then either be generated by the construction above, or alternative methods such as Gaussian elimination. Usually for Gaussian elimination we only transform the matrix into an upper triangular matrix. However in without any numeric issues we can directly solve for the inverse matrix using following pseudo code:

def invert(M):
  # Extend with the identity matrix on the right
  system = [M | I]
  # Iterate over all columns in the original M
  col = 0
  for row in M.num_rows:
    # Find pivot row, which hasn't previously been applied
    for pivot_row in range(row, M.num_rows):
      if system[pivot_row][col] == 1:
        break
    # Move the pivot to the current row
    system.swap_row(pivot_row, row)
    # Cancel all other rows with a 1 in the current column
    for cancel_row in range(M.num_rows):
      if system[cancel_row][col] == 1 and cancel_row != row:
        system[cancel_row] += system[row]
    # Move to the next column
    col += 1
  # Return the part which was previously the identity
  return system.I

Combining multiple LFSRs

We’ve seen that we can solve the state of a single LFSR as a linear equation of the form where all components are computed modulo 2. Remember, however, that the full RNG result is determined by 3 independent LFSRs whose output we XOR together. We can model this as having 3 different states each with a corresponding transition matrix . If we then stack all these state vectors together, we obtain a big vector describing the entire state at once. For this new state vector we can again derive a transition matrix which we know to be invertible:

To obtain the final result from the current ”hidden state of the RNG we can then simply calculate:

where is the corresponding identity matrix. If we just look at this, we might think that the entire thing turned non-invertible again. And this would be true, if we only look at a single output. But what happens if we step the random generator multiple times? The first output stays as it was, the next are:

and likewise:

Thus, we realize that if we observe 3 full outputs in a row we obtain the following system of equations:

In other words: To figure out what the state of the PRNG registers was at any time step , we need to observe the results of 3 consecutive calls and solve the linear system of equations:

Implemen­tation Hurdles

The earlier result of inverting the observation matrix already works. In fact, it was the first solver implementation I built in Python. For the observations, I used the Factorio Lua API to generate 3 consecutive random numbers. That was enough to recover the internal state and predict future RNG outputs; see: First recording of the method working

Before we try to implement it with only the available resources in-game, we still have to inspect two theoretical hurdles:

  1. Currently we need the result of consecutive calls. These might not be available to us.
  2. Moreover, the full result width i.e. all 32 bits at once of the PRNG calls are required for our observations. With pure game mechanics, these are not necessarily observable.

As such, let’s take a look at both of these issues, and how we can address them.

Consecutive calls

In the previous derivation we utilized the states , and which correspond to using the full width of 3 consecutive calls. As we are not necessarily the only system in the simulation requesting RNG values at any given time, we need to consider a non-isolated case. There are several ways to tackle this:

  1. If we have a method of counting the calls made between observations, we can skip the non observed results by generalizing the previous result to use instead, where is the number of calls we skipped until the next measurement.
  2. Alternatively, we try to force the measurements to occur consecutively. This can be done by disabling all other sources in-game which can interfere with the measured calls, doing our necessary calls in order and computing / manipulating from there.
  3. The latter can be extended further by venturing into the realm of sub-tick mechanics. Every 1/60th of a second, the game performs an update step, aka a tick. Within this tick all the simulation mechanics run in a fixed order. One of the triggered mechanisms is of course the creation of the crafting results within all machines finishing their item crafting cycle. If we now can harness the order in which the machines queue the item creation events, placing our entropy generators in a consecutive block within this queue, we force the RNG calls to be gapless, ensuring proper state reconstruction can occur.

For my implementation I chose to pursue both option 2 and 3. The former, as it does not rely on internal update orders, is the fallback method which should always work (as long as the devs do not change the RNG away from taus88). Meanwhile, in theory, the latter approach allows for much faster state readout and more robustness against extraneous outside calls. In practice, however, it appears somewhat flaky, breaking at seemingly arbitrary times.

Full result width

For our Entropy Generators we will use crafting recipes which have some randomization in their outputs. This has the drawback that whenever we measure such an output, we do not obtain information about the entire PRNG call. Instead, the only thing we can measure are some simple questions about the output, depending on the chosen method. Some examples are:

  • The number of output items. It involves randomness if either the recipe yields non-integer item stacks (e.g. recycling recipes, which return 25% of the items required to craft a single input item or the item itself in case it is a self-recycle recipe), or it is a recipe with inherently random outputs (e.g. uranium processing, where there is a 0.7% chance of a U-235 being produced and a 0.7% chance of not producing a U-238).
  • The quality level of the output. We can measure if it rose in level, and if yes by how many at once.

I’m going to focus on the first of the two methods, just observing the amount of produced items – as this was the only source of information I had available when I started this project. The thing to realize is that answering any of these questions yields us only information about some of the top bits of the RNG roll result.

Let’s stick with the example of refining uranium ore into U-235 and U-238. For this we have 2 production results:

  • U238 occurs with 99.3% probability as a result and
  • U235 with a 0.7% chance.

To generate both outputs, the RNG is queried twice for a single crafting cycle. Once per item to generate two consecutive RNG calls. Because these probabilities are very extreme, we gain important knowledge whenever the low-probability event occurs. The resulting item gets generated if the respective inequality holds, where is the computed RNG roll:

In particular:

  • If U238 was not generated, i.e. is greater than the given threshold, we know that the first 7 bits are 1.
  • Likewise if U235 was generated, then the first 7 bits of have to be 0.

Otherwise, we have no meaningful information about the rolled bits.

Cool! But which recipe will yield us the highest amount of information each time it completes? The more information we obtain with a single crafting cycle, the fewer crafts we require and the faster and more efficient we can determine the internal state.

Like we saw above, the only information we can observe is determined by the topmost bits, and whether we obtained the item or not. If we now estimate that the rolls are actually evenly distributed, we can compute the expected amount of information gained with each roll and observation:

This means we can expect a total of bits per successful crafting cycle. If we study the above pattern a bit longer, we might notice that the number of leading bits obtained in each positive case (i.e. where the probability is ) is where is the probability of the event occurring. A similar thing holds for where the result is instead leading 0 bits observed. This allows us to compute the expected number of bits we measure for an event with probability . Overall, it can be written as:

This function is also shown below. Its plot indicates the following:

  • The event which has the highest expected number of observed bits is situated at the even 50% split. At that point we can in fact always observe the most significant bit.
  • While events closer to 0/1 allow us to infer more bits whenever they succeed, the likelihood of the events occurring diminishes too fast, decreasing the total number of expected observed bits per event instead.

What we just calculated can be seen as a discretized version of Shannon entropy. As such, we have a measure applicable to all available recipes allowing us to identify those which yield the largest amount of information per craft. By extracting the relevant recipe data from the raw game dump4 we can programmatically compute the entropy for each recipe.

Doing so yields a table of recipes with their corresponding expected bits of information per craft, alongside how long each craft takes. The following highlights a small selection of recipes with random outputs, for the table containing all recipes with random outputs see here.

RecipeBits per CraftCraft­ing TimeItems Returned
4.50.5

3.75x Steel Plate

2.5x Iron Gear Wheel

2.5x Stone Brick

2.5x Electronic Circuit

2.5x Pipe

30.03125

1.25x Electronic Circuit

1.5x Iron Plate

1.5x Iron Stick

0.75x Steel Plate

2.050.2

1x Iron Gear Wheel

(20%)

1x Solid Fuel

(7%)

1x Concrete

(6%)

1x Ice

(5%)

1x Steel Plate

(4%)

1x Battery

(4%)

1x Stone

(4%)

1x Advanced Circuit

(3%)

1x Copper Cable

(3%)

1x Processing Unit

(2%)

1x Low Density Structure

(1%)

1x Holmium Ore

(1%)

20.03125

0.5x Electronic Circuit

0.5x Iron Gear Wheel

10.03125

0.5x Iron Plate

0.50.2

1x Iron Plate

(25%)

0.11

1x Yumako Seed

(2%)

2x Yumako Mash

0.09812

1x Uranium 235

(0.7%)

1x Uranium 238

(99.3%)

Excerpt of recipes with random results producing bit observations.

As we can see, there are waaay better recipes for extracting information from the game. One might think that scrap recycling would yield a lot of information due to the many different items which can be produced. Yet with a total entropy of it is only slightly above recipes like recycling repair packs which have an entropy of . This is due to the fact that recycling repair packs (and similar recipes with ingredient count ) yield exactly one bit of information of the RNG output in either case, as it creates a perfect split on whether the additional item will be created or not. There are obviously alternative recipes such as the oil refinery which has an entropy of . These, however, are also quite a bit more expensive and slower than repair pack recycling.

As such, I chose to implement the state readout using the repair pack recycling method, as repair packs are cheap, fast to craft, and unlocked early in-game.

Actual Implemen­tation

To actually implement the reversal and manipulation of the RNG, I’ve split the computation into the following steps:

  1. Sampling the current RNG through observations,
  2. Computing the current internal RNG state,
  3. Predicting the future internal states,
  4. Calculating corresponding quality levels for each future call, and finally
  5. Making use of the predicted levels with some adapters.

As already alluded to in Inverting an LFSR, we will need to compute a matrix-vector product for both of these steps. Now the question is how do we get the matrices, and where do we get the vectors from?

Sampling the RNG

The current state will be computed from observations made when recycling repair packs. Each recycling operation will yield exactly 2 bits of information, 1 for each resulting item. This in turn means that we require recycling operations to have enough information to fully reconstruct the state. As each result provides us with exactly one bit of information – the topmost bit of the RNG call – the 88 observations can be written as:

A single unit measuring and may look as follows:
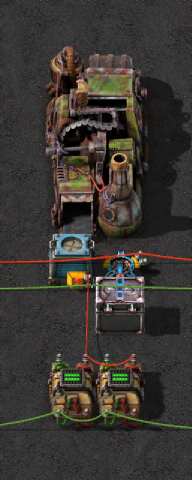
Screenshot of a single entropy measurement unit. A single entropy measurement unit.

It performs the following steps:

  1. The inserter will move exactly 1 repair pack into the recycler.
  2. The recycler will recycle the item, and upon completion query the RNG for 2 new integers, determining whether extra items (either 0 or 1) are produced.
  3. Depending on whether the items are produced or not, they are placed into the provider chest. This chest is set to read the contents, providing the observation to the red wire.
  4. These observations directly correspond to the topmost observed bits due to the 50% chance of output. Further processing occurs through the decider combinators below.
  5. Before the next call can occur, we clear the provider chest by making use of the trash unrequested option, alongside the enable/disable signal we can send over the green wire connected to it, which temporarily pauses the auto trashing behavior when the requestor chest is disabled. Otherwise it requests no items.

The above unit will therefore always provide us with 2 bits of information. To reconstruct the full state quickly, we copy this unit 44 times, yielding a total of 88 bits. This then looks like:
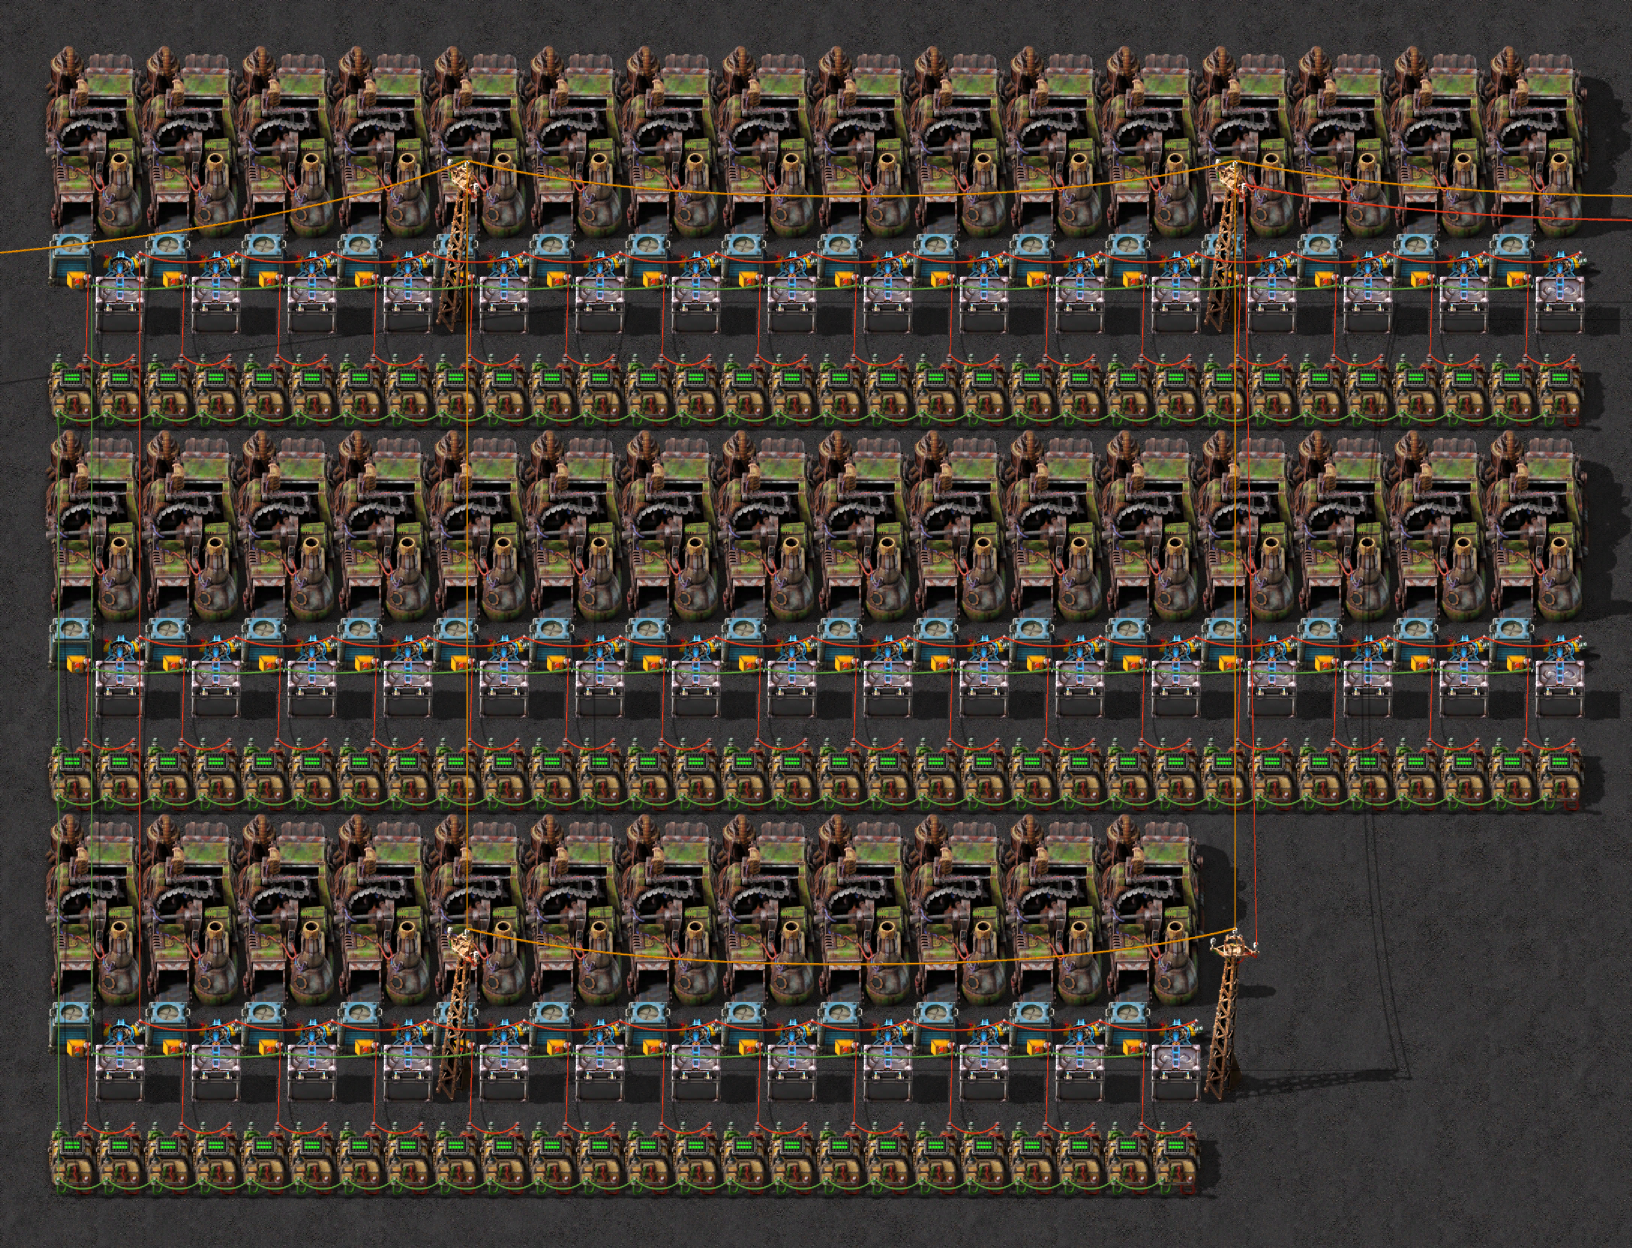
All entropy units joined together. All entropy units together.

Of note here is the manner in which the individual units are queried. There are 2 approaches:

  1. Either each is triggered with a 1 tick delay, ensuring that they are always queried in the same order. This, however, requires us to not have any other RNG running in the meantime, as RNG calls which occur in between will mess up the expected ordering.
  2. Alternatively, we can use same tick shenanigans. By splitting the red wire connecting the inserters with a 1 tick delay combinator in front of every inserter, this can be achieved. Connecting the inputs to the delay first creates a shared circuit network. Then sequentially connecting all outputs of the delays to the corresponding inserters will create a standalone network for each inserter. As the game needs to update the networks in some manner, I bank on the fact that it will iterate through the list ordered by the network ID. This ensures that the RNG calls all happen in the same tick, with no ticks interfering. Note that the wire construction can also be done using a 2-stage blueprint.

Note - Regarding the Same Tick Behavior

While the same tick stuff seems to work in practice, I have not actually confirmed that this is how the game works under the hood. It can be brittle at times, as it seems to arbitrarily break at random times. In those cases, simply reconstructing the wires allows it to work again.

Determining the current state

Each unit produces only single bit observations as a result, so we need to apply a similar strategy as we did before. This time though, we only use the first row of the linear equation defined above for computing observations from the state:

where is the first row of the matrix . If we now let be the matrix which denotes performing RNG steps followed by an observation of the topmost bit, then we can write the observations we gather above to follow the subsequent equation:

Now, as we consume 88 calls when we perform our observation, it would be beneficial to instead directly calculate the state the RNG will be in after our observation, rather than when we started. This can be achieved by making use of the inverse transition matrix which causes some shift in the time index, creating a new matrix :

Shifting the time to be relative to the next RNG call by means of substituting we then arrive at the equation:

This can be read as us computing the next internal RNG state from the previously done observations. Now since there are only 88 bits which are actually linearly independent, we cannot compute a full inverse. However, a pseudo-inverse will suffice. Especially since we are interested in the states after – for which the lowest bits are entirely described by the most significant bits. This means that even a single step forward will deterministically set those previously unknown bits, so we are all fine.

The really neat thing about this entire endeavor is that matrix and similarly do not depend on any dynamic state. As such, can be precomputed in Python and subsequently used in Factorio.

Hence we only need to implement a matrix-vector multiply in in-game. To do so, remember that any matrix-vector product can be seen as a weighted sum of the matrix columns weighted by the entries in the vector:

In this case, as we are performing our computations in , each entry is either 0 or 1, meaning the multiply can be represented with a simple conditional, while the sum is substituted with an XOR over all the weighted vectors:

Here is the -th column of while is the -th bit observation performed. In practice this equation is computed in 2 parts.

First, each measurement unit computes a pointwise scalar-vector multiplication of and vector . This is done via the decider combinator mentioned above doing “further processing”. If the resulting item was not observed () then the roll was above the threshold and we have , meaning this column needs to be accumulated otherwise it is not. The vector is stored in the constant outputs of the decider combinator, where only the bits which are 1 are actually output. As such the vectors are represented by 96 different signals.
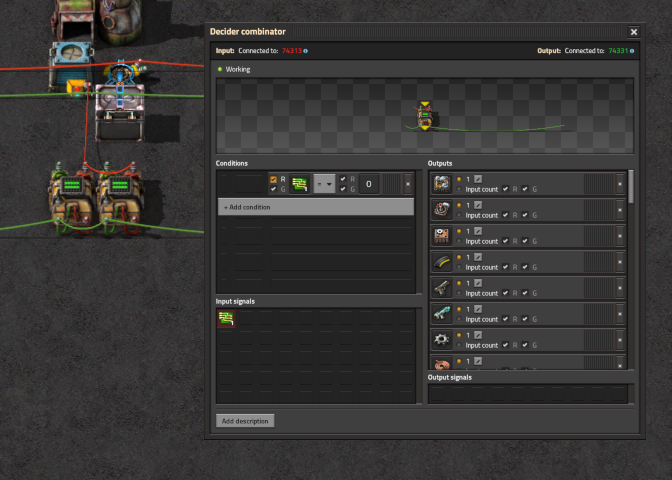
A single decider combinator computing a single scalar-vector multiplication. A single decider combinator computes a single scalar-vector multiplication.

Finally we require the XOR of all these vectors to obtain the final state. This can be achieved via implicit addition.5 Summing the values of a single signal and extracting only the last bit of this sum is equivalent to taking the XOR over all of them. As such, by wiring all decider outputs together, a single arithmetic combinator can perform the bit extraction by ANDing the pointwise sums with 1.

As each signal now corresponds to a single bit of the 3 32-bit LFSR states, we can make use of a set of decider combinators to sum up all the corresponding bits of each active signal. Thus we have 3 signals, each containing the current state of the game’s RNG.
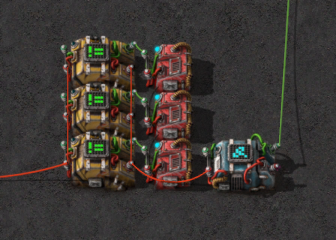
The final XOR sum of all the scalar-vector multiplications. The final XOR reduction.

Looking into the future

We perform a similar action to compute the future states of the individual LFSRs. However, as all LFSR states require fewer than 32 bits, we can store the lookup table in a more compact fashion. For each LFSR we need to compute the following:

This is computed for , where and are different between the 3 sub LFSRs. From this we can again rewrite these matrix-vector multiplications as:

where is the -th column of . These columns can be stored as 32 bit integers, as . Hence the skip-ahead equation can be implemented in parallel for all steps as follows:

  1. Split the packed state into its individual bits . Represent these as individual signals again (arithmetic combinator on the left).
  2. The pointwise scalar vector multiplication with all the different vectors will either include all the vectors in the corresponding -th state or not, thus we can implement this via a decider combinator again. This time, however, I store the constants in a separate constant combinator – it can output more signals at once. I opted to predict 1000 forward steps in parallel.
The same matrix column from different T^k transition matrices. The same column from different transition matrices.
  1. Now we have 32 nets each full with 32 bit wide values which need to be XORed together. Unlike before we cannot utilize the implicit addition here, as the vectors are now not represented by 32 different signals but instead via a single 32 bit signal value. Thus we have to use more arithmetic combinators. I’ve opted to use a binary tree to pairwise XOR sets of vectors together, as this is a known fast reduction strategy for prefix sums (which this is).
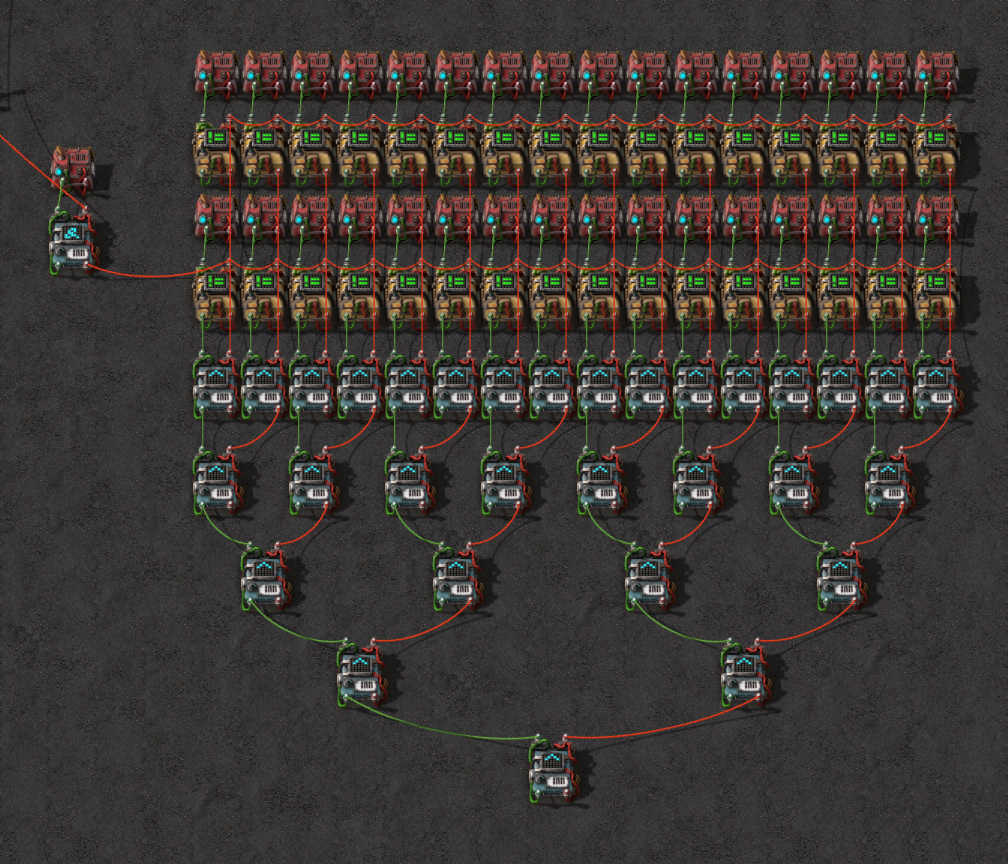
Parallel look-ahead for a single LFSR Parallel look-ahead for a single LFSR.

Quality prediction

Now that we have the next RNG call results before the actual in-game calls happen, we need to make them usable for our purpose. This basically means implementing some form of the rollQuality function from the game. A reverse-engineered version of the function can be seen below, implemented in pseudo-C++:

// Fixedpoint value of the module effect from -32.768 to 32.767
// e.g. 10% quality would be a value of 100
typedef EffectValue int16_t;

// Stub of relevant quality prototype fields
struct QualityPrototype {
    ID<QualityPrototype, uint8_t> id;
    ID<QualityPrototype, uint8_t> next;
    double nextProbability;
}

// Mapping from the ID<...> to QualityPrototype
PrototypeList<QualityPrototype>::indexToPrototype;

// Function which determines crafting result quality
ID<QualityPrototype, uint8_t>* QualityPrototype::rollQuality(
  ID<QualityPrototype, uint8_t> qualityID,
  EffectValue bonus, 
  RandomGenerator* generator,
  IDIndexedData<uint8_t, ID<QualityPrototype, uint8_t>> 
    const* unlockedQualities
) {
  // If no bonus, do early return -> no RNG call!
  if (bonus == 0)
    return qualityID.copy();
  
  QualityPrototype* quality = indexToPrototype[qualityID];

  // Roll the RNG exactly once
  double roll = RandomGenerator::uniformDouble(generator);

  // If roll < threshold we upgrade to the next quality
  double threshold = (double)((float)(bonus) / 100f);

  // Find highest quality which beats the threshold
  uint8_t nextIndex;
  while ((nextIndex = quality->next.id.index) != 0) {
    if (!unlockedQualities->data[nextIndex])
      break;

    // Scale by next upgrade probability, base game = 0.1
    threshold *= quality->nextProbability;
    if (roll > threshold)
      break;

    quality = indexToPrototype[nextIndex];
  }
  return quality->id.copy();
}

If we take a look at how the function is implemented in the game we can see that it basically just takes the RNG roll and compares it against some thresholds. It stops as soon as it finds a threshold which is no longer beaten by the roll.

This means that each craft which involves quality rolls will take exactly 1 RNG call. And for each call we can compute the expected quality level by just comparing against all the thresholds, which stay constant during the game. Thus they can be precomputed in-game with some arithmetic combinators.
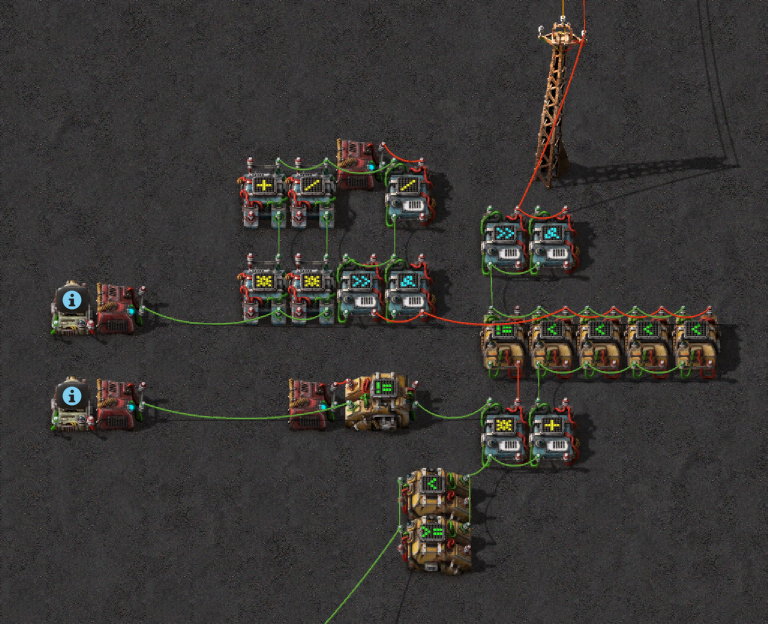
Computing the quality levels from RNG states in-game. Computing the quality levels from RNG states in-game.

The calculator below shows the required threshold for each quality level, as well as the expected amount of each quality level for a given bonus. Note that when the threshold exceeds , i.e. the uint32_t maximum value, we always upgrade, which is indicated by placing the thresholds in brackets.

ResultProbabilityuint32_t Threshold
75.200%1,065,151,889
22.320%106,515,188
2.232%10,651,518
0.223%1,065,151
0.025%106,515

Adapters

Yippee, we can now compute the relevant RNG outcomes before the corresponding calls even occur in-game. Now the question is what can we do with that? I have by now experimented with several – what I call – adapters, which take in these predictions, and do some funny stuff with them.

Beginning with the first that I’ve implemented:

Predicts quality levels before the craft.

It takes the sequence of future output qualities, and displays them next to the assembler, similar to the “Next Up Pieces” queue in Tetris. Each time a craft is completed, it advances the window into the future outputs by one, keeping the display relevant at all times.

The next one was the following:

Selects assembler by next up quality.

This one takes the same list, but instead assigns only a single crafter to fabricate the next item. The assembler which is selected depends on the next output quality. In turn this leads to the 5 assemblers outputting the items in a sorted fashion, where each belt only ever carries a single type of quality, ordered from left to right in increasing quality.

Finally, the goal that I’ve been interested in from the get-go – and the hook already seen at the start of this post:

Full automation of legendary items.

This method encapsulates the entire prediction and crafting loop into a closed system, which can do the entire thing (predict and craft) autonomously. We have seen how we can compute the current state, and predict the next states. But how does this let us force RNG values of our desire?

The answer is the simplest of all: It doesn’t. At least not directly.

Instead, we can make use of the fact that the sequence of the RNG outputs is deterministic. By consuming the bad RNG calls which would need to occur before our desired one, we can “force” the RNG to next output a desired value – such as one which upon use in the quality rolling code immediately upgrades from common to legendary quality. For this we need something to consume the RNG calls.

One automatable aspect is again the creation of partial item stacks. Unlike before however, we do not care about observing the output of these crafts, but only the number of calls each crafting cycle makes. Additionally quick crafting cycles lead us to maximize the number of calls per second.

As luck would have it we already saw a recipe which consumes many calls and has a tremendously fast crafting speed: Scrap Recycling. It takes 12 calls per completed craft, with a base speed of 0.2 seconds. Note that this holds for the number of completed crafts, i.e. crafts completed by productivity count as well. While this for one means that we scale the calls consumption rate of each recycler with the infinite scrap recycling productivity, this simultaneously also requires additional handling of the productivity.
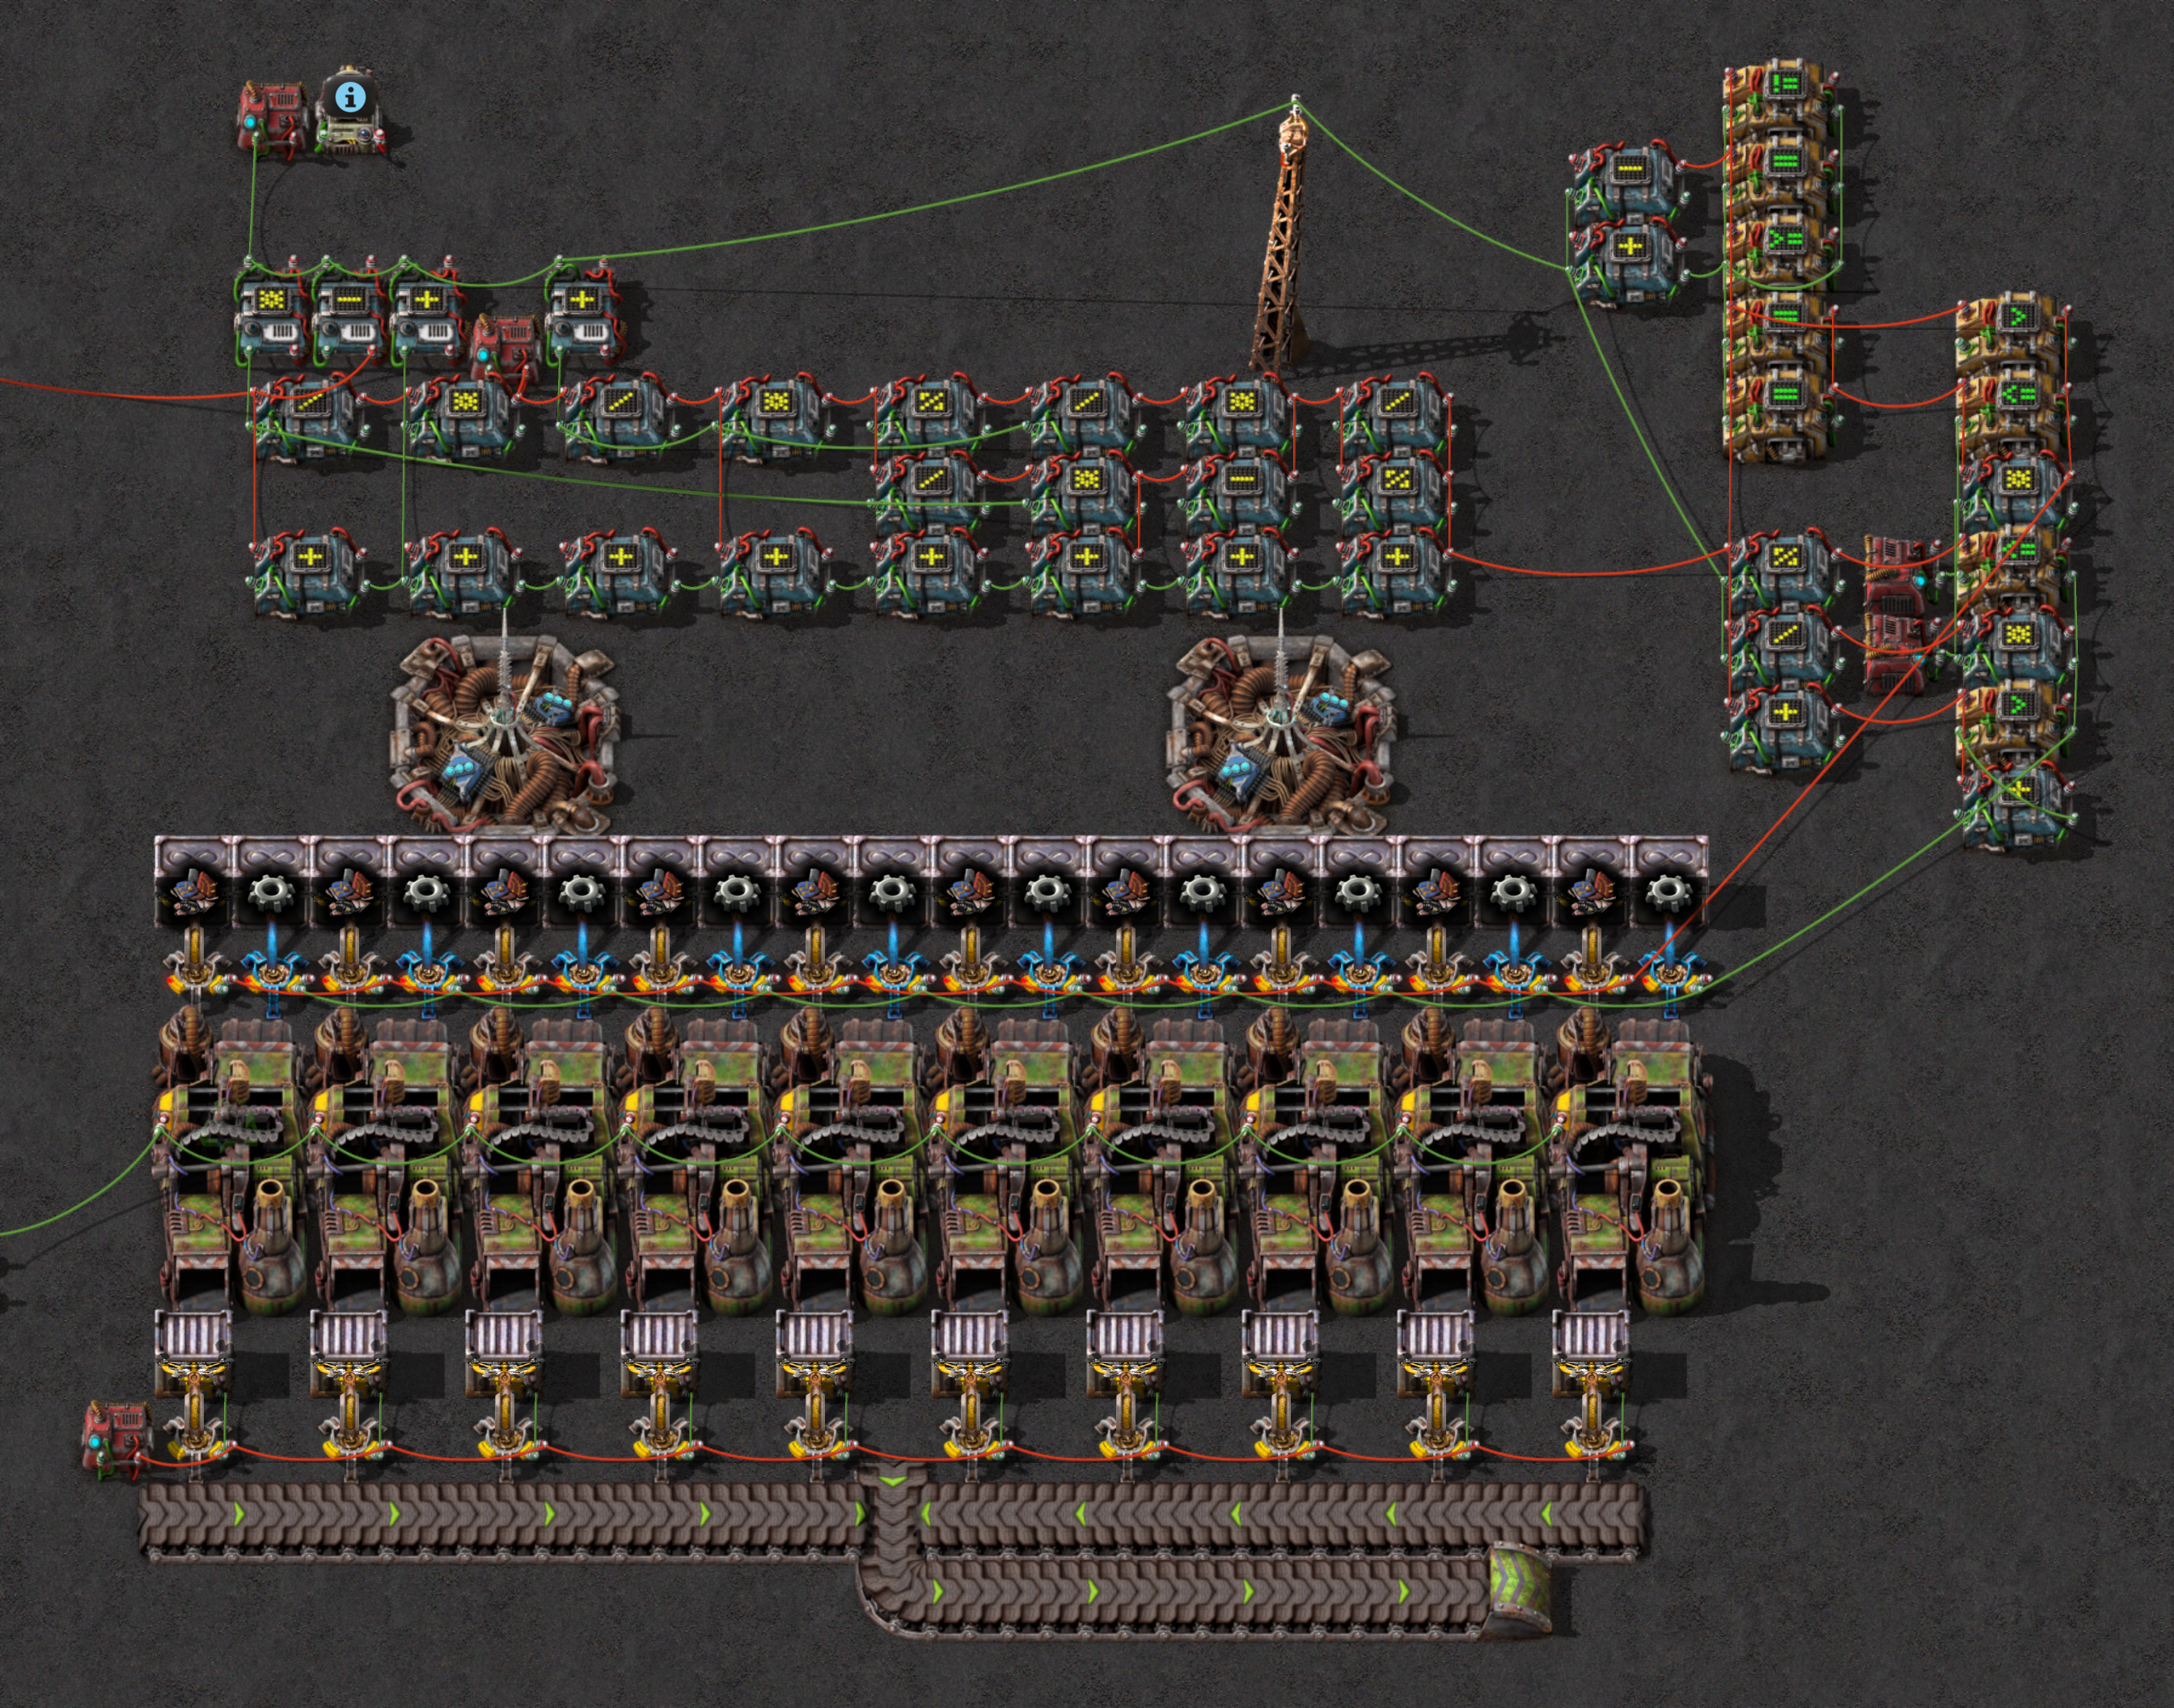
An array of 10 recyclers controlled by combinators ingesting both gears and scrap to skip rng calls. Consuming scrap and gears to skip bad calls.

Using scrap adds complexity due to the following considerations:

  • We have multiple recyclers, so we need to figure out how much scrap each gets, and how many get an additional one? The last part helps reduce the number of items of the last stage.
  • Recycling scrap steps rng calls per craft which is not fine grained enough to resolve an exact state. The remaining number of necessary calls are padded with crafts only eating a single call each. Here these are gears.
  • We also need to consider crafts completed due to scrap recycling productivity which occasionally leads to multiple crafts finishing for a single input item. This causes the RNG to be queried for multiple recipe results, i.e. a multiple of the 12 calls.
  • Each recycler is started with at least 1 gear before scrap to reset the previous productivity progress allowing us to avoid tracking that as well.

There are two additional considerations to make. First of all, while we could increase the amount of calls simultaneously predicted in the forwards pass, this will bloat the save / blueprint and does not scale well past a couple thousand calls per pass. Instead, we can simply feed the output of the last computed RNG states back into the RNG forwarder in a feedback loop.
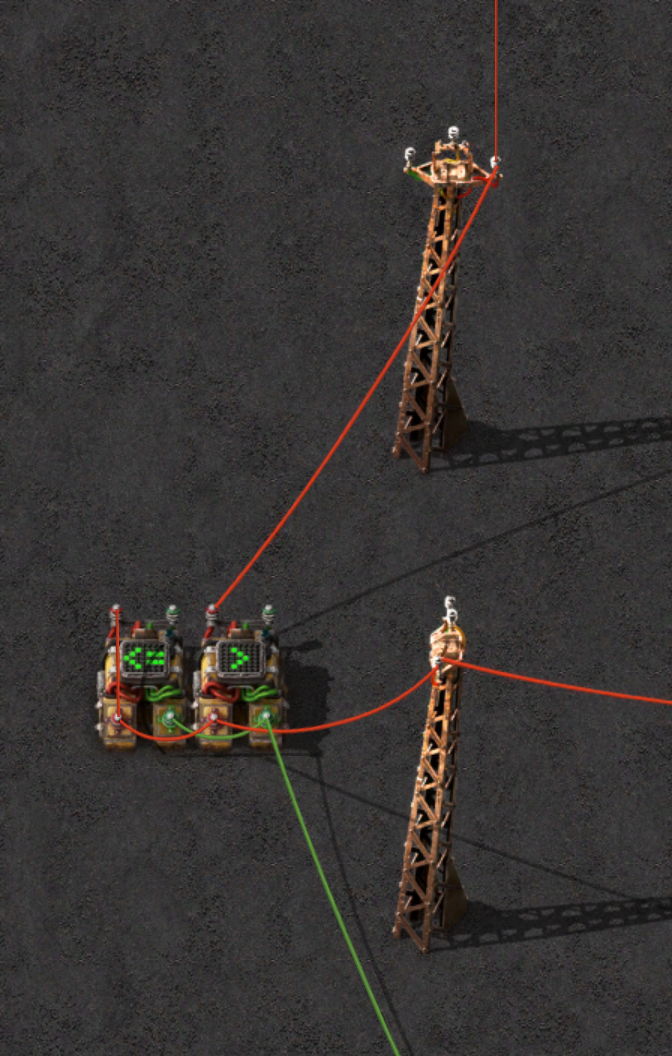
The two combinators feeding the output from the simulation back towards the simulator input. Feeding the forward simulated RNG registers (right) back into the simulator (top).

The first 2 adapters could simply ingest the output of the quality prediction module. To somewhat decouple the prediction and skipping ahead, I decided to decouple the 2 systems, by buffering known good offsets.

For this, as before I compute the threshold which needs to be passed, and now unlike before: Filter out the relevant call indices / offsets and only store those instead. This is done by remapping the passing signals into a sequence of new signals, one for each good offset, as seen in the image below. The remapping is done at 1 signal per tick. Once all passing signals of this iteration are consumed, the above feedback loop is triggered to advance to the next 1000 steps.
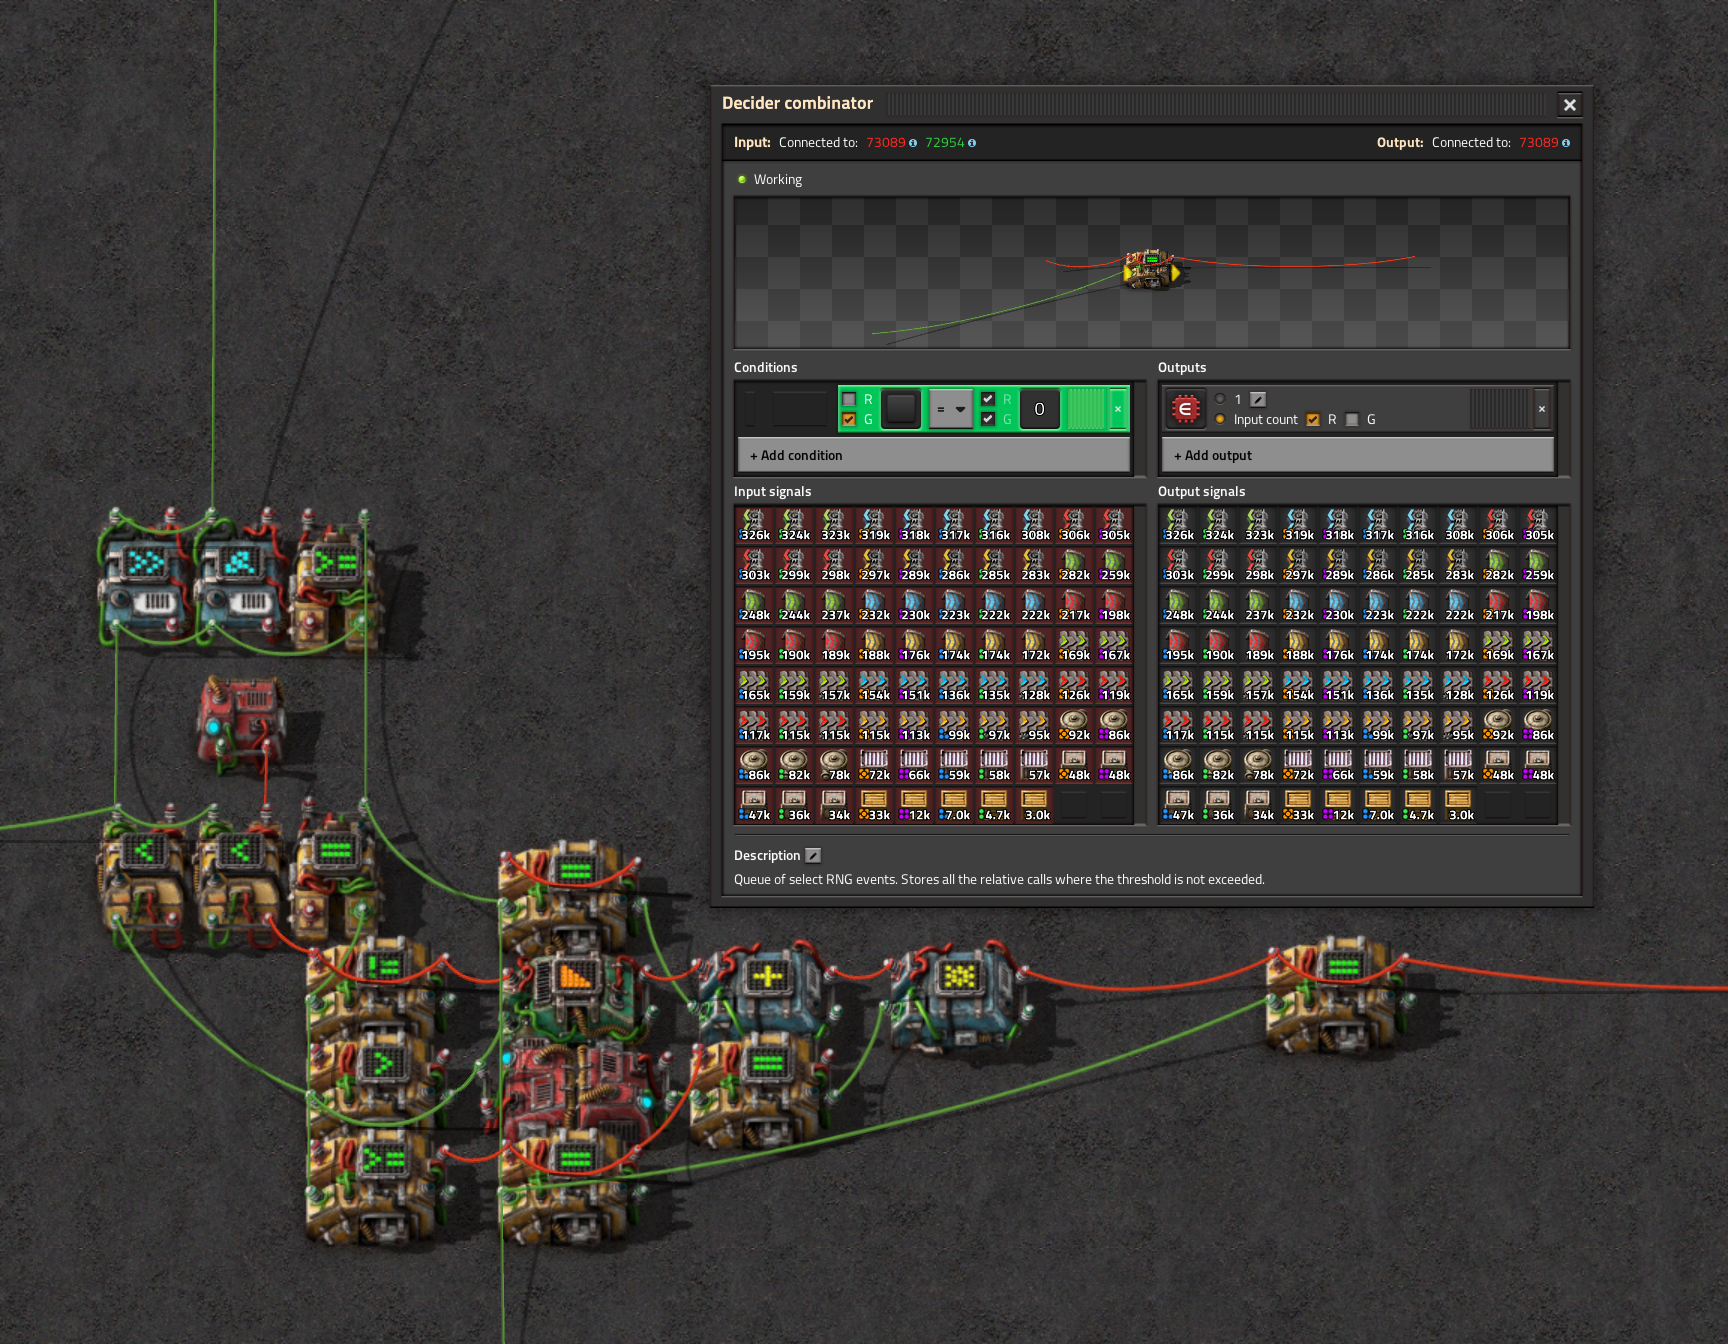
A view into the buffer combinator filled with filtered good quality call offsets. A buffer stores all "good" RNG offsets. Prediction state after about a minute.

As this buffer stores absolute offsets from the first time we measured the RNG, we need to compute the number of calls to actually skip to arrive at the next index. For this we fetch the current and the next index from the buffer and subtract their offsets, yielding the delta. This delta is then what is actually fed towards the skipper. The next number of steps is fetched only after the skipper has finished with the current cycle of skipping and creating the next item.
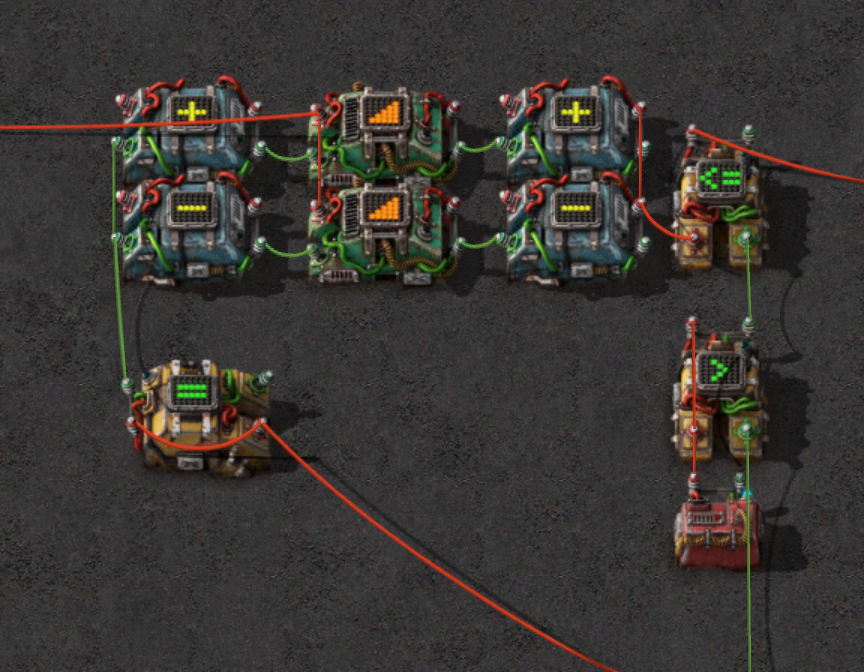
Two selector combinators indexing into the buffer, computing the difference between two adjacent calls. Computing the number of calls to skip subtracting two adjacent buffered offsets.

Lastly, we have the issue that the simulated registers may diverge from the actual game RNG state – for instance if any other process has consumed a RNG call unbeknownst to us. While we can not prevent such intermittent calls, we can at least detect them. In this instance our predictions will diverge from the actually observable crafting results. As such, when too many results (2) differed from our expected quality, we can simply restart the machine automatically, triggering another full state observation and forwarding future states from there on.
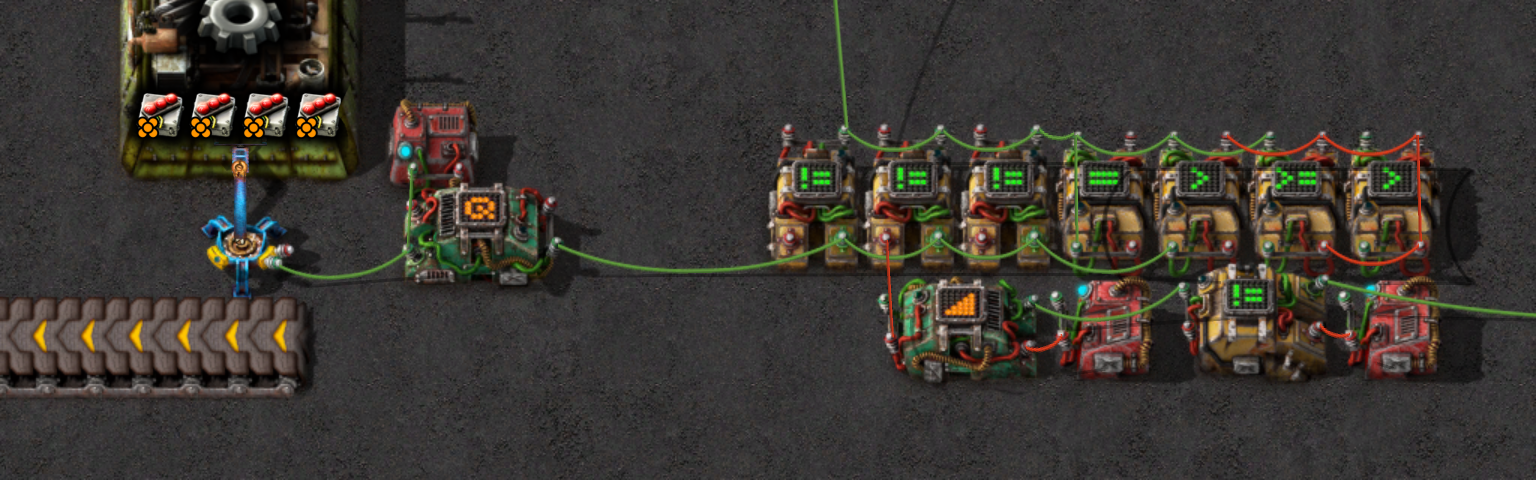
The assembler output inserter connected to the thresholding circuit on the right. Divergence detector and auto resetter.

Below we now see the entire machine in its full glory. I’ve highlighted the different modules corresponding to the individual segments we constructed previously. The general data flow can be read as starting from the bottom left (the assembler) going clockwise: Readout (lime), prediction (blue), filtering (yellow), buffering (purple), skipping (black).

The final overarching view of the fully automated crafter.

Limitations

Now to the important part, that you may be wondering about:

Sweet! Can I use this to now do <insert RNG manipulation target> in my save-game?

The short answer: Very unlikely.

But why? It’s not that I want to keep this tech for my self. In fact, here is the world download, a blueprint string and the relevant cleaned up python code for you to play with. No, it rather has to do with the way that Factorio currently handles their random generators.

For this we can take another look into the game binary. After browsing a bit we encounter the Map object, which among other things as references to the individual surfaces (i.e. the different layers of the world, like the planets Nauvis, Fulgora, and so on). The RNG states however are not stored per surface, but rather globally for the entire map. And notice that I am speaking of states (i.e. plural) as there are actually multiple RNGs in game, each responsible for some of the game’s logic.

The Map in particular stores the following six RNGs (names from the pdb). Try to guess what each one is responsible for:

  • Map.aiRandomGenerator
  • Map.entitiesRandomGenerator
  • Map.generalRandomGenerator
  • Map.mapRandomGenerator
  • Map.triggerRandomGenerator
  • Map.unsafeRandom

To be honest, I still don’t know what some of them do, I was only interested in the one relevant to item crafting procedures.

Here we can already see a saving grace for RNG manipulation. Not all random effects are handled by the same RNG, and thus we can at least isolate some of them from the rest of the game logic. For instance, the RNG responsible for the biter spawning and pathing is separate from the RNG we are interested in.

In particular this is the generalRandomGenerator, which is responsible for the item creation. As its name implies, it is the general random generator, meaning there is still some overlap with other game logic. Either completely unrelated to item creation, or through other recipes which also have probabilistic outputs. This is exactly the issue with the non-isolated cases I talked about previously.

First a non-exhaustive list, of instances unrelated to quality rolling:

  • Floor tiles changing via the MapGenerator::clearEntitiesAndSetTile function, which randomly chooses from variants. This can happen due to manual edits via the editor, through the freezing logic changing tiles, tile ghosts being constructed, or a space platform building some flooring.
  • Name randomization of entities like labs and train stops,
  • Player manually mining ore (particle spawning) or walking over dusty ground (creating dust particles),
  • Particles in general i.e. ParticlePrototype::getRandomVariation and Smoke constructor,
  • Selector combinators initialize their own RNG with a random seed,
  • Mining drills with a single ore tile running out randomly shuffle all remaining tiles they mine,
  • Lightning strikes on Fulgora,
  • Spidertron leg placements when walking

Secondly, all machines requiring any sort of randomness share the same RNG. Any time another (by my machine unexpected) recipe uses the RNG – for instance your scrap recycling line on Fulgora, uranium processing on Nauvis, or any other quality rolling – then the state of the RNG will change, causing the predictions of my machine to diverge from the actual game state, making it impossible to reliably manipulate the RNG towards any specific goal. Moreover, consider that in a game about automation one usually scales up to produce large volumes of items, leading to potentially thousands of calls occurring in just a second, outpacing my capabilities of precomputing the RNG fast enough.

While it might be possible to account for all / many of the randomness sources above, e.g. by dynamically disabling any other production lines doing random calling using for example a logistics group, and waiting for daytime on Fulgora it may be possible to apply this in an actual game save, it should be taken into account from the get-go, rather than being retrofitted into an existing save.

If anyone wants to give it a shot, feel free to try and let me know how/if it works out.

Factorio 2.1

With the last major update to Factorio, the way the RNG is used has changed. While they still use taus88 as the underlying generator, they have fundamentally rewritten major parts of the item creation logic, reusing a single call for multiple item outputs.

Additionally from what I can currently tell, now every single crafting operation uses the RNG, even if it is deterministic, to fill the shared call field in case anything later on will require it. This means that no other machine can run in parallel, as it will always interfere with the RNG state.

Moreover, due to the sharing of the rolls, using scrap recycling to skip the RNG forwards is no longer useful, as the RNG is queried the same amount for any recycled item, and dealing with scrap recycling productivity and its many outputs increases the overhead a bunch. As such this could be replaced with the recycling of any other simpler/cheaper item instead – at least it’s no longer directly bound to Fulgora.

Lastly, while the update is still in the experimental branches I have been somewhat on a rollercoaster ride seeing different changes to the RNG system. At one point, the Map::generalRandomGenerator was used to control the FISH motion. This of course would be a huge problem, as it meant that any fish on the map generated an unknown number of RNG calls, leading to it continuously desynchronizing the RNG state from the predictions without any feasible way to account for it shy of removing all fish from the map (without generating any new chunks with new fish). Thankfully, this was changed in a later update (its gone in version 2.1.13) with a new seventh RNG on the Map object, called Map::fishRandomGenerator. Guess what its job is :)

However its not all bad. For instance, with the forced move away from scrap recycling, and the addition of universe wide signals (allowing us to send when Fulgora lightning storms start to other planets) we are no longer bound to any specific planet, and could instead build the manipulator on Vulcanus, gobbling up however many resources the skipping now requires, sending a signal to any other planet to craft local legendaries when the RNG is in the right state.

For now, I will leave it at that, as the game may further change while it is still in experimental, so any updates to the cracker might just get broken by the next update without notice.

Conclusion

This marks the completion of a two+ year project, finally reaching the fully autonomous gamblen’t I wanted from the beginning. Though to be fair, most of the latter part was me procrastinating on writing and publishing this post. In the meantime (while I was dragging my feet), others have also looked into the RNG, who I’ll link here for reference:

  • @kovaxis in the Factorio forums, reaching and stopping at a similar point as I did initially, where the state is computed with an external python script from some in-game observations.
  • @d4s_over_dt4 on the Factorio discord, who built a combinator circuit to compute the RNG state, read out from 3 placed selector combinators (which each query the general RNG to seed each combinators own state), without further followup integration or verification.

Boy there were quite some tangents along the way which did not even make it into this post, as its long enough already, such as me partially recreating cnide with improved handling for subnets just for documentation and simulation purposes as with syntax highlighting in vscode, or the first implementation attempt where I did all the matrix math in game, including the creation of the matrix and Gaussian elimination of said matrix.6

Thanks go out towards

  • @earthcomputer and co. who unknowingly inspired this project, as their “Mess Detector” reads out Minecrafts RNG state with only in-game mechanics,
  • @redruin1 with their factorio-draftsman library allowing for easy procedural blueprint creation,
  • the Binary Ninja team for a decompiler which does not shit itself7 actually works when encountering the relatively chonky factorio.exe,
  • and everyone close to me who bullied me into finally finishing this writeup after hearing me rambling about RNGs for the past 2 years :)
Read the whole story
emrox
8 hours ago
reply
Hamburg, Germany
Share this story
Delete

Let’s Use the Emergent CSS random() Function in all the Browsers | CSS-Tricks

1 Share

The creator of the TV show The Good Place wrote a tie-in book about moral philosophy which includes a chapter called “The Luck of the Draw,” discussing how the myth of meritocracy leads people to “underestimate the role that luck has played in their lives.” Given how God seems to play dice with the universe, there is something compelling in the way art imitates life when websites embrace controlled chaos in their designs. The jury is out on whether extreme versions of this nondeterminism such as generative UI are a helpful usage of unpredictable UX. Indeed, when I see the YouTube comments reacting to Google’s upcoming usage of GenUI in search, maybe it’s taking the idea too far down a bad path. But there is still something about the idea of a webpage that exists in a state of subtle flux each time you land on it, the same way you can’t step into the same river twice.

Real-world use cases for randomness

I’m a consultant who often works on short-term, greenfield projects, which provide me with a window into the zeitgeist and the trends companies think are the future. It’s no coincidence that the idea of randomness permeated one of my recent projects. That’s epitomized by a burst of confetti to give the user a sense of excitement when they run a random draw they configured. And like many a UI feature in the corporate world, the simple idea of confetti was subject to several revisions to make every randomized particle align with the client’s brand.

In fact, the requirements became custom enough that we ended up ditching the JavaScript plugin we were using and rolled our own confetti implementation! This illustrates the tension between the conflicting needs for chaos and control in UX, even in a fun feature like random confetti.

Wouldn’t it be nice if we could wield controlled presentational randomness in the presentation layer without leaving CSS?

If unpredictable user experiences are having a moment, it follows that CSS will do its part to make randomized layouts easy to implement. The creators of CSS have always been on a mission to harvest common UI patterns into declarative CSS standards. In keeping with that spirit, we see that in late 2025, Safari became the first browser to support the CSS random() spec, as part of an update that emphasized “letting you solve common use cases with HTML and CSS alone, paving the cowpaths, and reducing the need for JavaScript or third-party frameworks.”

Since then, cool demos and discussions of random() keep popping up. For instance, Schalk Neethling showed us how CSS random() can give us fine-grained control over the infamous confetti effect, and Alvaro Montoro made a strong argument that CSS turns out to be the most suitable language for such tasks. He points out this approach is in line with the Rule of Least Power, which encourages “solving a problem using the least powerful language capable of expressing and solving it.”

Now the bad news: half a year after Safari introduced CSS random(), there isn’t clarity on when it will land in the other browsers. At time of writing, there are signs of life that both Chrome and Firefox have been working on it, but no guarantees about when we will be able to use it outside of the Apple world, even behind a browser flag.

So, it seems currently I can only try the online demos of CSS random() on my work MacBook and not on my PC where I do my personal projects. I am tempted to write my own implementation, but the syntax is surprisingly intricate, mostly because of elaborate random caching and keying semantics, combined with the options for base values and intervals. Even if I could manage to get all those details correct, CSS random() is part of an editor’s draft spec that’s in the “early exploration phase” and “major breaking changes are expected.”

On top of that, from my dive into CSS polyfills in my article on ::nth-letter, we know the whole idea of a CSS polyfill can be a minefield.

With all these obstacles in mind, a person would have to be a special breed of crazy to attempt to polyfill CSS random().

Let’s polyfill CSS random()

One of the commenters on a neat YouTube demo of the feature marvelled that it’s a “feature that works ONLY IN SAFARI?!? Did the Earth get flipped upside down?” Indeed, I am more accustomed to getting my first opportunity to experience emergent features in Chrome, which means my friends on iPhones often can’t run my experiments.

And yet, in the case of random(), it’s darkly poetic that a feature based on chance appears in an unexpected place where many of us can’t use it. In fact, even Safari users may benefit from my css-random-polyfill package, because Safari updates are tied to the OS, meaning not everyone can upgrade to the latest version of the browser. Besides, we know how much Apple loves it when you hack their stuff to improve compatibility.

Jokes aside, Apple seems serious about the “hackability” and transparency of everything about the open source WebKit engine that powers Safari, and most of the demos I’ve used to test my polyfill are forks of demos from the WebKit blog, in which the Apple Safari team showed off the possibilities for CSS random() back when it was in Safari preview.

Demo: Random starfield

Here’s my cross-browser version of the first demo from the Safari team’s article. It’s a randomly scattered field of stars fading in and out at random intervals. The larger, four-pointed stars all tilt at the same randomly selected angle. All stars have subtle, randomly hued shadows around them.

To migrate the Safari-only original to a version that works in Chrome and Firefox, we need to change the HTML to reference my polyfill script and add the randomized marker class to all elements that we want to polyfill.

<!-- the script processes usages of css random on page load -->
<script src="https://unpkg.com/css-random-polyfill@latest/dist/css-random-polyfill.js"></script>

<!-- 200 star divs, we add the "randomized" marker class so css-random-polyfill knows which elements to target  -->
<div class="randomized star"></div>
<!-- etc. -->
<div class="randomized star fourpointed"></div>

As for the CSS, unlike my :nth-letter polyfill which uses a nonstandard selector that has to be translated into valid CSS at runtime — and introduces drawbacks in the process — this time we need to support a new function in CSS instead of a new selector. It turns out the CSS we can use in this situation is technically valid, even in browsers that have never heard of CSS random(). More later on why it is valid, but for now, just notice that anywhere we want a random value, we store it in an intermediate custom property, and we always have to follow the convention that the property name starts with the prefix --random.

.star {
  --random-star-size: random(1px, 7px, 1px);
  background-color: white;
  border-radius: 50%;
  aspect-ratio: 1/1;
  width: var(--random-star-size);
  position: fixed;

  --random-top: random(0%, 100%);
  --random-left: random(0%, 100%);
  top: var(--random-top);
  left: var(--random-left);

  --random-hue: random(0, 360);
  filter: drop-shadow(0px 0px calc(var(--random-star-size) * 0.7) oklch(0.7 0.2 var(--random-hue)))
    drop-shadow(0px 0px calc(var(--random-star-size) * 3) white);
  mix-blend-mode: hard-light;

  --random-speed: random(2s, 5s);
  animation: fade-in var(--random-speed);
  animation-iteration-count: infinite;

  --random-delay: random(2s, 5s);
  animation-delay: var(--random-delay);
  animation-direction: normal;
}

This starfield demo showcases a few different variations of the supported random() syntax, such as the optional third argument for specifying a step interval which, in this case, is used to randomly select only whole number values within the range:

--random-star-size: random(1px, 7px, 1px);

…and the element-shared base value, which we use here to tilt every four-pointed star by the same randomly selected angle.

.star.fourpointed {
  --random-rotation: random(element-shared, -45deg, 45deg);
  rotate: var(--random-rotation);
}

Note: In the original starfield demo, most of the random values were used inline, which is admittedly more elegant. The spec that includes random() makes it clear that this kind of function “can be used in place of any part of any property’s value,” just like calc() or min(). So, by requiring extra ceremony and conventions, the polyfill is supporting a subset of what we will get with native random(). To see the glass half-full, it means the CSS stays compatible with the native implementation: we could delete the script reference to the polyfill once native support goes baseline and our code will still work, like it does today when it detects native support in Safari. in this case the polyfill does not process random() calls at all and it lets Safari do all the work. This is a compromise I can live with, especially if the alternative is to press our noses against the glass of Safari-only demos on YouTube and make comments such as one viewer did: “Can’t wait to use this in prod in 4 years.”

Demo: Random Colored Grid Cells

Chris Coyier said of the original starfield demo from Apple that he found it “pretty darn compelling!” I agree, and when I was testing my polyfill, that demo was fun to watch randomly twinkling, refresh and see the stars scatter differently using an emergent, declarative CSS standard. By contrast, I can’t say I have ever sat around wishing I could create a 100×100 CSS grid with randomly multicolored cells, so this example from the Safari team feels a bit like a contrived excuse to randomize something. However, it did help me test the polyfill support of a few different variations of the syntax.

The polyfill allows for some flexible syntax. You can see that references to custom properties passed to the random() function get substituted as expected, and you can see that inlining multiple random() calls in the same value works. For example, we can create a grid-area shorthand property value with randomized row-start and column-start values.

.rectangle {
  --random-grid-area: random(1, var(--rows), 1) / random(1, var(--columns), 1);
  grid-area: var(--random-grid-area);
}

Demo: Wheel of fortune

This example is from Tim Nguyen from the Safari team. To continue the themes of chance and synchronicity, I’ll mention that I had the good fortune to meet Tim last year when I spoke at Web Directions 2025My talk came right after his talk, and now that I’m forking his CSS random() demo to create a cross-browser version, he is once again a tough act to follow.

You can see in this example that the final random position of the wheel uses a different unit for its step interval parameter than for the minimum and maximum parameters.

@keyframes spin {
  from {
    rotate: 0deg;
  }
  to {
    rotate: var(--random-rotation);
  }
}

#wheel {
  --random-rotation: random(2turn, 10turn, 20deg);
}

The mix of types is supported because the specs say the values must be “resolvable to the same data type,” so we are able to mix units as long as they are in the same “overall data type,” such as turn and deg, familiar from the way CSS calc() adds values with different units when it makes sense, using CSS typed arithmetic.

Note: To make the demo work with the polyfill, I had to define the variable in a CSS class that will be applied when the polyfill first loads, in contrast to Tim’s original demo which uses the random() function inside a keyframes animation that was applied based on a checkbox hack. That’s because, for now, the polyfill only processes the computed styles that are applied to elements when the page first loads. Since all my tests pass with this implementation, I am leaving it like that for now in the interest of doing the simplest thing that could possibly work. There are ways we could explore to make the polyfill react to dynamic changes to the computed styles and/or the DOM.

Demo: Random squares

Chris Coyier has a knack for writing code that’s either as tricky or as simple as needed to get his point across, and his CodePen “Very basic random() in CSS” is maybe the simplest demo of CSS random() possible, showing three randomly positioned squares with random colors. Below is my cross-browser version, which I also modified to randomize the size of the squares, as a test that my polyfill supports random value sharing using custom keys.

Here is the code I added to make each square have a random height that is equal to its random width:

--random-height: random(--side, 40px, 100px);
--random-width: random(--side, 40px, 100px);

width: var(--random-height);
height: var(--random-width);

This reassures that we are supporting the correct syntax. Admittedly, custom keys will be more useful in the real native version, which won’t need the intermediate variables. Since we are using intermediate custom properties, we could just have used one custom property named --side and referenced that for both the height and width values.

Chromium-only bonus demo: Simulate random-item using a custom CSS function

Many of the above demos include random colors. That’s achieved by passing random numeric values into CSS color functions such as rgb() or lch(). But if we had a list of specific colors we wanted to randomly choose from, we can’t do that easily, which is why the spec for the CSS values and units module mentions the random-item() function, although no browser currently implements it (except for experimental support in safari preview). If we had this function, we could select a random color or anything else from an arbitrary list of values:

random-item(element-shared, red, blue, green);

The random-item function takes a mandatory first argument of the type random-caching-options, the same as CSS random(), but then it takes a variable length list of arguments to randomly select from, rather than a minimum and maximum value.

I don’t feel like complicating the polyfill to support a CSS syntax that isn’t implemented in any browser — evidently I only give myself permission to do that once a year. But now that we have a version of CSS random() in Chromium which also supports CSS custom functions and inline conditionals, it’s hard to resist seeing what happens if we combine all these weird and wonderful things into one experiment. It turns out these features together can get us pretty darn close to the functionality we’d get from random-item().

--random-index: random(element-shared, 1, 5, 1);
--random-color: --item(var(--random-index), aqua, purple, pink, grey, green);

If you’re using a Chromium-based browser, you can see the code in action in this version of the squares demo which sets all three elements to the same color randomly selected from the list.

The implementation of my generic --item custom CSS function takes an --index argument followed by 10 optional arguments. These could be increased to any number of arguments you think will be the realistic maximum size of a collection you would need. Each of the optional arguments is made optional by defaulting it to an empty value, so the caller of the function only needs to pass in the arguments it needs to index. Lastly, the function maps the --index to the argument at that index, because CSS custom functions do not support variable length collections of arguments the way JavaScript functions do.

@function --item(--index,
  --arg-1: ,
  --arg-2: ,
  --arg-3: ,
  --arg-4: ,
  --arg-5: ,
  --arg-6: ,
  --arg-7: ,
  --arg-8: ,
  --arg-9: ,
  --arg-10: ) {

  result: if(
    style(--index: 1): var(--arg-1);
    style(--index: 2): var(--arg-2);
    style(--index: 3): var(--arg-3);
    style(--index: 4): var(--arg-4);
    style(--index: 5): var(--arg-5);
    style(--index: 6): var(--arg-6);
    style(--index: 7): var(--arg-7);
    style(--index: 8): var(--arg-8);
    style(--index: 9): var(--arg-9);
    else: var(--arg-10);
  );
}

Sidenote: This generic helper function is interesting, because Temani Afif has demonstrated cool use cases for being able to choose from a list of colors using an --index variable, but the solution he created was specific to the color data type and he freely admits it’s “more of a hack than a CSS feature. So, use it cautiously.” By contrast, the custom function approach will work with a list of any data type, and I wouldn’t describe it as a hack because it’s using CSS standards as intended, albeit emergent standards that aren’t available in all browsers just yet.

How the polyfill works

Now we have gained confidence in our random() polyfill, you might be curious how it works. Is this a good time to level with you and say I don’t fully know? That’s a very 2026 predicament, but thankfully it’s not because of AI.

As I hinted at the start, my level of eagerness to use new CSS syntax before it’s supported is matched only by my level of laziness to implement and maintain my own version of random(), so I went hunting for an open source JavaScript implementation and was pleasantly surprised it exists!

As you might expect, it’s not designed for the exact purpose I want it for. it’s in an implementation that’s designed to be used at build-time rather than on the client, as a PostCSS plugin. Digging through the source we see that this plugin wraps the MIT-licensed @csstools/css-calc which has no dependencies and isn’t coupled to PostCSS. The Readme for this package says it only implements the older CSS Values and Units Module Level 4, but we see from the commit history that it’s recently had an “update to latest spec” of random() and we see it passing automated tests for the kind of random goodness we have been enjoying in this article.

My main question is how on earth we are going to hook it up to client-side CSS, but it turns out not to be too much custom code:

import { calc } from "@csstools/css-calc";
const calcFn = calc;

if (!CSS.supports("width", "random(0px, 100px)")) {
  const styleTag = document.createElement("style");
  styleTag.textContent = ".randomized { display: none; }";
  document.head.appendChild(styleTag);
  const elementIDs = new WeakMap();
  const documentID = crypto.randomUUID();

  document.querySelectorAll(".randomized").forEach((element) => {
    const styles = getComputedStyle(element);
    [...styles]
      .filter((property) => property.startsWith("--random"))
      .forEach((propertyName) => {
        const css = styles.getPropertyValue(propertyName);
        const value = resolveRandom(css, {
          element,
          propertyName,
          documentID,
          elementIDs,
          calcFn,
          crypto,
        });
      element.style.setProperty(propertyName, value);
    });
  });
  if (styleTag.parentNode) {
    styleTag.parentNode.removeChild(styleTag);
  }
}

function resolveRandom(css, { element, propertyName, documentID, elementIDs, calcFn, crypto }) {
  const patchedCss = css.replace(
    /random\(\s*(?!(?:[^,]*\b(?:shared|scoped)\b|fixed\b|--))([^,]+),/gi,
    (_, expression) => `random(fixed ${Math.random()}, ${expression},`
  );

  return calcFn(patchedCss, {
    precision: 5,
    toCanonicalUnits: true,
    randomCaching: {
      documentID,
      elementID: elementIDs.getOrInsert(element, `element-${crypto.randomUUID()}`),
      propertyName,
    },
  });
}

Let’s translate this code into natural language steps:

  1. If we detect that the browser supports native CSS random(), then the polyfill will do nothing and let the browser handle any calls in CSS to random().
  2. If it doesn’t support the feature, we temporarily hide all elements marked as .randomized to prevent a flicker.
  3. We loop through all the --random prefixed properties in any element that has the  .randomized CSS class.
  4. For each --random custom property, we take advantage of the fact that the “allowed syntax for custom properties is extremely permissive,” which means that even if the CSS parser does not understand an expression used in the value for a property such as --random-grid-area: random(1, var(--rows), 1) / random(1, var(--columns), 1), the value will be parsed into a string which can “be read and acted on by JavaScript.” The browser will also resolve any calls to var() and substitute those into the computed value, regardless of any surrounding gibberish it can’t interpret.
  5. We generate unique surrogate identifiers for the document and each randomized element we pass to @csstools/css-calc together with the expression string that contains each usage of random(). This allows CSS Tools to respect the random caching rules such as element-shared.
  6. If no base is specified in a usage of random(), the library doesn’t seem to generate evenly distributed values (for example, the stars in the first test kept ending up in weird clusters), so we break out the proverbial duct tape and patch the problem by injecting a fixed randomly generated base value if the user didn’t provide one.
  7. Using the value we get back from @csstools/css-calc interpreting the random() call, we set the property to that value with an inline style on the randomized element.
  8. We remove the class declaration we injected to hide the randomized elements while we were resolving them.

Point 4 is a big deal. Interpreting arbitrary custom property values using CSS is the closest we have in present day CSS to an honest-to-goodness documented extension point for the language. Since arbitrary expressions in custom variable values are valid and can be read by JavaScript via the computed styles, this approach has the potential to avoid many of the known downsides of polyfilling CSS such as refetching and rewriting stylesheets, doing our own parsing of CSS, and other fun but dangerous pastimes.

Random parting thoughts

Fittingly, it’s only by good luck that an open source project has already done most of the work we need to be able to run CSS random() in any browser while we wait for native support. A lot of people claim they can’t wait for this feature to be available in more browsers, so it will be interesting to see whether people choose to wait now that a polyfill exists. Seeing Chris Coyier’s reaction to the starfield demo, his enthusiasm was contagious! I had a similar moment when I first got the demo working in other browsers. Let me know if having this polyfill available sparks creativity for your own projects. I definitely have ideas for some more advanced use cases for it, which is what prompted me to polyfill it.

Till next time, happy randomizing from your friendly neighbourhood random guy.

Read the whole story
emrox
8 hours ago
reply
Hamburg, Germany
Share this story
Delete

Gridfinity - Wikipedia

1 Share
Standard for physical object storage
A 3D-printed drawer with a 4×3 Gridfinity baseplate and an 1×3 Gridfinity bin, used to store toothpicks

Gridfinity is an open standard describing a 3D-printed modular storage system for physical items.[1]

It defines a quadratic grid "baseplate" in which plastic bins and other receptacles are arranged. The components' dimensions are multiples of 42 mm in width and breadth, and multiples of 7 mm in height, allowing components of varying sizes to be arranged and stacked efficiently.[1]

The 3D prototyper Zack Freedman designed Gridfinity in 2022 to store screws, tools and the like in his workshop in an easily findable manner.[1] Gridfinity was inspired by the "Assortment System" by Alexandre Chappel. Both systems are licensed under an open Creative Commons NonCommercial license.

Gridfinity has been adopted by a broad community of 3D modeling and printing hobbyists.[2][3] They have created a plethora of models of Gridfinity components, as well as parametric generators that create component models for users' specifications.[1]

In a 2026 review of the standard, Yadullah Abidi appreciated Gridfinity's sizeable ecosystem of models and noted that it works well to organize items in small enclosed spaces such as drawers. But he found the baseplate grid unnecessarily restrictive and material-consuming for other purposes, and wrote that the standard's fixed dimensions wasted space when storing odd-sized objects.[4]

  1. 1 2 3 4 Simons, Che (2026-01-22). "3D Print Your Way Out of Chaos With Gridfinity Modular Storage Systems: All You Need to Know". All3DP. Retrieved 2026-07-11.
  2. Peels, Joris (2023-03-31). "Gridfinity Could Bring 3D Printing Into Any Home and Many Businesses". <a href="http://3DPrint.com" rel="nofollow">3DPrint.com</a>. Retrieved 2026-07-11.
  3. Coward, Cameron. "Check Out Zack Freedman's 3D-Printable Gridfinity Organization System". Hackster.io. Retrieved 2026-07-11.
  4. Abidi, Yadullah (2026-06-18). "I tried the 3D-printed organizer the internet adores, and I want my filament back". MakeUseOf. Retrieved 2026-07-11.
Read the whole story
emrox
9 hours ago
reply
Hamburg, Germany
Share this story
Delete

Small Programming Tricks

1 Share

Day to day, I think a surprising amount of engineering productivity comes from small nuggets of knowledge: being aware that a language feature exists; knowing that an unexplained tcp delay is probably related to the TCP_NO_DELAY setting and Nagle’s algorithm; knowing the right git incantation to get out of a pickle; or knowing a trick with sed to rewrite a file.

In one sense, this is self-evident: anything you know is going to be made up of smaller pieces of knowledge. Of course those smaller pieces of knowledge matter.

But I think there are some nuggets of knowledge that are particularly valuable and don’t require a lot of supporting mental infrastructure. You don’t need to know any python to use python3 -m http.server to start a simple server in a directory, but it might still make your work marginally easier. Let me share a few examples:

  • You probably know that ctrl + r allows searching your terminal’s command history, but if you install fzf, you can set it up so that ctrl + r does a fuzzy search. If you want even more power, atuin replaces your shell history with a searchable SQLite database. per-directory-history lets you switch back and forth between searching for commands that have been run in a specific directory or searching all previous commands. Finally, you can configure how much history to store: stackoverflow question.
  • You can SELECT without a FROM. This can be useful for testing out how a function in your database actually works or reminding yourself how SELECT TRUE <> NULL works.1
  • PostgresSQL and MySQL both support explain analyze which will actually run the query you’re trying to optimize and give you a ton more information about its performance.
  • In regular expressions, \b, the word boundary assertion, makes it easy to look for the beginnings or ends of words.
  • You can use logarithms with metrics to get a sense of the distribution of values for a field you’re interested in:
    const bucket = Math.floor(Math.log10(userInGroupCount))
    metrics.increment("my_metric", { bucket });
    
  • Modern JS now supports Array.flatMap, Object.entries, and Promise.withResolvers.
  • In NodeJS, you can keep a connection open to an external resource by creating an https.Agent and then providing it to your http requests: fetch(url, {method, agent}). This can have a dramatic impact on latency.
  • git log -S pattern (”git pickaxe”) can give you all commits that added or removed a string in a codebase. It’s amazingly useful especially with older codebases! (git log -G pattern is similar, but will also show when that line was moved)
  • Similar to cd -, you can use git checkout - to check out your previous HEAD.
  • You probably don’t need find. A lot of find commands can be replaced with globs like **/*.md. Most shells support this out of the box, but with bash, you need to turn this on with shopt -s globstar.
  • In a similar vein, most folks will probably want to use rg (ripgrep) rather than grep, ack, or ag.
  • zsh’s advanced autocompletion features aren’t turned on by default:
    if type brew &>/dev/null; then
        FPATH="$(brew --prefix)/share/zsh/site-functions:${FPATH}"
    fi
    autoload -Uz compinit
    compinit
    

You might have already known all of these things! Or you might work in a domain that makes all of these little tricks totally useless. Even if this particular set of tricks isn’t useful for you, I bet you have your own stash of tricks that you’ve accumulated over the years that makes your work easier.

At a company, I think even more knowledge tends to be this sort of small high-leverage nugget:

  • To debug $PROBLEM, use $DATA_SOURCE.
  • $PERSON knows a ton about $AREA and they’re happy to help if you get stuck
  • There are good docs about $HARD_THING $OVER_HERE.
  • When $THING happens, it means we should manually scale out.
  • To do a rolling restart of a service, run $THIS_COMMAND.
  • This $UTIL makes $THAT_PROBLEM easy to script.

At a previous company, I shared a trick on slack every day with the engineering team, both technical and company-specific, and folks found them pretty useful. Even if you knew 9/10 tricks, that 10th doc or technique might save you some time! And one trick per day was the right number to avoid overwhelming people with knowledge, and it could occasionally spark useful discussion. If you’re a more senior engineer at your company, you might think about doing something similar.

Read the whole story
emrox
9 hours ago
reply
Hamburg, Germany
Share this story
Delete

Interesting articles

1 Share

General

No one actually wants simplicity
Simplicity is sacrifice. See also:
simple made easy (video)
wicked features

Avoid the nightmare bicycle
Good designs expose systematic structure; they lean on their users’ ability to understand this structure and apply it to new situations.

Don't Feed the Thought Leaders
Contingent advice (that depends on the situation) is in general better than generic advice. In my experience, one of the most difficult parts is knowning when you have to deviate from common practices.

Programming

The Configuration Complexity Clock
Programming languages, configuration files, DSLs for configuration

Code is run more than read
A unified theory of broken software

Java for Everything
The advantages of focusing on a single language and how performance and static typing are helpful.

Ostrich algorithm

Finding and Fixing Standard Misconceptions About Program Behavior
About the Standard Model of Languages (SMoL)

Best Simple System for Now
A view I disagree on about IAGNI and the opposite concepts, but interesting

Static types are for perfectionists
Our programming style is influenced by our personality and life

Making wrong code look wrong
The history about Hungarian notations

What We Know We Don't Know: Empirical Software Engineering
40-minute video about the power of proper sleep, working schedules and stress levels vs. engineering practices

We are not special
Second of a series of three articles comparing software engineering with traditional engineering. Mostly dispels some myth and lack of knowledge about traditional engineering.

See also my own "on testing" for further notes about testing, including risk-driven testing, the Beyoncé rule, SMURF, test doubles (dummies, fakes, stubs, spies, and mocks), and classic/mockist testing (also Chicago/Detroit/London).

Python

Python’s "Disappointing" Superpowers
A convincing defense of dynamic typing

Rust

The Mediocre Programmer's Guide to Rust
How to Avoid Fighting Rust Borrow Checker

Optimization

The Oracle Performance Improvement Method
My favorite text about performance tuning- the good advice is not Oracle-specific. Includes a bit more real-world advice than:
Rob Pike's 5 Rules of Programming

The Performance Inequality Gap, 2024
How web bloat impacts users with slow devices
About janky browser applications and websites.

Git

Git Tips 3: Really Large Repositories

Accessibility

The text mode lie: why modern TUIs are a nightmare for accessibility

Systems

In defence of swap: common misconceptions

Technical writing

What I think about when I edit

Organizations

Pragmatism, Neutrality and Leadership
(The parts about "As a leader, your job is to succeed", "Companies with shitty cultures win all the time".) This article connects with:
The no asshole rule book

The Engineer/Manager Pendulum
Why people should multiclass engineering and management

How organisations cripple engineering teams with good intentions
Arguments for having coders code

Generative AI Is Not Going To Build Your Engineering Team For You
Bad title; it's about the need for junior coders

Senior Engineer Fatigue

Things You Should Never Do, Part I
About rewriting software from scratch

Some observations concerning large programming efforts
Someone figured most of it out in 1964.

The tyranny of structurelessness
(My Cliff's Notes)

Well-Kept Gardens Die By Pacifism
About moderation in small communities

On 'scaling up' and being the right size

Project management

An epic treatise on scheduling, bug tracking, and triage
No non-sense opinions on project management I mostly agree with

News

The Truth Is Paywalled But The Lies Are Free
Excellent title, but the article is so-so

Society

Contra la tecnocratización de la vida
About the pressure of the modern age and the privilege of being mediocre

Face it: you're a crazy person
Choosing a job because you like the worst parts of it

Epistemology?

The Relativity of Wrong by Isaac Asimov
All physics theories are strictly "false", but they are very true.

Meta

Essays on programming I think about a lot
A Programmer's Reading List: 100 Articles I Enjoyed (1-50)
matklad's

Infrequent but useful terms

The Abilene paradox
A collective fallacy, in which a group of people collectively decide on a course of action that is counter to the preferences of most or all individuals in the group, while each individual believes it to be aligned with the preferences of most of the others.

The Dunning–Kruger effect
A cognitive bias in which people with limited competence in a particular domain overestimate their abilities. Some researchers also include the opposite effect for high performers: their tendency to underestimate their skills. In popular culture, the Dunning–Kruger effect is often misunderstood as a claim about general overconfidence of people with low intelligence instead of specific overconfidence of people unskilled at a particular task.
A Statistical Explanation of the Dunning–Kruger Effect
This effect might only be caused by subjects in the bottom quartile can only make optimistic errors placing themselves into a higher quartile, while subjects in the top quartile can only make pessimistic errors placing themselves in a lower quartile.

The Gell-Mann amnesia effect
A cognitive bias describing the tendency of individuals to critically assess media reports in a domain they are knowledgeable about, yet continue to trust reporting in other areas despite recognizing similar potential inaccuracies.

Goodhart's law
An adage that has been stated as, "When a measure becomes a target, it ceases to be a good measure".

The McNamara fallacy
(Also known as the quantitative fallacy) involves making a decision based solely on quantitative observations (or metrics) and ignoring all others.

Hanlon's razor
An adage, or rule of thumb, that states: Never attribute to malice that which is adequately explained by stupidity.

The Hawthorne effect
A type of human behavior reactivity in which individuals modify an aspect of their behavior in response to their awareness of being observed.

Novelty effect
An effect of introducing new elements on some activity or behavior.

Sturgeon's law
An adage stating "ninety percent of everything is crap".

Schedule chicken
When two or more parties working towards a common goal all claim to be holding to their original schedules for delivering their part of the work, even after they know those schedules are impossible to meet. Each party hopes the other will be the first to have their failure exposed.

Your radical ideas about society, individualism, and religion have already occurred to others

Lizardman's constant
The approximate percentage of responses to a poll, survey, or quiz that are not sincere

Solomonoff's theory of inductive inference
Under its common sense assumptions (axioms), the best possible scientific model is the shortest algorithm that generates the empirical data under consideration. Solomonoff's induction naturally formalizes Occam's razor.

Planning fallacy
A phenomenon in which predictions about how much time will be needed to complete a future task display an optimism bias and underestimate the time needed.

See also:

Greek task list

Sources:

List of paradoxes
Unintended consequences

Lost and not found

Some articles I'd like to find here, but haven't been able to find again:

  • Enqueuing function calls vs. extending your domain model: This article discussed using traditional queues for handling some actions in your application vs. doing this "declaratively". For example, enqueue "send notification about x to user y" vs. "add column 'needs_x_notification to users table". If I remember correctly, the article contained some insightful arguments for the latter approach I had not thought of.
Read the whole story
emrox
2 days ago
reply
Hamburg, Germany
Share this story
Delete

We are all Product Engineers now

1 Share

Just yesterday I published a very long post about the economics of open source. As part of that argument, I mentioned that the cost of writing software has collapsed, and that meant the variables in the equation had changed for the first time in thirty years.

That led me off on a tangent that grew into this equally long post. I had a bunch of questions to answer. Has the cost of creating software really collapsed? Can I prove that? If the cost of actually producing code goes to zero, what parts of the job of “software developer” really remain? Where, in fact, is the entire industry of software going in the next decade?

You can see why I felt it needed a post of its own.

I’ve been circling this topic for a while now. In early 2025 I predicted AI would create many more programmers and that their jobs would look different, but I didn’t get into the details of how different, and also that was more than a year ago, an infinity in the compressed timeline of AI. In March this year I found companies substituting compute for labor at record rates. In July I looked into labor statistics and found that the market for junior programmers had been savaged while the market for senior ones was fine, in fact growing.

This post is an attempt to build on those and make a forecast of where the industry is going in the next 10 years. Making a 10 year forecast of anything is of course a crazy thing to try to do, and especially about the business of software right now. To make it, I had to make two very big assumptions.

Assumption 1: agents are going to eat the entire software development lifecycle

This assumption is based on the observation that agents are currently very good at writing code and mediocre at everything that comes after that: reviewing code, testing it, finding bugs, fixing bugs, deploying to production, monitoring, and scaling up. They suck at that stuff right now, but my assumption is that that’s a temporary state of affairs. There’s nothing structural about those things that prevents agents figuring out how to do that stuff. If you think I’m right about that, this post will be of interest, but if you think I’m wrong now is a good time to bail.

Assumption 2: there is no upper bound to how much software we need

This one is if anything even more out on a limb. If you think I’m wrong about this you probably think software developers as a profession are doomed. I disagree.

I've made this argument before: look at the website of your dentist, your insurance company, your kid's school, or literally any department of any government, and you're looking at software that is terrible not because nobody knows how to build better software, but because the people who need it can't afford to pay for better at current prices. Then think about all the things software hasn't touched at all, which is most things. Every small business runs on a spreadsheet and a group chat and a person who remembers stuff.

That means there isn’t now and isn’t going to be a glut of software developers, and anything that looks like one right now is a temporary transitional state. The demand for software, at least inside my 10 year horizon, is for practical purposes infinite, or software developers wouldn’t be as highly paid as they are.

But the job of a “programmer” is about to get very, very different. So different that you might not even recognize it as “programming” any more, while still being recognizably “software development”.

The job of making software will become what the agents can’t do

If agents are going to eat the entire software development life cycle, what does that leave behind?

To figure that out, I broke the cost of making software into as many component pieces as I could think of. I came up with a long list, in four categories:

Collapsed:

  • Actually writing code: historically the most expensive part of the whole process, because getting it right was really tricky. The entire industry oriented itself around very expensive programmers as the center of gravity, with every other job more or less orbiting around them. The cost of this, with LLMs, has already collapsed.

Going soon:

  • Reviewing code: I’ve written about the death of the code review before, the TLDR being: it hasn’t happened yet, but it looks like it’s about to.
  • Maintaining code: finding bugs, fixing bugs, refactoring. Agents are making real progress here but are still not great.

Next on the chopping block:

  • Shipping code to production: getting it out of dev onto real production hardware. With various platforms this has been dropping for a while, and my assumption is that agents are about to get very good at it.
  • Scaling up: not something I’ve seen anyone talk about, this is a big part of successful software development. I’ve not seen people throwing agents at production bottlenecks so far.

Possibly safe:

  • Deciding what to build in the first place: figuring out what the customer actually wants is a huge part of software development, and so far I haven’t seen anyone throw an agent at it. To my mind, this is the most durable part of the job.
  • Deciding the definition of “good”: this is the intersection with my day job in the world of AI evaluation. I’ve not seen any attempts to automate this. How would you even know, short of asking a human, what good looks like?
  • Making it delightful: we can all tell the difference between a piece of software that gets the job done and one that’s actually easy and fun to use. Can an agent? The current state of agentic design does not suggest that they can, but this one is the most wobbly of the three.

Then there’s a bunch of things that are arguably not software development at all, but are still part of the software industry: marketing, user acquisition, retention, branding. Who knows what agents can do with them, but I’m not considering them.

All juniors did was write the code you told them to, and that’s gone

I already talked about this in my post about the labor market, so I won’t reiterate the whole argument. The thing agents got good at first was producing code from a description, which is exactly the thing junior developers were hired to do. It was the whole point of hiring a junior: you gave them a well-specified ticket, they produced mediocre code, a senior reviewed it, and over about a decade of that they absorbed enough judgment to become the senior.

The problem from that post is: if you don’t need juniors to handle well-specified tickets any more, where do the seniors come from? We have to train them in a different kind of job. The point of this post is: what job?

Since July the Stanford team has updated their numbers and things did not improve for junior developers. The employment gap for 22-to-25-year-olds in AI-exposed jobs is now 19% below where it would be if they'd tracked their less exposed peers, up from 15% a year ago, and it's happening through reduced hiring rather than layoffs. More interesting is where it's happening: young workers lost ground in occupations built on knowledge that's been written down somewhere, and experienced workers gained ground in occupations built on knowledge you get by doing the job. The Stanford authors call these codified and tacit knowledge, and I'd call them "stuff that's in the training data" and "stuff that isn't", but it's the same distinction, and it maps exactly onto "what juniors do" and "what seniors do." SignalFire's 2026 talent report has the corporate side: entry-level hiring at the big tech companies is down 65% since 2019, at early-stage startups it's down 75%, and yet engineering as a share of hiring went up, from 46% to 55%.

Companies are hiring fewer people overall, but a bigger share of the people they do hire are engineers, just not the kind whose primary job is typing code.

Going soon: reviewing and maintenance

For reviewing and maintenance, agents are clearly not there yet, but the data shows them on an upward trajectory.

On benchmarks where agents fix real bugs in real repositories, frontier models went from roughly 50% to roughly 95% in the last two years, to the point where the main benchmark is effectively saturated and people have had to build harder ones. On the harder ones, which resist the models having seen the answers during training, the best models now score around 59%. That’s not good enough, but neither was 50% two years ago and that went away really quickly.

A study of 567 pull requests opened by Claude Code across 157 open source projects found 84% of them eventually got merged, a bit below the human rate of 91%, and just over half went in without a human touching them. Google's Big Sleep agent found a memory corruption bug in SQLite that traditional fuzzers had missed and that attackers already knew about, and has found around twenty more since in things like FFmpeg and ImageMagick.

Until they do, the ability to create code but not to review it is causing an enormous amount of pain. GitHub added 36 million developers and a quarter more commits in a year, and the number of merged pull requests on the platform is up something like three and a half times since 2023, with one estimate having agents alone opening 17 million PRs a month. Something should review all of that, but one study of 33,000 agent PRs found that most PRs on GitHub, human or agent, get no recorded review at all, and when agent PRs are reviewed, 58% of the time the only reviewer is another agent. In open source, examples abound of projects shutting out new submissions because of a tide of AI slop and the inability to effectively review them; curl shut down its bug bounty in January after the share of submitted reports that were real bugs fell from better than 15% to under 5%.

Next on the chopping block: operations and scaling

For this part of my argument data was really thin on the ground, so I’m relying heavily on my “looks like it’s going to happen” assumption from the start. There are some benchmarks that look more like operating a system than fixing a bug, and agents are somewhere under 65% on them. This isn’t a thing happening yet, which is why there’s almost no data either way. It’s just the thing that, logically, looks like it’s next.

What's left is finding out what people actually want, and only they know

So if the code is free and the operations are free, what’s left? It’s sometimes called "product sense", and it’s highly valued in senior developers, but what does that mean exactly?

At some point every piece of software is a formalization of a human desire. Somebody wanted something, and the software is a precise enough statement of that want that a computer can act on it. When a customer says "I need to keep track of my orders," there are ten thousand pieces of software that fit that sentence, and only one of them is right for a bakery, and it's a different one from the one that's right for a car parts factory, and the only person on earth who knows that the customer is running a bakery and not a parts manufacturer is the customer.

You cannot do product discovery mechanically short of reading people’s thoughts. You can't train it into a model, because it isn't in the training data, because it's in the head of one specific baker who's never written it down and wouldn't know how to if you asked them. Somebody has to go and get it out of her, and then turn it into something exact enough to build, and then check that what got built is actually what she meant, which it never is the first time.

There is no economy of scale in product decisions

The cost of deciding what the customer wants has a very important property: it doesn't transfer well. The definition of "good" for a calendar app and the definition of "good" for a scheduling app, which are two ways of solving roughly the same problem, have almost nothing in common, and two bakeries don't have exactly the same problem either. Whenever you see software with a zillion configuration options that still doesn’t do what you need it to do, you’re feeling this problem. It’s why software so often sucks, and why I say the demand for good software goes to infinity. Software requirements are more different than we’ve been able to admit while we’re still trying to write one-size-fits-all software.

As the cost of software creation falls to zero, the bottleneck moves to the description of the problem, and my thesis is that’s where it’s going to stay.

What about design?

I'd separate out design from this, because it's related but it's not the same thing. Design is the part where two solutions both correctly solve the problem and one of them is the one people actually like using. Everybody who's watched a well-specified product lose to a nicer one knows this is real, and I can't quantify it, and I'm suspicious of anyone who says they can. But I'll note that it has the same structure as the description cost: it's per product, it doesn't transfer, and cheap code makes it more important because when everyone can build the correct thing, the nice thing is what's left to compete on.

The job that remains is called Product Engineering

So what does that leave behind? Let’s talk history for a little bit.

When computers were new and programmers were scarce and expensive, companies hired a person whose entire job was to sit between the business and the programmers, understand what the business needed, and write it down precisely enough that a programmer could build it without talking to anyone. This person was called a systems analyst. There's a 1963 memo from Miami University describing systems analysis as a brand new profession born out of the mountain of paperwork business executives faced: it was the translation layer, created because the people who could type were too valuable to also do the talking (and also, people who were very good at laying down code seemed to be not very good at talking to humans anyway).

Then software went commercial and, especially, consumer-facing, and the translation job changed shape. Consumers don't want to sit in requirements meetings: they just want to be handed a thing they like. So the person whose job was understanding what people wanted stopped being an analyst who interviewed the business and became a product manager who studied the market, a role borrowed more or less directly from Procter & Gamble's brand managers by way of Intuit and then Microsoft, where a programmer named Jabe Blumenthal invented "program manager" in the late 1980s because Excel for the Mac needed somebody to own what it should do.

The function moved into Product, and Product got separated from engineering as a career, and for the last twenty-five years we've had two professions where there used to be one and a half. I bring this up because it means the job I'm describing isn't a speculative new thing that we'd have to invent. It's a thing we've had for sixty years under two names. My speculation is that it’s about to collapse back into one job.

The new job is already being hired for, under a dozen names

You can see the start of this change arriving now: it’s showing up as job postings for a role nobody had heard of three years ago.

Palantir coined "forward deployed engineer" for a person who goes and sits with the customer, figures out what they actually need, and builds it, inside the customer's environment, with the customer watching. It was a Palantir oddity. Then in 2025 postings for it grew by something like eight hundred percent in nine months, and by this month a census counted almost a thousand live postings across 462 companies, including OpenAI, Anthropic, Databricks, Stripe and Google Cloud, with Salesforce saying it wants a thousand of them to roll out its agent products. The average total comp is around $240,000 and senior ones clear $600,000, which is to say it pays like a senior engineer, because it is one. The same role is being posted as solutions engineer, deployment engineer, applied AI engineer, implementation engineer, and half a dozen other things, because nobody has agreed on the name yet, because it’s so new that nobody has standardized it yet.

But read the job descriptions and you see, roughly, a senior product engineer. The responsibilities include: scope the problem with the customer, understand their business, write production code into systems you didn't build, iterate with them until it works. The code-writing is in there, but it's the smallest part, and it's the part the agent does; what the company is paying $240,000 for is the person who can walk into a car parts factory and come out with a correct definition of "good." The market has already decided this job is incredibly valuable.

But that’s not programming!

Here’s the part that’s going to suck for a lot of people who develop software currently: no, this isn’t programming. It’s recognizably still software development, but laying down code is a vanishingly small part of it and, if the trends I’ve laid out here are real, going to get even smaller.

I want to be careful here because “figure out what to build, not how to build it” is also a description of the part of software development I personally always liked, and there's a well-known failure mode where everyone with an opinion about AI concludes that all jobs will be automated except theirs, which is mysteriously impossible to automate. So take this with the appropriate salt: I think the durable, paid part of making software becomes the part where you understand a problem better than the customer does and think harder about the solution than they can, and I think that's durable because it can't be extracted from the customer mechanically, and I think it's paid because if you don’t do it you get software that everyone agrees sucks, which is to say: most current software.

The market wants context and taste and nobody is being trained for those

Here's where my forecast runs into a problem.

The input the software development industry is about to need in unlimited quantities is people who can extract requirements from humans, define good, and exercise taste, and we do not make those people. Product people fall into their jobs by accident, as a byproduct of the typing job, or sometimes a marketing job, or maybe a consulting job. For developers, you hired a junior to write code, a senior reviewed it, and over a decade the junior picked up judgment by osmosis. That's how every senior engineer I know got their taste, and it's the loop I said in July is now broken, and it's broken because the first rung on the ladder was "type code somebody else reviews" and the agents are going to do both of those things.

Formalized training of product people barely exists. Google's APM program, which Marissa Mayer started in 2002 and which is the template everyone copies, takes about fifty people a year out of something like twelve thousand applicants. Meta, Uber, LinkedIn, Salesforce and a few others run equivalents of similar size. Add them all up and you get maybe a few hundred people a year trained, on purpose, to do the thing I'm claiming is about to be the whole job, against a junior developer pipeline that used to be tens of thousands and is now on fire. Universities teach data structures. Bootcamps teach React. Nobody teaches "go sit with a baker for a week and come back with a spec," and the pipeline for turning junior devs into that role by accident has been closed, also by accident.

The market wants people with context and taste and we are simply not training those. We’re not even sure we know how. Until that changes, the scarce input stays scarce, the people who have it get more expensive, and most of the world’s software stays bad for longer than it needs to.

I do think the market will probably solve for this. The price of the scarce thing goes up until somebody finds it worthwhile to make more of it. IBM is already redesigning its entry-level role around customer contact and specification instead of typing. Companies paying $240,000 for forward deployed engineers will eventually notice it's cheaper to grow them, and universities will eventually notice that "requirements analysis" is a course people would pay for, but it will all happen too slowly, and a cohort of people will get hurt in the meantime, and I'll come back to them. But the demand is real and the demand is what fixes it – eventually.

The craft as paid work is mostly dead, and that is a real loss

I’ve posted this sentiment before, but it’s a real tragedy that shouldn’t be glossed over. I've seen a lot of despair from career programmers over the last two years and I don't think the right response to it is a chart showing that aggregate employment is going to be fine.

A lot of people got into programming because they love the craft of it. The feeling of a clean abstraction. The satisfaction of a hard bug finally yielding. The specific pleasure of making a machine do exactly what you told it, which is a pleasure most jobs don't offer. Those people did not sign up to interview bakers. Some of them have no interest in product management and some of them are actively bad at it, in the way that some brilliant engineers are, and they're looking at the forecast I've just written and seeing their job turn into a job they'd never have chosen.

I think they're right, and I don't have a consolation prize. The craft of writing code as a thing somebody pays you to do is, I think, mostly over, outside of niches that will get narrower every year. That's a real loss and it's a loss for the profession as well as for the people, because the craft is where a lot of the taste I've been talking about actually came from, and we're about to find out what taste looks like when nobody grew up doing the thing.

Two things I'd say that aren't consolation, just observations. One is that for a fair number of the people who think they loved the typing, the part they actually loved was the moment before the typing, when a vague mess of a problem resolved into a precise shape in their head. That moment is the job now. If that's what you loved, you're going to be fine and possibly better than fine, because the industry is about to be desperate for you. The other is that the craft survives, the way woodworking survived the furniture factory, as a thing people do because they love it and occasionally get paid a premium for. Developers write software the way singers sing. That was true when it was free and it'll be true when it's automated, and the people who love it will keep doing it, and some of the best software will keep coming from them. It just won't be the job.

Ten years of turmoil lie ahead

It’s been a long 4000 words, so let’s review.

The cost of writing code collapsed, and the cost of reviewing, fixing and operating it is following, and I'm assuming it gets there. What's left of making software is finding out what people actually want, defining it precisely, and making it pleasant to use. That cost is per piece of software and doesn't transfer, so as the amount of software goes to infinity, which it will because there's no ceiling on demand, that cost becomes the whole job.

That job is called a product engineer. It's being hired for right now under a dozen new names at senior engineer pay. And the training pipeline for it is roughly fifty people a year at Google, because the way we used to produce it was as a side effect of a typing job that no longer exists.

I think the next ten years are going to be ugly, because the load is arriving before the tools do, the junior ladder is gone before the replacement exists, and a lot of people who loved the craft are going to have to decide whether they love the job that's replacing it. I think by ten years it shakes out, the way it did when compilers and then frameworks and then open source each made a generation’s worth of typing unnecessary, into a profession that is larger than today's, pays about as well, and is mostly shaped like product engineering. At twenty years I have no idea; if we hit anything resembling general intelligence in that window then this post and every other post about jobs is moot. But for the horizon I can see, the forecast is: more software, more people making it, and almost none of them typing. We are all product engineers now, whether we like it or not, and a lot of us won't.

Read the whole story
emrox
2 days ago
reply
Hamburg, Germany
Share this story
Delete
Next Page of Stories