Log in


nature


This is a weird moment. I have a hunch that we’ll look back later and tell ourselves stories in which it seemed obvious where things were going. So I wanted to lay down a little time capsule and register just how confusing everything felt at the time. This is a personal view from the trenches.
If you’re a normal person, you may feel that AI has been good at math for a long time.1 But for “real” math, this is roughly what it felt like:
| When | Feeling |
|---|---|
| 2024 | LLMs are toys |
| Summer 2025 | LLMs are interesting toys |
| Early Autumn 2025 | LLMs can do useful stuff sometimes |
| Mid Autumn 2025 | …a lot of stuff |
| Late Autumn 2025 | …a lot |
| Early 2026 | holy god |
Even having been astonished by AI progress in the past, it was still astonishing to see AI move in a matter of months from a mildly-useful toy to something that many people now consider almost impossible to do without.
Personally, I’d say that current AI makes me around 50% more productive at “doing math”. That’s despite the fact that AI can now often do in a few minutes things that would have taken me hours to do myself.
The main reason is that my concept of “doing math” involves various steps, like coming up with ideas for theorems, trying to prove them, writing things down, reorganizing everything to make it more clear, and so on. AI is good at some parts of this, but still pretty bad at others, so the overall speedup isn’t as high as you might expect.
(Even if planes could go 10× faster, your door-to-door travel time from your apartment in London to your friend’s place in Rome wouldn’t decrease that much, because you still have to get to the airport and wait to board.)
But then, I’m still (sort of; more on this later) trying to follow my old “doing math” workflow, just automating certain parts of it. That can’t be right, can it?
If we found a way to make batteries at 1% of the current cost, we wouldn’t just say, “cool, batteries are cheap now”. We’d find all sorts of new ways to use batteries that didn’t make sense before, and change the ways we generate power to account for all these new batteries. Probably our whole energy system would end up transformed. Analogously, AI being good at proofs should lead to a very different equilibrium. But what is that?2
It seems healthy, at the moment, to maintain a fluid view of what “doing math” means. But at bare minimum it surely involves understanding the math that “I” am “doing”. So long as that’s part of the workflow, it would seem to impose a limit on how quickly “I” could “do” math, no matter how good AI is.
One obvious conclusion would be that my tiny organic brain should be removed from the workflow entirely. Maybe! But it’s interesting to speculate about how much faster things could go while still keeping a human brain in the loop. I think the answer is: A lot.
Contrary to what you may have heard, humans are not obsolete for math. Not yet. The most obvious reason is that AI is still bad at writing.
People often complain that AI writing overuses various patterns or lacks a unique voice or whatever. I don’t disagree, but I always felt like there was a deeper issue that I couldn’t quite put my finger on. With math, this becomes very clear: The problem is it doesn’t make any goddamned sense.
Really, I think it’s deeper than being bad “at writing”. It seems like AI is bad at thinking in certain ways that manifest as bad writing.
When novices do math, they often create “spaghetti-code math”: Imagine a long document with lots of equations, but if you point at any one equation, it’s hard to say what assumptions underpin it, or how it fits into the bigger picture. Any random idea that was mentioned 17 pages ago might be used again at any time with no warning. With experience, people learn to break complex arguments down into modular pieces with a good “API”, in the sense that the assumptions and conclusions for each part are relatively simple.
Somehow, AI has developed these amazing technical skills, while still being bad at creating abstractions So the arguments it gives are long and tangled and bewildering. This is what makes AI math seem so alien.
Now I know what you’re thinking. Maybe AI isn’t bad at creating abstractions. It’s just bad at creating abstractions that work for you, human with tiny organic brain.
From a distance, that seems plausible. And it might be true to some degree. I have high-bandwidth access to a human brain. It’s not crazy to imagine that this gives me an advantage in predicting how a human brain would react to a given presentation of ideas. But still, I claim that current AI is objectively bad at creating abstractions, regardless of if the consumer of those abstractions is human or artificial.
Here’s why: If I ask AI to prove something hard, it will produce a proof that starts simple and gradually descends into a rampage of complexity. If I tell it to break that proof down into self-contained pieces, it will produce lemmas that each take a full page just to state. If I ask, “Why? Why have you done this to me?”, the AI will say, “This is as simple as it gets. It’s not that bad. What’s your problem?”
But if I argue with the AI for a while, I can start to understand the basic contours of the argument. And I’ll ask, “Why don’t you first just try to prove blah using only assumptions blahblah, without worrying about blahblahblah? Wouldn’t that be easier?” Often, this doesn’t work, either because my idea was bad, or because the AI isn’t smart enough to do it. (Which one? Who knows!) But after a few attempts, I can usually find something that works, and the AI can use it to re-write the proof in a somewhat simpler way. If I repeat this many times, I can gradually chip away at the complexity.
But maybe that’s still just making the proof easier for humans to understand? No! For one, this usually makes the proof shorter, and sometimes dramatically shorter. More importantly, during this process, someone (maybe me, maybe the AI) will often realize that there’s a different proof strategy that gives a stronger result. Instead of proving x < 9.7, now we can prove x < 7.1. Thus, artisanal human abstractions are “objectively” useful.
Some people might claim that it’s already possible to automate some of what I’m doing with some multi-agent Rube Goldberg thing. I’m not sure, because my experience has been that investing lots of time into clever AGENTS.MD or custom skills or harnesses isn’t a great use of time. That stuff is somewhat helpful, but things are changing so fast that the knowledge has a short half-life. Also, the majority of information about these tricks seems to come from people who are excited about the technology itself.
On the other hand, the automator told me to try typing, “ask independent agents for an adversarial review”, and I’ve found those seven words to be quite helpful. I wish I could find a source with boring best practices for people who are happy to stay away from the bleeding edge.
Another reason AI doesn’t improve my productivity more is that it is often the green light, the orgastic future that recedes before me. I’ll ask AI to do something, and it will almost seem to do it. So I’ll ask for changes, and it seems to help, but it’s still not quite right. Hours later, I’ve accomplished nothing and learned nothing. Eventually, I start over, either doing it myself or with AI on a very tight leash, and I’m done in 30 minutes. Each time this happens I feel foolish and tell myself not to do it again. But it’s very hard to judge in real-time.
Of course, I’m not claiming that AI is intrinsically bad at writing or thinking or abstraction-making. It’s gotten better at all of these and I expect it will continue to do so. All I’m saying is that as of Autumn 2026, humans still have a lot to contribute, and it’s not just better exposition.
Did AI actually get much better at math in Autumn 2025? Or perhaps, in the grand scheme of things, human math ability falls into a narrow range?
Some people are responding to the new reality by gleefully using AI to generate lots of semi-OK-ish papers and puking them up on arXiv. I understand the incentives that drive this. In some sense, it seems like the logical response to the new reality. (After inventing cars, we started taking a lot more low-value trips.) But I don’t think this is socially useful, and I tend to think everyone will soon agree that this is embarrassing. But… I’m not sure. Maybe it is socially useful? And I find myself feeling vaguely jealous of the people who are wired this way, who instead of feeling blinkered, see opportunity and plunder.
Want an optimistic pro-AI, pro-progress take? OK. If I take my old “doing math” workflow, AI makes it strictly better. A lot better. It’s like having a hyper-conscientious intern that is smarter than me in many ways, works at incredible speed, and knows approximately everything.
Yes, AI sucks at writing and making abstractions. But if I’m disciplined and try to mostly do the math “myself” while asking the AI for help, I can explore ideas much faster than before, make far fewer mistakes, and produce something just as clear as before, while developing just as much understanding. I can ask, “What happens if you do a Kofuni expansion?”, and get an answer instantly. I can ask for illustrations or interactive visualizations and see them instantly. Arguably, we’re incredibly lucky to be alive at this moment, when these new tools have opened up this new territory to explore.
And isn’t that what I wanted? Back in 2024, I bemoaned that what AI most seemed to struggle with was getting the facts straight:
Perhaps the old science fiction robots were a projection of our fantasies. I want my style and voice to be precious and uncopyable. I want an AI assistant that will tirelessly hunt down facts while I provide creativity and panache and magic. But that’s not how it is. So we should remember: In a scenario where AI is useful but humans retain some comparative advantage, we might not like where that comparative advantage lies.
At least with math, and at least for the moment, I get to be Kirk, while the AI is Spock. (Even with other types of writing, my impression is that since 2024, AI has improved more along Spock dimensions than along Kirk dimensions.) So that’s nice.
In the last few months, it frequently happens that a collaborator will use AI to generate something, and then send it to me and ask me to check if it’s useful. I can see why this seems reasonable. (Really, I do.) But when it happens a lot, one can’t help but wonder what the point of the human collaborator is.
On the other hand—with creative writing, my advice is not to use AI to write, at all. Ask questions if you want, but write every damned word yourself.3 With math, I don’t feel like such a hard line makes sense. It seems that creating something good still requires a lot of human involvement, to the point of agonizing over notation, repeatedly re-organizing things, and heavily editing individual sentences. Still, I find that if people make that effort, they can create something just as good as they could by hand, while still being perhaps 50% AI written.4
So I don’t mind if people send me “centaur math”, provided they take responsibility for the contents. The problem is that when working with AI, it takes constant paranoid vigilance to avoid letting things slip beyond your understanding. I often find myself wanting to awkwardly ask people, “OK, you obviously used AI to make this… which is OK… but how much of this do you vouch for? If we have a meeting to discuss it, will you crumble the moment I start asking questions?”
When I’m in abstraction-creation mode, I feel like I’m doing something intelligent. When I yell at AI about bad notation and writing, I feel like I’m providing taste. But I often find myself giving feedback that seems incredibly basic. Things like: This is a mess, clean it up. Or: Do you need that assumption? Or: If you can’t solve this problem, why don’t you create a simpler version and try to solve it first?
On the one hand, I guess a lot of what good human managers do amounts to giving very basic feedback. On the other hand, it’s hard to imagine that I have much durable advantage in doing this kind of thing. So I wonder how much durable advantage I have in abstraction-making or taste, too.
A common reaction to AI getting better at proofs is that humans need to focus more on exposition. This has an obvious Bourdieu-esque criticism: Human painters used to strongly value photo-realism, but after cameras were invented they convinced everyone that, oops, photo-realism isn’t important, what matters is expression, which coincidentally cameras can’t do. Isn’t a shift towards exposition in math just a way for humans to move the goalposts and justify their own continued relevance?
The only credible way I see to avoid that criticism seems to be to bite the bullet and say that, in fact, math should have already have focused more on exposition, even before AI. Personally, I strongly believe that this is true.
I think the biggest reason I’m not more productive is: What’s the point? In the past, if you came up with an elegant proof, you’d tell yourself, “I made a thing! Other people will read and use my thing! I am advancing human progress.” You can still tell yourself that now. But you have to wonder, will anyone actually read your proof? Or will they just ask another AI to explain it to them? Will your proof help their AI explain it better? For how long? If you just waited a year, would some other AI produce that same proof independently?
Alternatively, if you’re a normal person, you might think that LLMs still struggle with basic arithmetic? ↩
AI progress is so fast, compared to society’s ability to adjust, that we may never actually see what “the current equilibrium” looks like. ↩
This essay, if you’re wondering, was created by writing every damned word myself and not asking AI anything. ↩
You could have a whole debate about what that percentage means. It’s not the number of words written by AI that really matters, in my opinion, so much as who is responsible for the overall structure of the ideas. ↩

by Ploum on 2026-11-12
I like Gemini. Not the Google Chatbot but the network that existed before Google named its product. If you are enough of a geek, you may want to give it a try.
Eoin is counting the number of "capsules" on the Gemini network. A capsule is the equivalent of a "website" on the Web or a "hole" on Gopher. It’s a personal space, a bunch of pages. Blogs become "gemlogs".
Eoin’s first observation is that the number of active capsules is slowly growing. The network is healthy.
But his second observation is really interesting: there’s absolutely no correlation between the number of new capsules in a given month and articles about the Gemini protocol being promoted on the first page of Hacker News.
This is a confirmation of what I’ve been trying to explain for years: your metrics and web statistics are completely useless. The number of visitors, the number of clicks are worthless if you are not a marketer trying to extract money from a big brand. They don’t mean anything.
By the way: you should really avoid Hacker News these days. The front page is heavily manipulated to promote pro-AI stuff and bury everything that might question wether fascism-capitalism is good.
A Mozilla employee is leaving after 15 years and comes to a similar conclusion. Mozilla is awesome because it has always been abnormal. It is mostly used by abnormal people. This means that hiring "normal managers" who try to make it "normal" and chase "normal" metrics is, of course, a recipe for failure.
I always failed to understand those marketing people who try to be "like others but a bit cheaper". While all the value is being different enough to nurture your own niche.
I completely removed statistics from my blog in 2013. At the time, I had a very strong realisation that the blog posts that mattered most, those I was proudest of, and those that prompted people to mail me even years later all had mediocre statistics.
On the contrary, most of my hit, my "buzz", were quickly forgotten. But, being addicted to statistics, I was unconsciously adapting my writing style to improve those numbers. I was scrolling through social media posts that were highly popular while trying to create some myself.
Closing my social media accounts and, instead, procrastinating on Gemini had the opposite effect: making me read other ideas without caring about reactions, about popularity. Jsreed5 made the same observation while he was trying the Nostr protocol. While Nostr’s technicalities may be interesting by themselves, the content on it is similar to the one found of mainstream social networks. And our smolnet Gemini-formatted brains cannot take it anymore!
We really need a simple Gemini hosting provider that would also provide a Web version, to welcome less technical-minded people who still may want to access a quieter, non-commercial, out-of-time virtual space.
Lot of people are trying Gemini and find that there’s no content on it, that they can’t have their news and dopamine hit on it. Well, that’s exactly the point.
The fact that only a niche minority want to use it is also part of the point. Gemini might no be for you. That’s fine. The modern Web and even the real world (where every device is actively working against me and every human interaction seems to be about AI) is increasingly not for me. So let me have my strange niche space.
UPDATE: Those Gemini hosting providers exist:
I’m Ploum, a writer and an engineer. I like to explore how technology impacts society. You can subscribe by email or by rss. I value privacy and never share your adress.
I write science-fiction novels in French. For Bikepunk, my new post-apocalyptic-cyclist book, my publisher is looking for contacts in other countries to distribute it in languages other than French. If you can help, contact me!
Since the initial release of GraphQL in 2015, the GraphQL specification has always been transport agnostic.
Most of the GraphQL specification is about “services”, taking “requests” in, executing them, and producing “responses”. How those requests and responses are sent and received is up to the implementer.
This is generally useful. You can use GraphQL on your local machine, over raw TCP, avian carriers, or anywhere else. For the large crowd using GraphQL over HTTP, though, the lack of a specification made interoperability with other HTTP tools and observability more difficult than it should have been.
This is changing today with the first release of the GraphQL over HTTP specification!
The GraphQL specification stays transport agnostic; the GraphQL over HTTP specification is a new document, supplementary to the main GraphQL specification.
If you’re using GraphQL over HTTP, follow the guidance from the specification and ensure your servers, clients, proxies, and other services play well together.
The GraphQL over HTTP specification includes a new media type.
Previously, a lot of GraphQL servers were using for their responses. This made it hard for clients to differentiate between a well-formed GraphQL response from the origin server and an error response from a proxy, cache, or other network intermediary.
As a workaround, most implementations set the status code to : if a client received a status code, it knew the response wasn’t tampered with and was safe to parse as a GraphQL response.
This is not ideal from an observability point of view and led to some jokes about . It’s hard to get the status of your service if everything is a 200…
This is now fixed!
When a client receives an body, it knows it can parse it as a well-formed GraphQL over HTTP response, regardless of the status code.
The general rule is:
The specification includes detailed guidance on which status codes should be used, but implementers may choose to use an alternative status code if it better fits the situation, so long as it is consistent with the general rule. Common status codes include:
A successful response would look like this:
A request error would look like this:
The specification also introduces a new status code for use when both and are present; you can read more about 294 Partial Success in the non-normative notes.
“200 Not OK” issues aside, a lot of things have been working really well for GraphQL over HTTP over the past decade.
This specification documents all those things::
It also includes non-normative notes about security, partial success, and future compatibility
This is just the beginning!
The IETF just moved the QUERY HTTP verb to a proposed standard.
is the perfect fit for GraphQL, and we already have plans to support it. We didn’t want to postpone this initial release or rush the implementation, but we hope to include it in the next revision of the GraphQL over HTTP specification.
Another thing that will benefit from standardization is Persisted documents. The technique of persisting GraphQL documents (“persisted queries”) has been in use since before GraphQL was open sourced in 2015, with different implementations solving different problems: performance, security, observability. We are eager to work with the community to build a standard approach that can solve all these issues whilst retaining future extensibility.
Finally, request batching will be a big win, particularly in the context of composite schemas (Federation) or when making requests to schemas you do not control.
If you are a GraphQL user, chances are you are already using the new specification without being aware of it! Most GraphQL frameworks and libraries out there already support the new specification.
If you are a library author, give the new specification a try!
In all cases, let us know what you think!
Last updated on
Copyright © 2026 The GraphQL Foundation. All rights reserved.
By Yagiz Nizipli, Principal Engineer
Open a profile on <a href="http://X.com" rel="nofollow">X.com</a> over a slow connection. On the old web app, you'd stare at the X logo for more than 22 seconds before the first post appeared. On the new one, it shows up in 2.7.
That new web app replaces the three servers we used to run for people, search crawlers, and link previews with one. It already serves logged-out <a href="http://X.com" rel="nofollow">X.com</a> and the pages search engines crawl. Signed-in <a href="http://X.com" rel="nofollow">X.com</a> is next. We tested it with employees and testers on <a href="http://lite.x.com" rel="nofollow">lite.x.com</a>, and now we're moving signed-in people over slowly, one country at a time.
<a href="http://X.com" rel="nofollow">X.com</a> is the sixth most visited website in the world, according to Similarweb. Five engineers, working with AI coding agents, built the first version of its new web app in under six months. The team has grown as signed-in pages move over, and more than 20 people have committed to the app since the end of September.
This post covers why we rebuilt <a href="http://X.com" rel="nofollow">X.com</a>, how we're rolling it out country by country, and how the old and new apps compare today. It also covers the performance work we've done since logged-out traffic moved over.
<a href="http://x.com" rel="nofollow">x.com</a> has been rebuilt before. In 2017 we launched Twitter Lite (capitalized terms used in this section defined therein), a Progressive Web App at <a href="http://mobile.twitter.com" rel="nofollow">mobile.twitter.com</a> built for people on slow connections. It was a client-side React application with a small Node.js server that rendered an HTML application shell. Once the shell loaded, the browser fetched data directly from our APIs. Keep that detail in mind, because it's at the root of the slow-connection problem we'll get to later. In 2019, the same codebase became the new Twitter.com on desktop, built around "one codebase - one website" for every device.
That app, which we call rweb (short for responsive web), has served <a href="http://x.com" rel="nofollow">x.com</a> for most of the last decade. Over the years, we added more servers alongside it, each with its own purpose:
Each server did its job well. The trouble was that there were three of them: a single page on <a href="http://x.com" rel="nofollow">x.com</a> could be built in three different ways.
Which server answers each kind of visitor, before the rewrite and today.
One URL on <a href="http://x.com" rel="nofollow">x.com</a> has three very different audiences. Take x.com/elonmusk.
A person on a phone or a laptop wants to see the profile and the latest posts as quickly as possible, then scroll and maybe sign up.
A search crawler such as Googlebot or Bingbot wants complete HTML: the posts, structured data that describes them, links to every language version of the page, and the right status code when an account doesn't exist.
A link-preview bot, like the ones behind iMessage, Slack, or Discord, wants the page's title, description, and image. Everything else on the page is wasted work for it.
Serving all three is hard because of how x.com's data is shaped: it's a graph. A post has an author, the author has a profile, and the post may quote another post with its own author and media. The browser discovers most of that graph only after it has downloaded and ran the code that asks for it. Remember the application shell from Twitter Lite? This is where it hurts. On rweb, a logged-out visitor's browser downloaded the shell, then the JavaScript, then ran it, then requested data from our GraphQL API, and only then rendered the profile. On a fast connection, you barely notice that chain. On a slow one, every step is another round trip, and the visitor spends all of that time staring at a splash screen.
Steps in order, not to scale.
rweb SSR and Jetfuel SSR solved the crawler half of this problem by rendering HTML on the server. The catch was that they solved it separately, from each other and from the app people used. A fix to a page's meta description, structured data, or 404 behavior could need to land in three codebases.
Some problems don't show up in a design doc. You only find them after years of running the system.
Three servers drift. Every SEO fix could land in one server and miss the others. Keeping them aligned was a constant, mostly invisible tax.
Logged-out visitors got the slowest path. Crawlers got finished HTML from rweb SSR or Jetfuel SSR. People who weren't logged in got rweb's application shell and had to wait for JavaScript to render the page. The bots got the better deal.
The stack aged unevenly. rweb combined a normalized Redux store with Relay, styled components through React Native for Web, type-checked with Flow, and shipped separate modern and legacy bundles. Each choice made sense when it was made. Together they made everyday changes slower than they needed to be. We call the result death by a thousand cuts: each problem was small on its own, and together they made the app hard to maintain and hard to keep fast.
At this point, we had three options.
The first was to keep improving rweb in place. We'd done a lot of that over the years, and it kept the site healthy. But it also kept all three servers, and giving logged-out visitors server-rendered HTML would have meant building a fourth rendering path. A fourth.
The second was to go a step further and replace rweb's toolchain while keeping its architecture: Webpack and Babel with Vite, Flow with TypeScript, and our Express server with Fastify. Each of those changes touches nearly every file in the codebase, and at the end of it, the architecture that caused the problems would still be there.
The third was to build a new application that serves every audience from one server, move traffic to it gradually while rweb keeps serving everyone else, and fold both SSR servers into it along the way. That's the one we chose.
In 2019 we wrote that "big migrations like this are risky and difficult to pitch." That's still true. What made this one possible is that it happens gradually: logged-out visitors first, then signed-in people one country at a time, and the old servers keep running until everyone has moved.
There are two fair objections to a rewrite like this.
"Never rewrite from scratch." Joel Spolsky's advice is well earned: big rewrites tend to stall while the old product keeps moving. We kept rweb shipping the whole time, moved traffic over gradually, and tested the new app against the old servers as specifications. With agents doing much of the implementation, the rewrite took months, which left the old product little time to pull ahead.
"Why not just upgrade Webpack?" Faster builds would help the people building <a href="http://x.com" rel="nofollow">x.com</a>. They wouldn't give the visitor on a slow connection server-rendered HTML, and they wouldn't turn three servers into one. Those were the problems worth a new app.
Rewrites have a way of making the old code sound worse than it was. A lot of what worked in the old stack made it into the new app.
rweb got the product model right. One responsive codebase that adapts to screen size, input method, and network conditions is still how we build for the web. rweb also moved <a href="http://x.com" rel="nofollow">x.com</a> to GraphQL and Relay, which the new app builds on directly.
rweb SSR knew how <a href="http://x.com" rel="nofollow">x.com</a> URLs break in the wild. Over the years, rweb SSR collected rules for URLs that arrive mangled: search queries with trailing punctuation, language parameters glued onto queries, and intent links that chat apps wrap in extra characters.
Jetfuel SSR took search seriously. Jetful SSR pages carried detailed structured data, linked every language version of each page, and returned real 404s for content that doesn't exist.
A rewrite is a chance to throw things away, and it's tempting to throw away too much. We kept:
The new app is built on Vite, React, Fastify, Platformatic Watt, Relay with GraphQL, and XDS, our new component library. A server package of our own ties them together.
@x-clients/server package assembles it from configuration: security headers, cookies, metrics, streaming rendering, and graceful shutdown.The new server decides how to render each request based on who's asking.
People get streaming HTML. The server sends the page shell as soon as it's ready and streams in each part of the page as its data arrives. Each GraphQL response the server received travels in the page once, so the browser can reuse it without asking the API again.
Verified search crawlers get complete documents. For search engines, the server waits until every part of the page has been rendered and sends the whole document at once, with structured data and every Suspense boundary resolved in place. We make that call based on our edge's verification of the crawler's IP address. Why not check the User-Agent header, which is the common approach? Two reasons. First, it would buffer performance tools like Lighthouse along with real crawlers. Second, it would let anyone request the more expensive path by changing a header. With verified IP addresses, our Lighthouse runs measure the same streamed page people get.
Crawler documents never hydrate, so they carry no client bundle, no router state, and no placeholders that only our JavaScript would replace. Size matters here more than you'd think. Googlebot reads only the first 2 MB of a response, and the HTML of a long thread can run past that. We'll get to how we brought those documents back under the limit in the performance section.
Link-preview bots get only what they read. These are the bots that unfurl links, such as Slack, iMessage, Discord, WhatsApp, Signal, Facebook, LinkedIn, Telegram, and Snapchat, to name several. For them, the server runs the route's data loading and head tags and skips rendering the page body, and the loaders skip the timeline and conversation requests that only the body needs. The response carries the title, description, and card image that the bot reads. Any other crawler that our edge hasn't verified gets exactly what a logged-out visitor gets. That includes a request that claims to be a search engine but comes from an unverified IP address.
Card images come from a Rust service. The image in a post's link preview is a PNG drawn on demand. Jetfuel used to draw those cards with a JavaScript service. It could only use more cores by running more instances, which share no memory, and during incidents it had taken about two minutes to respond. So we rewrote it in Rust. The new service lives in the same monorepo as the new app and answers the same routes: posts, media previews, subscriptions, cashtag charts and Money. A record-and-replay test harness checks every card against committed baselines, and a second harness compares the new cards with the old service's, pixel for pixel.
Every route declares its data up front. When a request comes in, route loaders start the GraphQL requests the page needs while the server is still rendering. The page carries each GraphQL response the server received, once, as JSON text. The browser starts with an empty Relay store and replays those responses into it, so a component that asks for data the server already fetched gets the server's response without a network request. The browser holds responses that nothing has read yet for 30 seconds after the stream ends, so a tab or dialog opened soon after still finds them.
Client-side navigation works the same way. Links preload a route's code and data when someone shows intent to visit it, by hovering over or focusing the link. Posts in a timeline aren't plain links, so a post preloads when the mouse moves onto it and rests there for 100 milliseconds, or presses it. A post that scrolls under a still pointer doesn't preload. Since September, 21 more routes start their main query from the route loader, so a hover preload fetches their data along with their code.
rweb still has one advantage we're catching up on. It kept so much data in a client-side cache that moving between screens often felt instant. Intent-based preloading is how we're closing that gap.
So how did fewer than five engineers build the first version in under six months? The short answer is AI coding agents.
The engineers set the architecture, decided what to build, and reviewed every change. Agents did much of the implementation: porting behavior from the old servers, converting pages, writing tests, and fixing what CI and reviewers flagged. That only works if you can trust what the agents produce. Three things got us there.
Shared instructions. One file at the root of the repository, AGENTS.md, tells every agent how we write code: named exports, no barrel files, validation of external data at trust boundaries, which tests are worth writing, and that nothing gets committed until lint, typecheck, and the relevant tests pass. Every agent, and every new engineer, starts from the same rules.
Skills in the repository. Recurring workflows live next to the code as skills that agents follow step by step, more than 25 of them: writing commits, opening and stacking pull requests, reviewing code, shepherding a pull request through CI, changing dependencies, adding translations, and working with Relay and our router. When a workflow changes, we update its skill once, and every agent picks it up.
Guardrails on every commit. We turned our conventions into lint rules. Custom oxlint plugins check Relay usage, Tailwind classes, tests, and translations. And yes, we have an "anti-slop" plugin. It rejects patterns agents tend to produce, such as chained type assertions, parameters typed as unknown, and conditional spreads of empty objects. A pre-commit hook formats, lints, and type-checks every change before it lands, and a pre-push hook lints the packages that import it.
The migration itself suited agents well, because rweb SSR and Jetfuel SSR were working specifications. An agent could read how an old server handled a URL or a page type, port the behavior, and write a test that pins it down, and a reviewer could check the result against the original.
For the engineers, the job shifted. We spent less time writing code and more time deciding what the system should do, then checking in a real browser that it actually does.
Moving crawler traffic is the riskiest part of any web migration, because search engines notice everything: a missing structured-data field, a changed canonical URL, a 404 that used to be a redirect.
We treated both SSR servers as specifications. For each page type, we compared what Jetfuel SSR or rweb SSR returned with what the new app returned, and closed the gaps one by one: structured-data annotations, meta descriptions, language alternates, 404 pages, redirects, and URL cleanup. Many of those behaviors now live in shared components, next to tests that name the server they came from.
A small parity script made that comparison repeatable. It requests the same path from two servers as a verified Googlebot and compares what search engines read: the status code and redirect, title, description, canonical URL, robots tags, Open Graph and X card tags, the number of language alternates, and the types of structured data.
Crawler traffic moved to the new app gradually:
We're moving signed-in <a href="http://x.com" rel="nofollow">x.com</a> one country at a time. For every request, our edge decides which server answers, based on the path and on who's asking, so we can move a group of people to the new app and move them back if something goes wrong.
The paths come from the app itself. A configuration file next to the app (ngroutes) discovers the routes in the app's file-based route tree and publishes them to the edge on every deploy. A path the new app doesn't have goes to rweb.
A feature switch decides who gets the new app, so we can change who's in without deploying the app, and anyone we take out goes straight back to rweb.
Logged-out pages went first. While they were in progress, the new app was also available at <a href="http://lite.x.com" rel="nofollow">lite.x.com</a>, which let us compare it with <a href="http://x.com" rel="nofollow">x.com</a> side by side. Today, the new app serves logged-out <a href="http://x.com" rel="nofollow">x.com</a>, and signed-in <a href="http://x.com" rel="nofollow">x.com</a> is rolling out. Signed-in pages are rebuilt and tested on <a href="http://lite.x.com" rel="nofollow">lite.x.com</a> first, where employees and testers use the signed-in app. Recent examples are the NFL, MLB, and college football hubs. In the first country, signed-in people are split into an experiment: some get the new app, and the rest stay on rweb, so we can compare the two apps on real traffic.
Some features are built once and shared across the migration. X Chat is the clearest example: both rweb and the new app load X Chat at runtime from <a href="http://chat.x.com" rel="nofollow">chat.x.com</a> through Module Federation, so both sides run the chat that <a href="http://chat.x.com" rel="nofollow">chat.x.com</a> ships. The new app loads X Calls and Money the same way. It also lends Money the page's own copy of React and other shared libraries, which cut the code downloaded for the first Money page from 590 KB to 509 KB gzipped. A shared features package still carries code that both apps import, such as analytics and Grok Imagine.
The easiest way to see the difference is to watch both apps load side by side.
We recorded this on November 3, 2026, signed in to the same account on both sides: rweb on <a href="http://x.com" rel="nofollow">x.com</a> and the new app on <a href="http://lite.x.com" rel="nofollow">lite.x.com</a>. The network was throttled to Lighthouse's default Slow 4G profile, a 150 ms round trip, 1.6 Mbps down, and 750 Kbps up, with no CPU slowdown, an empty cache, and service workers turned off. We recorded each app three times on its own and used each app's median run. The timers under each side come from the browser's own timing APIs.
That's more than 22 seconds of splash screen. This is a lab recording, so treat it as an illustration of the gap; real devices and networks will vary. But the shape of the difference comes straight from the architecture: the new app sends content in the first response, and rweb has to download and run its JavaScript before it can even ask for any.
The other results are structural. x.com's logged-out web runs on one server where there used to be three. The crawler traffic that rweb SSR and Jetfuel SSR used to handle is served by the new app. An SEO fix now lands once. As traffic moved, we halved rweb's logged-out fleet from 1,400 to 700 instances per data center, and halved rweb SSR's fleet from 2,400 to 1,200 before shutting it down.
That 2.7 seconds didn't come for free. The June recording in Figure 2 shows where the new app started: already about six times faster than rweb on a slow connection, with plenty left to fix. Since then, performance has been a big part of the work: more than 80 commits labeled perf have touched the app since September 1. Here are the changes that mattered most, on the server and in the browser. Every number below comes from the pull request that made the change, except the stylesheet change, which we measured again for this post. Each one says where it was measured: on production builds in a lab, on a development server, or on the production fleet before the change.
More rendering workers. Logged-out rendering was limited by the workers' event loops. In October, measured on the production fleet, each worker's event loop was busy about 67% of the time at the median and 84% at p95. At peak, its longest stall was about 1.9 seconds at the median and 3.7 seconds at p95. Here's the sneaky part: a stalled event loop can fire a timer before it handles a response that has already arrived. So a 1-second timeout on one upstream request fired on 1–9% of logged-out renders, even though the service behind it answered in about 25 ms. Each worker renders on one thread, so we spread the same traffic across more workers, which cuts each event loop's share of it.
No waiting on a guest token. A logged-out render needs a guest token and the visitor's feature flags. The server used to request the feature flags only after the guest-token request returned, even though the feature-switch request doesn't use the token. Now both requests start together. That removes a serial round trip from logged-out renders, and a slow or rate-limited guest-token request no longer delays the feature flags.
GraphQL responses in the page, instead of store records. The server used to serialize its Relay store into the page, then stream every update to it. Those normalized records were four to five times the size of the GraphQL responses they came from. Now the page carries each response once, as JSON text, and the browser parses it with JSON.parse when it replays the response into its own store.
Crawler documents under Google's 2 MB limit. Remember Googlebot's 2 MB limit? The HTML of a long thread ran to 2.2–3.5 MB, so Google lost the replies past the cut, and our structured data pointed at posts it never saw. Three changes brought those documents down. Each was measured on local renders, with the request marked as a verified crawler.
Hydrating the shell right away. The entry script used to be a deferred module, which the browser runs only after it has parsed the whole document. A streamed document is fully parsed only when its last Suspense boundary arrives, so hydration waited for the slowest part of the page. The entry is now an async module. It runs as soon as it loads, React hydrates the shell, and each boundary hydrates when its HTML lands. In a test with a 5-second server-side delay on the conversation query, React attached to the page at 589 ms, long before the document finished parsing at 6,017 ms.
Fewer files at startup. A page can't hydrate until every file in its entry's static import graph has arrived. With Rolldown's default chunking, that was 754 files for the signed-in entry and 582 for the logged-out one, and most signed-in startup files held a single module. Chrome runs at most about 100 requests at once on one HTTP/2 connection, and our asset CDN allows 100 concurrent streams. So those files took about eight round trips, even when the browser requested them all at once. A build plugin now packs the modules that every entry loads at startup into three chunks: dependencies, our own code, and the code that names lazily loaded chunks, whose file names change on almost every deploy. The signed-in entry went from 754 startup files to 182, and the logged-out entry from 582 to just 10. Every page still loads exactly the modules it loaded before. In a lab test that delayed every JavaScript response by 275 ms, about the p90 round trip for <a href="http://x.com" rel="nofollow">x.com</a> users, the signed-in home timeline appeared at 4.95 seconds instead of 6.63.
The stylesheet first. On a slow connection, every download in flight shares bandwidth with the render-blocking stylesheet. The page's JavaScript used to start downloading at the same time, so first paint waited for code the page didn't need yet. A small inline script now adds the entry script, and the preloads for the chunks the server rendered, once the stylesheet has loaded. In lab runs on a slow profile (4× CPU slowdown, 150 ms round trip, 1.6 Mbps), first contentful paint for a logged-out profile went from 3,064 ms to 1,984 ms. For a logged-out post it went from 7,216 ms to 1,804 ms. There's a cost: scripts start later, and on two of the five slow pages, hydration finished slightly later, by 0.3% and 0.6%.
Lab medians before and after JavaScript started waiting for the stylesheet. Lower is better.
Fewer bytes. Several changes cut what pages download:
How we measure. Lighthouse CI runs on pull requests that can affect the app, against @jack's profile and his first post, with desktop and mobile settings. The pull requests behind the changes above measured them on production builds, often behind an HTTP/2 proxy that adds latency, and reported regressions next to gains. For this post, we measured the stylesheet change again the same way: 11 interleaved pairs of runs per page, marking a change only when its 95% bootstrap interval excluded zero. In the field, the app reports Core Web Vitals (LCP, INP, and CLS), plus FCP and TTFB, to perftown, our client performance pipeline, under the same product namespace as rweb.
For this post, we also benchmarked both apps on November 3, 2026. Signed in, we could compare them directly, because rweb still serves most of signed-in <a href="http://x.com" rel="nofollow">x.com</a> and <a href="http://lite.x.com" rel="nofollow">lite.x.com</a> serves the signed-in version of the new app. Logged out, <a href="http://x.com" rel="nofollow">x.com</a> already runs the new app, so there we measured it on its own.
Every load started a fresh headless Chromium with an empty cache and service workers turned off, so neither app got help from a warm cache or a service worker. We loaded each page seven times per app and setting, alternating between the apps. There were two settings: unthrottled, and a slow profile with 150 ms of added latency, 1.6 Mbps down, 750 Kbps up, and the CPU slowed down four times. Our main metric is time to first post, the moment the first post is on screen. First contentful paint alone would flatter rweb, because its first paint is the splash screen.
Median time until the first post is on screen. Lower is better.
Signed in, profiles and posts show up 8 to 13 times sooner on a slow connection. On the slow profile, rweb showed its first post after about 22 to 25 seconds on every page we tried. The new app showed the @SpaceX post in 1.7 seconds and the @SpaceX profile in 3.0 seconds, 12.8 and 8.2 times faster. Unthrottled, the new app was 3.2 times faster on the post and 2.3 times faster on the profile.
Home gains the least. The new app renders the signed-in Home timeline only in the browser, so Home waits for JavaScript in both apps. On the slow profile the new app showed Home's first post at 14.1 seconds against rweb's 24.6, 1.7 times faster. Unthrottled it was 1.2 times faster, at 1.8 seconds against 2.2. Home is where the new app has the most left to gain.
The server does more work before it answers. Signed in, the new app's first byte arrived at a median of 430 to 560 ms on the profile and the post, against under 300 ms for rweb, because the server fetches the data and renders the page before it responds. rweb answers sooner with an empty shell and then asks for everything from the browser.
Compressed bytes of script that finished downloading before the first post appeared.
Most pages show a post before any JavaScript arrives. On the slow profile, rweb downloaded 3.0 to 3.6 MB of compressed JavaScript before its first post on every page. The new app downloaded none before showing a profile or a post, because the post is already in the HTML. On Home it downloaded 1.9 MB first. Over a whole page load, the new app downloaded 1.3 to 2.3 MB of compressed JavaScript per signed-in page, against 4.1 to 4.8 MB for rweb.
The new app on <a href="http://x.com" rel="nofollow">x.com</a>. Median time until the first post is on screen.
Logged out, <a href="http://x.com" rel="nofollow">x.com</a> shows a post in about 2 seconds on the slow profile. On the slow profile, the logged-out new app showed the first post in 1.7 seconds on an @SpaceX post and in 2.2 seconds on the @SpaceX profile. Unthrottled, it took 442 and 792 ms. With the June recording's network throttling and no CPU slowdown, the @SpaceX profile showed its first post at a median of 2.1 seconds. In the June recording (Figure 2), a logged-out profile showed its first post at about 3 seconds on the new app and about 18 on rweb. A screen recording and the browser's timing APIs don't mark exactly the same moment, so treat that comparison as rough.
These are lab numbers from one laptop, and real devices and networks will vary. Signed in, we used the same account on both apps.
Looking back, three lessons stand out.
The old servers were the best specification we had. Much of what rweb SSR and Jetfuel SSR had collected over the years became tests in the new app, and a parity script checked the result against the originals. That's also what made the work such a good fit for agents.
Moving gradually is what made a rewrite safe. Crawlers and logged-out pages went first, and signed-in people are moving one country at a time while rweb serves everyone else. Any group we move can go straight back.
Lab numbers need field numbers next to them. Most numbers in this post come from a lab. The app also reports Core Web Vitals from real visits, because real devices and networks will always vary.
Signed-in <a href="http://x.com" rel="nofollow">x.com</a> is rolling out now, one country at a time, through the same edge routes and feature switch that serve logged-out pages. When the rollout completes, rweb retires, after serving <a href="http://x.com" rel="nofollow">x.com</a> for most of the last decade. It's been a year of rebuilding at X: in July, we also rebuilt the Android app from the ground up.
Twitter Lite set out in 2017 to be the best way to use Twitter on a slow, unreliable, or expensive connection. Nine years later, that's still the goal. The new <a href="http://x.com" rel="nofollow">x.com</a> carries it to all three audiences: people, search engines, and link previews.
This wouldn't have been possible without these people: Alex Abraham, Jonas Badalic, Robert Balicki, Louis Barthonet, Vinayak Bector, Tom Blacknell, Lachlan Geoffrey Bradford, Nicolas Duc-Dodon, Benjamin Erichsen, Klara Jemelik, Ray Li, Yagiz Nizipli, Saurin Patel, Darshan Raju, Jainam Chirag Shah, Mridul Singhai, Hugo Striedinger, Benji Taylor, and Zachary Warunek. Thank you.
I recently built two full games with AI:
I did not write a line of code. I did not read one either.
My "game editor" was a chat, a link to playtest the game, and a web page with previews of 3D models. My "work" was sending text and screenshots. Nothing else.
And still, making those games has been hard and intense. Like never before. For weeks.
AI made writing a game faster and easier. It did not make it easy.
150
100
50
0
I really enjoy game development. Like, a lot. But game dev is intense, time-consuming, and often has a bad financial return. So much so that I wrote a full essay about my frustration.
But AI changed everything!
A project that used to take months is now a weekend of prompting, and I wanted to see if that holds for a complete game, not just a slop demo.
My goal was getting an answer to the question all game devs are asking themselves:
If AI implements everything, what's left for me?
I found the answer: The hard part didn't go away, it moved. Away from implementation, and into the choices only you can make: what game, what style, what is fun, what is broken.
AI frees your time, so you can think about the core of your game. And that's hard, and now it's all you have to do, all the time. No coding break.
Great. Well, what does this mean, in practice, for you?
Here are all the steps I will take for my next game, everything that I learned, and how you can steal all of it.
The first decision is yours, and it will always be so: "What game do I want to make?"
The answer you choose has the potential to make or break you and your game. Literally.
Any step in your pipeline the AI can't do becomes your full-time job.
So when you pick a genre and a style, you are also picking where your time will go. Agents go fast, so whatever still needs you becomes the bottleneck. Make sure that step is one worth your time: taste, fun, playtest.
My plan for Spirit Call was a game like Genshin Impact (原神), with a new character every few weeks.
So the question became: can the agent produce high-quality characters, without me stepping in? And, spoiler, the answer was no (after two days of attempts).
Simple stylized models worked well. Detailed anime characters failed every time.
I tried every route I could think of: reference sheets, prebuilt models, a full studio-style pipeline, even copying a character from another game. The results were bad, and worse, never repeatable. And all of this before animation.


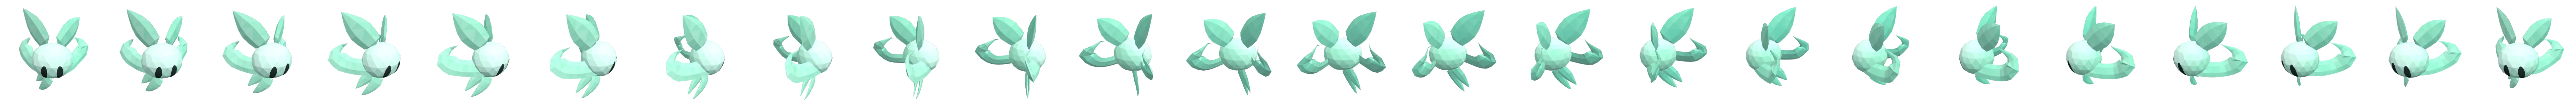
I could have done the anime characters by hand (maybe). Even with AI support, one decent character would have taken me weeks.
So I changed the style instead of the game: from full anime characters to simple stylized spirits. Not the initial vision, but one I could ship, fast, with AI in every step of the pipeline.
Even the simple spirits would have cost more by hand than the whole game took: about a month for all ten, against three weeks for all of Spirit Call. With the agent, they took about 20 minutes each:
They were also far easier to animate. Each enemy went through the same steps.
I learned my lesson with my second game, Inkline Town: an ink style, assets made by an agent, with a repeatable pipeline from day one.
Agents are not yet good at anything that requires taste: character design, detailed 3D models, animation, story. Any of it adds more work for you, personally.
| genre | characters | many models | animation | tuning | left to you |
|---|---|---|---|---|---|
| puzzle | |||||
| idle | |||||
| town builderInkline Town | |||||
| card game | |||||
| platformer | |||||
| top-down shooterSpirit Call | |||||
| fighting | |||||
| story RPG | |||||
| anime action |
If you want an agent-first fast loop, your role should only be playtesting and taste. Anything else, and the loop is broken.
You should not need to read the code. The agent can handle it all. But you need layers of verification on top to make the output reliable. It starts with structure.
I use an Entity Component System (ECS): every object in the game is an entity, a bag of data (components) like position, velocity or health. Each piece of logic (a system) declares which components it reads and writes, and runs on every entity that has them.
Systems never call each other. That's what makes the architecture composable: the agent can add or rewrite one system without touching the rest, and since every system declares what it touches, the checks have something concrete to verify.
Spawn a Projectile below: it has a position and a velocity, so the same Move system that moves the player moves it too. No new code.
ECS
Pick components
Below is the same rule on a real frame of Spirit Call. The spirit, every enemy and every bolt in flight are entities: pick components, and every entity that has all of them lights up. That is how a system finds what to run on.
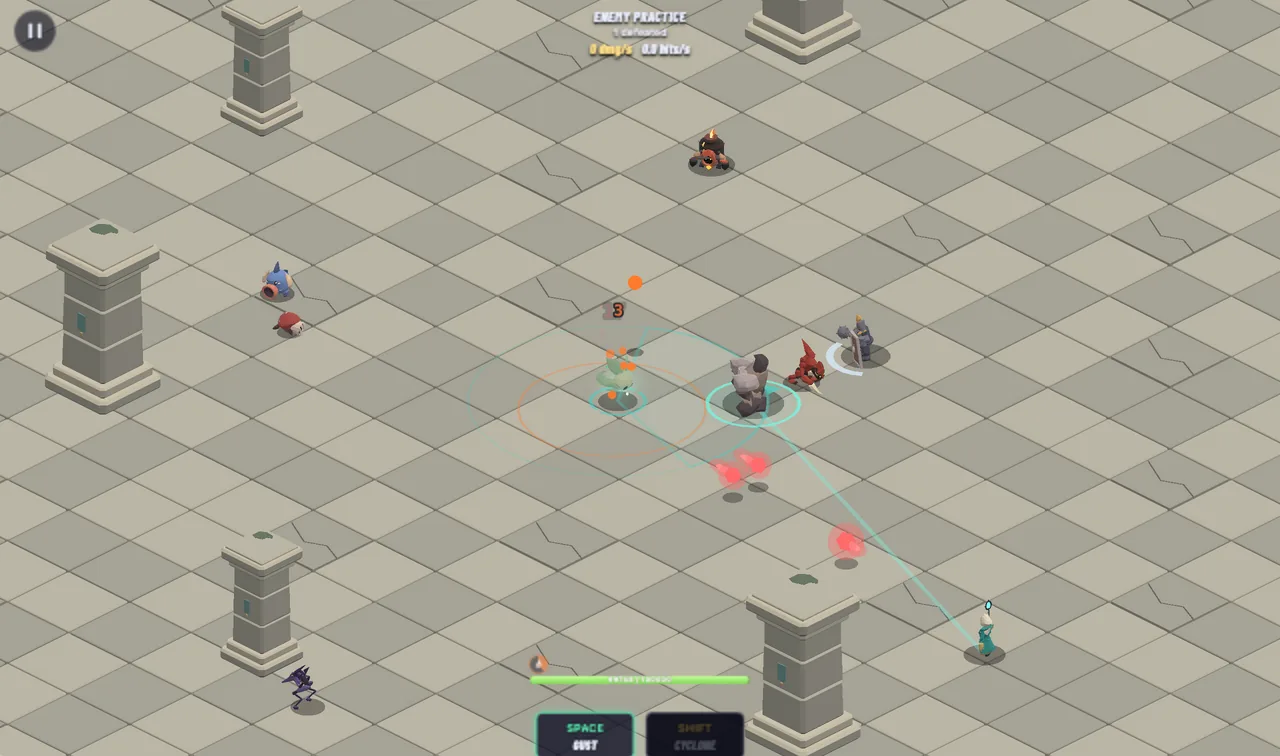
Pick components to find the entities that have all of them
On top of that structure, you layer automatic checks. Each one takes a set of bugs off your mind:
The checks run between my prompt and my next playtest: the agent sees the failures, fixes them, and I never hear about most of them.
You can get creative with checks, depending on your game. In Spirit Call, I made the agent write a balance model to mathematically prove that clearing each main quest once pays for leveling a character up to the next one, without grinding.
Drag the sliders: cut the quest rewards or make level-ups pricier, and see which quest first needs replays to afford.
None of these is mandatory. But the more of them you add (where they make sense for your game), the faster you iterate, and the more of your attention goes to taste instead of code and bugs.
You still need to know what each layer protects you from, even without knowing the implementation details. That's what lets you direct the agent when something keeps going wrong.
I created Ritmo for this exact purpose: a TypeScript ECS runtime I built in parallel with the two games, to collect all the checks in one place.
But the principles work with any engine.
Below is a real session: my prompt, the agent's thinking, and how Ritmo helped:
Upgrade the game inkline-town to Ritmo 0.9.0, adopt the new Ritmo oxlint plugin…
Typecheck passes, so now I'll run the game-specific lint to catch things like .
pnpm lint:gamewarning relation-failure-never-read Town/WalkerOf: … so
warning relation-failure-never-read Town/FieldOf: … so
before the upgrade: 0 warnings
If relate fails because the parent gets despawned in the same apply right after the child spawns,
…a Hazards system could despawn a watch tile the same frame a Rescue walker relates to it… I think that reads relation failures…
Created src/sim/orphans.ts, added DropOrphans to the schedule
pnpm lint:game0 warnings
pnpm testpass 138 · fail 0
With all of that in place, the first version of your game loop comes quickly. Days, sometimes hours. Then the real work starts.
Everything that comes later, an AI cannot do alone:
Three quarters of Inkline Town's commits came after the first two days, when the game was already playable.
The start was fast. I found a style reference on X, a short video, and asked the agent to recreate it, animations included: five minutes.
Then I asked the agent to turn it into a town simulation with a few basic buildings: working ten minutes later. The core of the game took about 20 minutes. Defining the buildings and a few mechanics came next. All of that fit in the first two days.
The screenshots from those days show it: a playable town within the first hour, and a real-looking one by the evening.
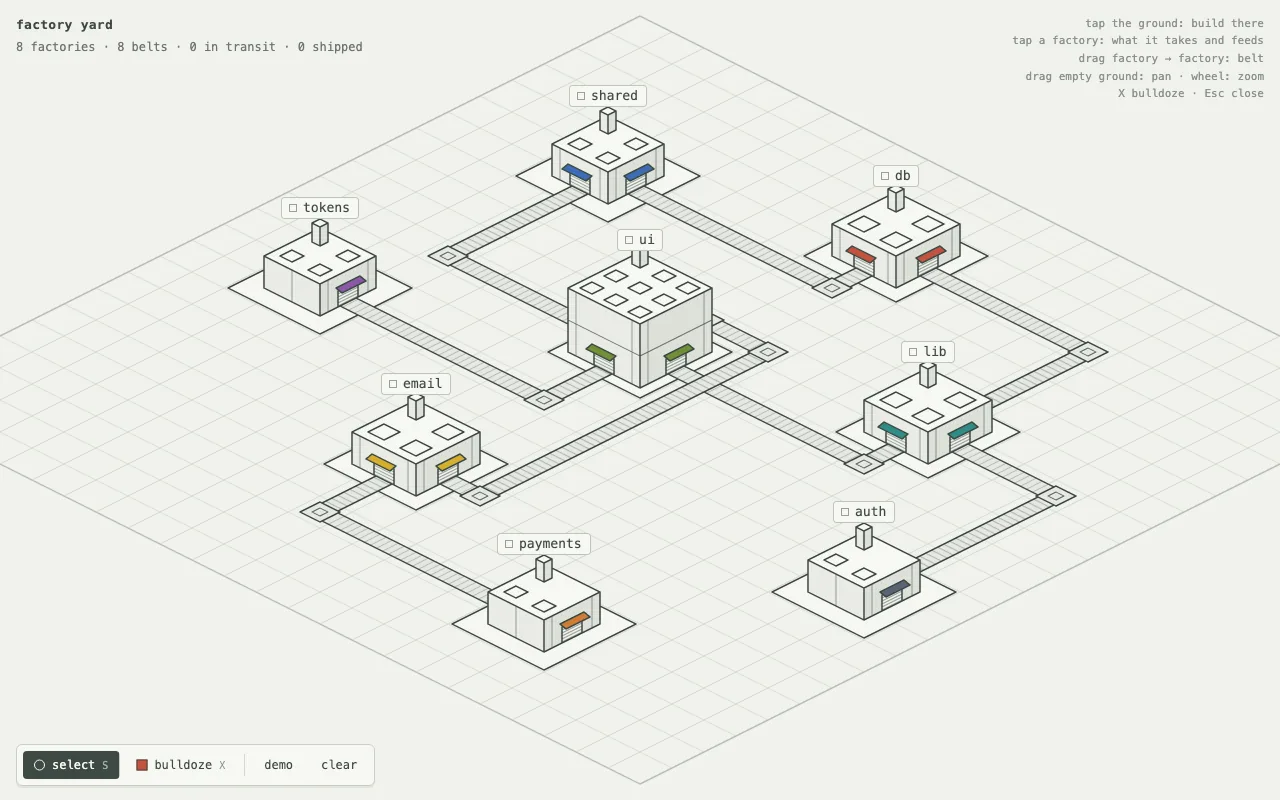 Oct 12, 12:17 · factory yard
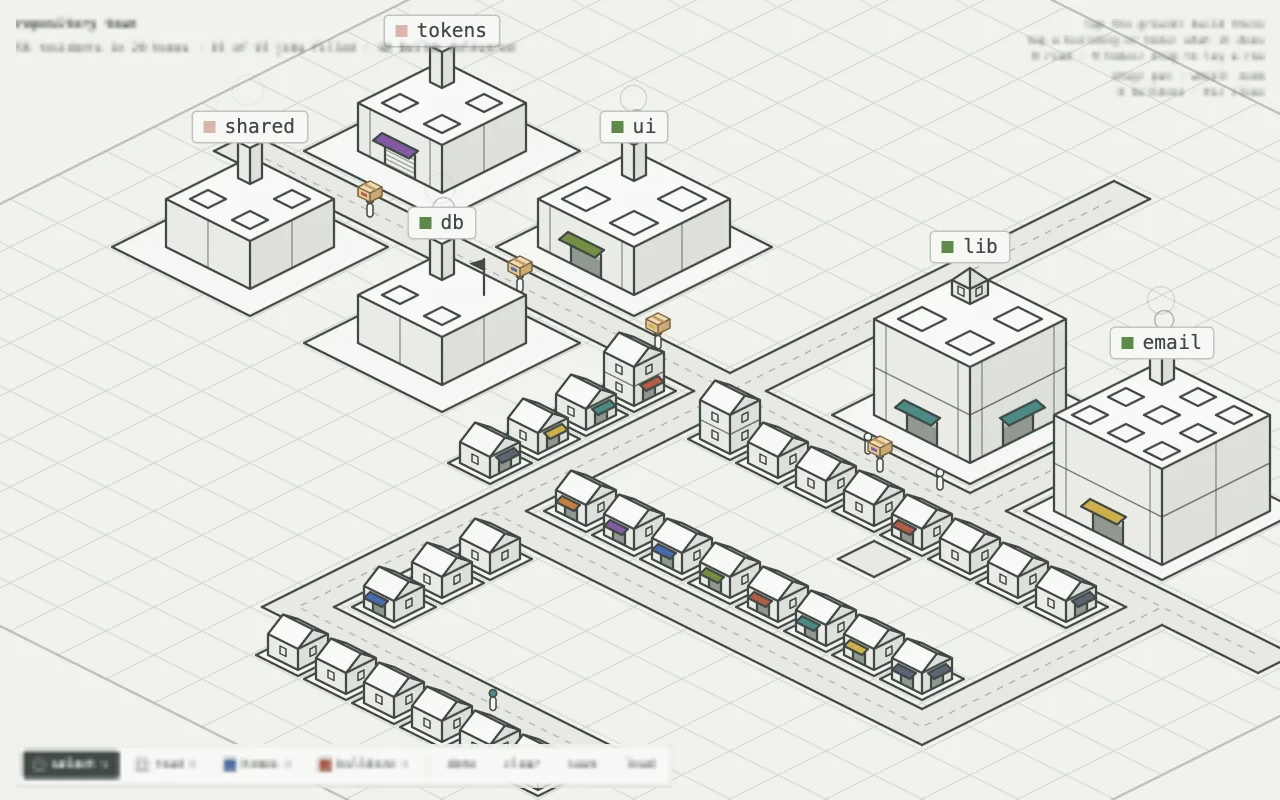 Oct 12, 13:10 · the first town
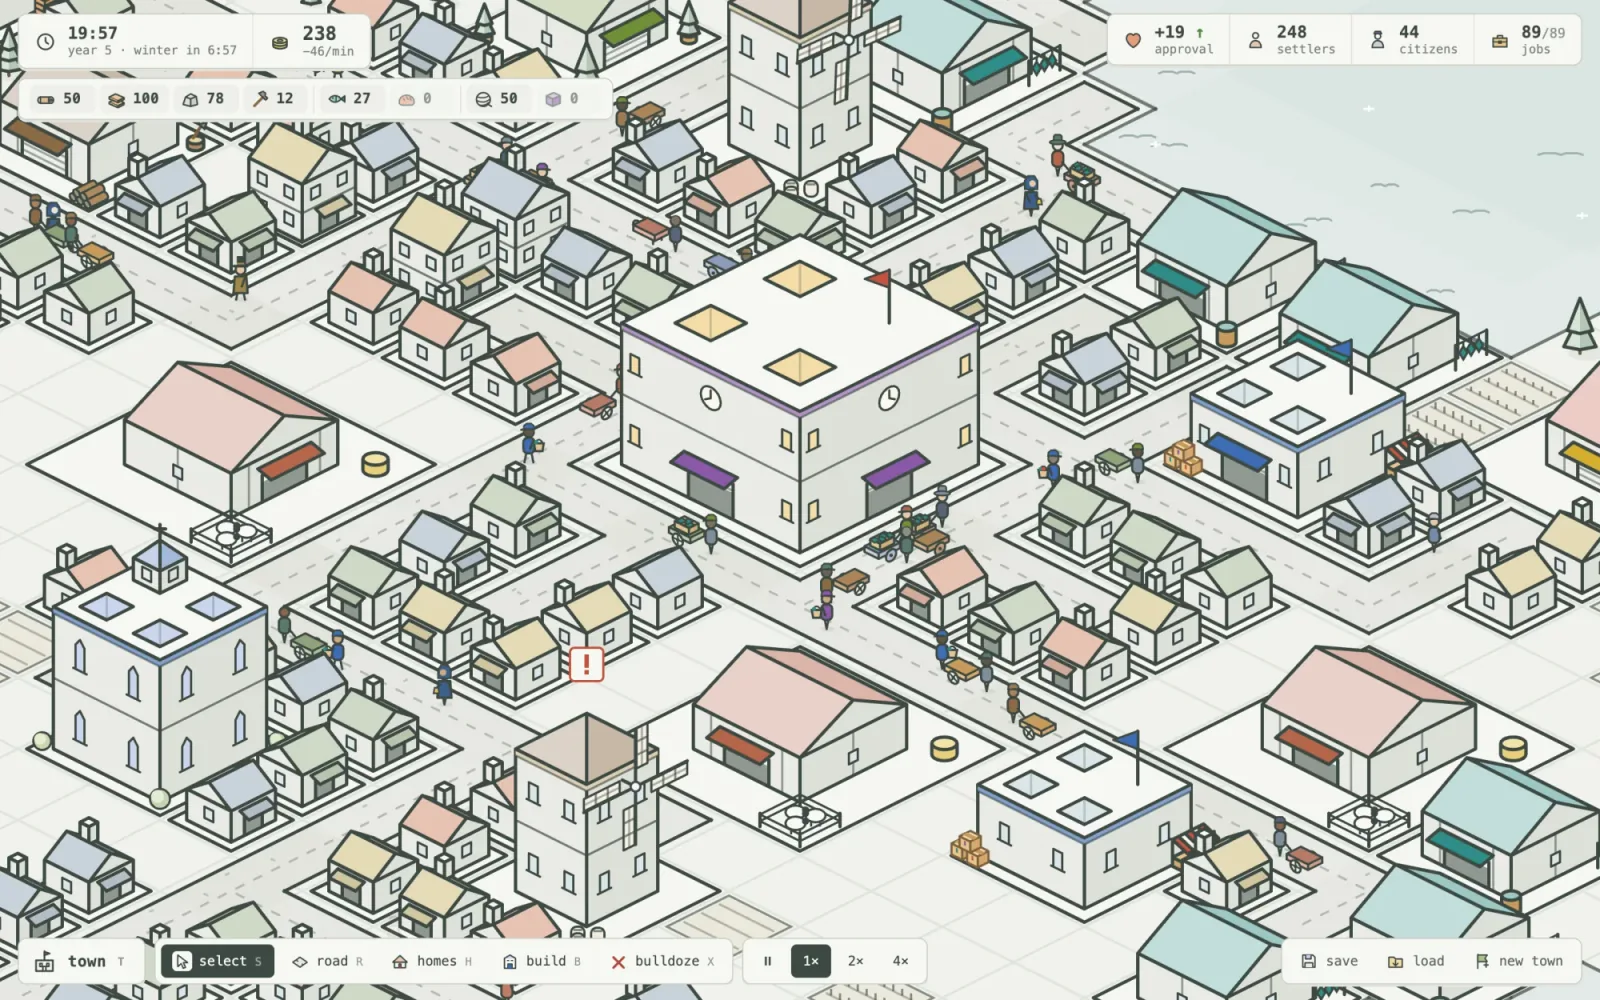 Oct 12, 20:37 · end of day one
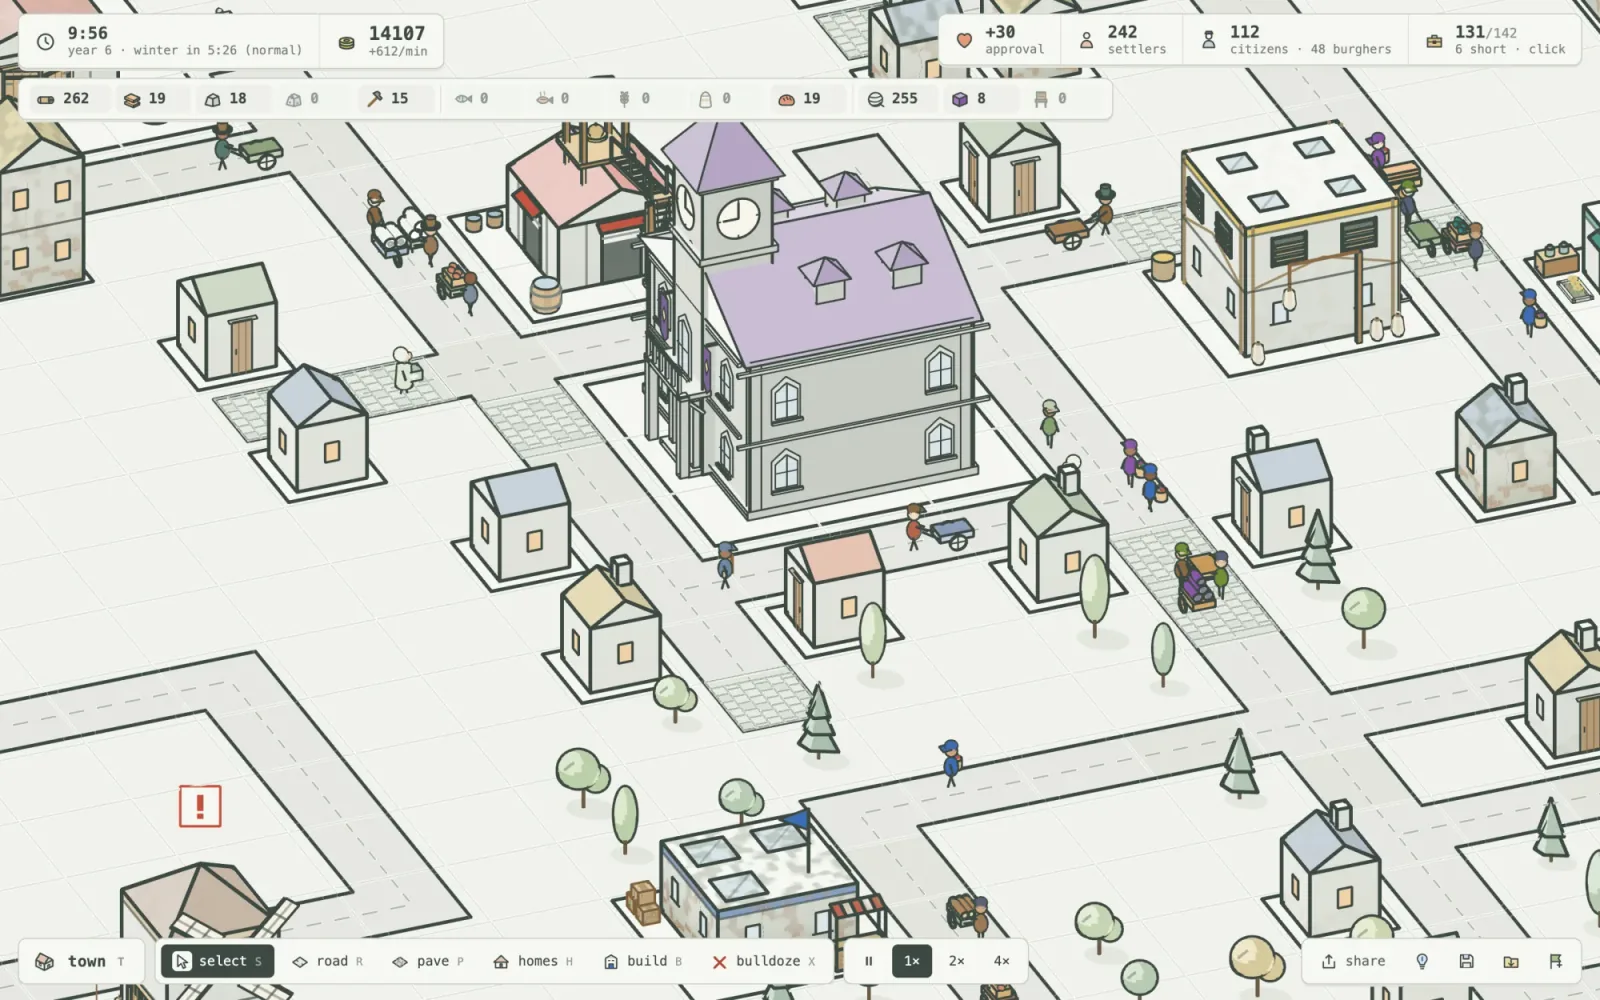 Oct 16 · day five
Two days for something playable, then six more for content, fun and balance.
Just check Inkline Town's own commits. From day two on, most of them tune something after a play session instead of building something new: nearly two thirds of all game commits.
The agent implements each of those changes in minutes. What takes time is figuring out what to implement: which mechanic is missing, why a system is boring, what a new player doesn't get.
Every round of that loop needs me: play, notice, decide, ask, play again.
I never touched a number in Inkline Town. To this day, I don't know how they're computed or how they move: I only ever saw the game.
I play for around 45 minutes, as a player. Then I report what I see:
Inkline Town's clearest case was food.
The town eats fish or bread. A fishery is one building; bread needs three buildings, all running. So I built fisheries, side by side on the same lake, and food stopped being a problem. Everyone was living on fish; bread had no reason to exist.
My bots had been playing the economy since the first day, and none of them noticed this bug.
An agent has no sense of balance: a strategy that makes the rest of the game pointless looks like any other strategy to it.
So I spoke the prompt below to the agent, as any human playtester would.
agent, next commitsI tested the game as a user and there are a few holes in the gameplay. Here is my winning strategy, see if you can find the holes in it.
I place about 10 homes, then , lumberjack, and stone.
While production keeps going, I buy some tools and start on bread and cloth.
As soon as I can, I upgrade the homes, and my money just keeps coming. Then it's just a matter of adding more homes, and I'm done.
This works all the time. Is there a hole that lets me exploit this and win every time?
The agent turns that into a fix, and then proves it, often with an automated economy simulation. And now that my playtests are recorded, it also has the exact numbers of the session I just played.
For the fisheries, the fix started with a model, not a number.
I knew that if one hole like this had slipped through, there were others, and that an economy like this can be checked with math: an agent can write that check as a test.
So I asked for an economy model that weighs every number in the game against the others.
It confirmed the fishery, and showed it wasn't alone: twelve rules of the economy were broken. Finding the issues took most of the time; fixing them was fast and easy.
The problems that broke the economy never came back, because for each one we added the assumption behind it to the model. What still needed my playtests was the kind of choices I wanted the player to face.
Getting from the ledger to the fix took the agent under an hour. My part was the 45-minute match, the report, and knowing to ask for the model.
Inkline Town's economy ledger on Oct 15: the rules the game broke, at each commit from the one that wrote the ledger to the one where every rule held.Some of the agent's work takes hours. I don't watch it. I don't review it.
When it's done, the checks have already run. Types compile, tests pass, lints are clean, simulations hold. Implementation is verified before it reaches me, against what the checks encode.
you 0:00AI 0:00
round 1 of 3, on repeat
Passing the checks doesn't mean the game is ready. What reaches me is what they miss: a side panel hiding a button, an unclear tutorial line, a mechanic that works exactly as specified but isn't fun.
Simple but glaring example: an empty side panel covering half the map. I sent the screenshot; half an hour and multiple iterations later, it was fixed.
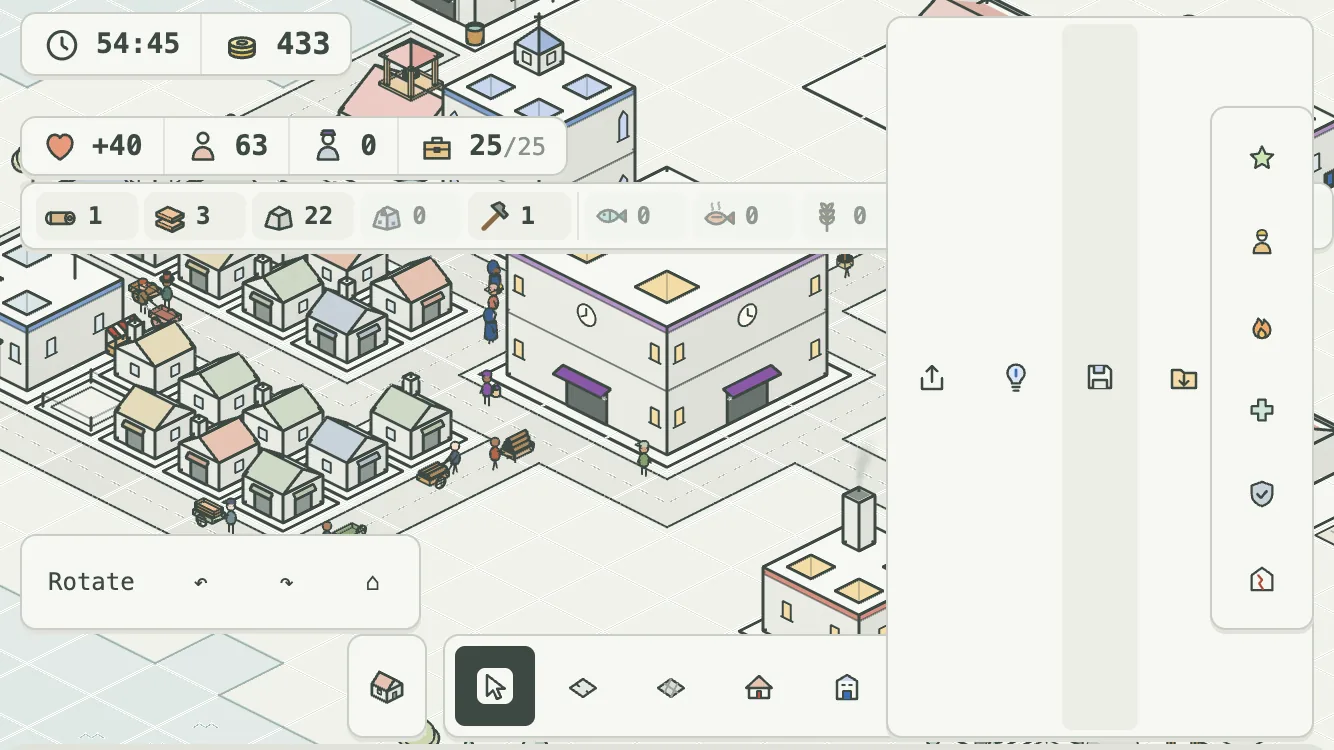 Oct 14, 10:19 · what I saw
 Oct 14, 10:52 · after the fix
Then I open the game (never the code) and restart it from the very beginning to judge what no check measures: whether it's fun.
Since I never know what the agent changed, every time I open the game I meet it fresh, like a new player: I read the UI for the first time and follow the tutorial step by step.
My reports mention what felt off and why, never how to fix it. My sessions are recorded, so the agent can replay my actions, take its own screenshots, and see the issue.
You can even create various bot profiles, each with different skills, as a check to balance the game:
The bots show which quests can be cleared, and catch it when a change breaks one. They don't tell you how many players would clear them, or whether it's fun.
The checks are only as good as the rules behind them. When one keeps failing, you need to tell whether the agent got it wrong or a rule is missing, and for that you need to know the tools underneath.
My trust came from the stack: my own engine plus Effect, which I know well enough to let the agent run.
If you're not into development or math, expect to hit a wall at some point.
Remember the fisheries: there, the wall was knowing to ask for a math model. Without that, you would be stuck in a much longer loop, fixing each case by hand from playtests.
If you have been building your game by hand for years, I know you are screaming: "But it stops being my game if I don't write any of it!"
It doesn't. Your contribution was never the code. It was the ideas, the feel, the hundreds of small decisions about what's fun. That is exactly the part AI can't do, and the part that now gets all your time.
If you enjoy writing every line, keep doing it. But if you want to make and sell games, building by hand means years on a game you're not sure will work, while an agent writes a full system in minutes, and the models keep getting better.
My prediction: on average, games made with an AI system will ship faster and sell better.
Not because AI makes better games, but because the time no longer spent on code goes into playtesting, fun, and the bugs only a human catches. If you keep writing code, you simply don't have enough resources for all of it.
If you want to make a game, here is the order:
It's still hard. It's faster. And, if you ask me, way more fun than before.
Why more fun? Because my time goes to the part I care about. Since code doesn't matter much, the focus is all on gameplay and game feel. I am playing more instead of bothering with code details.
And the final game is still mine, something that no agent alone could make.
Revised after reader feedback, with shorter sections.
New: screenshots from development, an interactive Spirit Call frame, a real agent session, and a chart of bots playing the game.
All of it comes from the games' repositories and the agents' own session logs.