 Log in


concurrently. That's a fair complaint, but DHH seems to think it's not the best look for Elixir that the clanker couldn't write performant code. Not sure if I agree when I look at the Rust version. Cause in the Rust version some of the database operations are not async, which in some cases may be worse. You see, in Rust, when using an async runtime, the scheduling is not preemptive, but rather cooperative

Hamburg, Germany


Featured in Javascript Weekly - 2026-09-08, Node Weekly - 2026-09-10, and Web Weekly #200
await fetch(url) looks like it waits for the response, but it only waits for the headers. By the time the promise settles you are holding a Response object whose body is still arriving over a connection that is very much open, and the code after your await runs while bytes are still on the wire. This is why you usually await twice:
const response = await fetch(url) // awaits the headers
const body = await response.json() // awaits the body
This gap is easy to miss because it's usually microscopic. When a server sends the headers and the body together, the distance between the fetch promise resolving and the last byte landing is a fraction of a millisecond, and nothing you write is going to notice it. Put a 300ms pause between the headers and the body and the promise still settles after about a millisecond, with the body finishing 300ms later. The resolution time doesn't move, because the thing it waits for happened at the same point it always does.
In this article we'll go through what the specification says the promise awaits for, what happens to the connection while you decide whether to read the body, what clone() does when there is nothing finished to copy yet, how abort behaves once you already have a Response in hand, and why a timeout you thought covered the request often doesn't. There are subtle browser and Node differences worth knowing about too.
The promise settles early
HTTP-network fetch is the algorithm that talks to the socket. Because a server may send provisional 1xx responses ahead of the real one, it loops over incoming status lines and discards anything in the 1xx range. When a final status shows up it waits for the last header byte, leaves the loop, attaches a fresh ReadableStream to the response, and hands that response back to its caller. Printed underneath that final step is a note: Typically response's body's stream is still being enqueued to after returning. The warning appears a second time in HTTP fetch, one level higher up the call chain.
The promise you are awaiting is resolved by an algorithm the spec calls processResponse, which is handed the response at that same moment and queued as a task. Nothing in that path consults the body, what you get back is a Response whose headers, status and URL are all final, and whose body is a stream that the network layer is still writing into from a buffer it fills as bytes arrive. Reading the body is a separate operation you have not started yet.
Run the following snippet in a browser console or Node REPL to see the gap in action:
const t0 = performance.now()
const response = await fetch('https://httpbin.org/drip?duration=3&numbytes=120&delay=0')
console.log('headers  ', (performance.now() - t0).toFixed(1), 'ms', response.status)
await response.arrayBuffer()
console.log('body done', (performance.now() - t0).toFixed(1), 'ms')
headers   250.7 ms 200
body done 3445.8 ms
The status and the headers are readable at 250ms, the last byte of the body arrives at 3445ms. On an ordinary endpoint that sends headers and body together the two numbers are a fraction of a millisecond apart, so the gap only becomes measurable when the server or the network is slow.
HEAD requests and the null body statuses (101, 103, 204, 205, 304) are exceptions. Main fetch sets their body to null and disregards any enqueuing toward it, so response.body is null rather than an empty stream and there is nothing still arriving. The rest of this article is about the other responses.
The socket is still yours
Checking the status and walking away is a common pattern: you send a request, the promise resolves, the status is 500 or 404 or simply not what you wanted, and you return early without touching response.body. Under HTTP/1.1 a connection carries one exchange at a time and can only be handed back to the pool once the current response has been read to its last byte. An unread body leaves bytes on the wire that nobody will ever take delivery of, and the client has no way to find the start of the next response, so the connection is closed rather than reused.
Whether that costs you anything depends on how big the body is. Ten sequential requests against a local server, first reading each body and then ignoring it, show where the boundary sits in Node:
import { createServer } from 'node:http'

let seen = new Set()
const server = createServer((req, res) => {
  seen.add(req.socket)
  const size = Number(new URL(req.url, 'http://x').searchParams.get('size'))
  res.writeHead(200, { 'content-type': 'application/octet-stream' })
  res.end(Buffer.alloc(size))
})
await new Promise((r) => server.listen(0, r))
const port = server.address().port

for (const kb of [4, 8, 16, 32, 64]) {
  const counts = []
  for (const read of [true, false]) {
    seen = new Set()
    for (let i = 0; i < 10; i++) {
      const response = await fetch(`<a href="http://localhost:" rel="nofollow">http://localhost:</a>${port}/?size=${kb * 1024}`)
      if (read) await response.arrayBuffer()
    }
    counts.push(seen.size)
  }
  console.log(`${kb}KB  read: ${counts[0]}  ignored: ${counts[1]}`)
}
server.close()
process.exit(0)
4KB   read: 2  ignored: 2
8KB   read: 2  ignored: 2
16KB  read: 2  ignored: 10
32KB  read: 2  ignored: 10
64KB  read: 2  ignored: 10
Below 16KB it makes no difference at all. The whole response has already arrived and been buffered by the time the promise resolves, so from the transport's point of view the exchange is complete whether or not your code ever looks at the bytes. From 16KB upward every ignored response burns a connection, and 10 requests need 10 of them instead of 2.
The number is a property of the runtime rather than of fetch. Chrome tolerates far larger unread bodies, reusing a single connection through 512KB and only starting to open extra ones somewhere between 512KB and 4MB. That is two orders of magnitude away from Node's boundary, which means what you can get away with in the browser may or may not work on the server. Both numbers come from the size of the buffers underneath, so neither is a guarantee to build on, and the safe reading is that a body you never touch may or may not cost you a connection depending on where the code runs.
(Which buffer that is, and how much of a never-read body the server actually manages to send before it stalls, is measured in the companion note in the import chaos newsletter: Director's Cut: Why 16KB, and what happens on HTTP/2.)
Cancelling the stream explicitly does not buy the connection back. Add await response.body.cancel() to the loop above in place of ignoring the response and the counts do not move: 2 connections at 4KB and 8KB, 10 at 16KB and above, the same as walking away without saying anything. Cancellation tells the stream you are not going to read it, which is information the connection can't act on, because the bytes the server already committed to sending are still undelivered either way. Reading the body to the end is the only thing that returns a connection to the pool.
The failure this produces is gradual. Twelve concurrent unread 4MB responses do not wedge the origin: the server receives all twelve across twelve sockets, and an unrelated request issued at the same time gets its headers back in under two milliseconds. What you get is connection growth, more sockets held open than the work requires, file descriptors on the server side, and a client pool that expands under load and shrinks again when the pressure comes off. Nothing breaks, which is why it can run in production for a long time before anyone asks why the connection count looks odd.
The reason a large body behaves differently from a small one is backpressure. The network layer fills an internal buffer as bytes arrive and stops pulling from the socket once that buffer exceeds a limit the implementation chooses, waiting for a reader to drain it. A small response never reaches the limit and is fully absorbed before you decide anything. A large one stops mid-transfer and waits for a consumer that, in this pattern, never turns up.
Clone copies nothing
A response body can only be read once. clone() is the escape hatch, and it is usually reached for when two pieces of code both want the payload: a cache that stores a copy while the caller gets the original, or a deduplicating layer handing the same in-flight request to several waiters. The name suggests a copy is made, which invites the assumption that some memory gets duplicated at the moment you call it and the two objects then go their separate ways.
There is nothing to copy at that moment. The spec defines cloning a body in one line: Let « out1, out2 » be the result of teeing body's stream. Teeing a stream produces two readers over one source, and the source here is a socket that is still delivering. What clone() actually creates is a fork in a pipe that is still running.
The consequence is that the two branches are tied together. A tee has to hand identical bytes to both, so a chunk pulled by whichever branch reads first has to be kept until the other branch asks for it. If one branch never asks, the chunks accumulate. Serving 60MB and sampling resident memory while it is read shows what that costs:
import { createServer } from 'node:http'

const MB = 1024 * 1024
const server = createServer((req, res) => {
  res.writeHead(200, { 'content-type': 'application/octet-stream' })
  const chunk = Buffer.alloc(MB)
  let sent = 0
  const write = () => {
    while (sent < 60 * MB) {
      sent += MB
      if (!res.write(chunk)) return res.once('drain', write)
    }
    res.end()
  }
  write()
})
await new Promise((r) => server.listen(0, r))
const url = `<a href="http://localhost:" rel="nofollow">http://localhost:</a>${server.address().port}/`

const mode = process.argv[2]
let max = 0
const sampler = setInterval(() => {
  max = Math.max(max, process.memoryUsage().rss)
}, 5)

const response = await fetch(url)
const copy = mode === 'plain' ? null : response.clone()
await response.arrayBuffer()

clearInterval(sampler)
console.log(mode, (max / MB).toFixed(1), 'MB')
server.close()
process.exit(0)
Each mode has to run in its own process, otherwise the second measurement inherits a heap the first one already grew and the numbers mean nothing:
plain    116.1 MB
clone    169.3 MB
The abandoned branch costs roughly another 55MB, close to the size of the response, because the tee is holding a second reference to every chunk on behalf of a reader that never arrives.
The buffered data is genuinely retained rather than re-fetched. Reading the first branch to the end, waiting half a second so the exchange is definitively over, and only then reading the abandoned branch still produces the full 60MB, far faster than the network delivered it the first time:
import { createServer } from 'node:http'

const server = createServer((_, res) => {
  res.writeHead(200, { 'content-type': 'application/octet-stream' })
  res.end(Buffer.alloc(60 * 1024 * 1024))
})
await new Promise((r) => server.listen(0, r))
const url = `<a href="http://localhost:" rel="nofollow">http://localhost:</a>${server.address().port}/`


const response = await fetch(url)
const copy = response.clone()
const first = await response.arrayBuffer()
console.log('first branch', first.byteLength)

await new Promise((r) => setTimeout(r, 500))
const t0 = performance.now()
const second = await copy.arrayBuffer()
console.log('second branch', second.byteLength, 'in', (performance.now() - t0).toFixed(1), 'ms')

server.close()
process.exit(0)
first branch 62914560
second branch 62914560 in 32.5 ms
The examples below reuse that same seven-line server, so only the part after const url changes.
That memory is held for as long as the unread branch is reachable. In a cache that clones a response and writes the copy asynchronously, the clone stays alive until the write completes, and the whole payload sits in memory in the meantime. The Durable Objects cache calls .clone() at three separate points for exactly this reason, once per consumer of a shared response, and each of those calls is a fork that has to be drained by somebody.
The ordering rule follows from the same mechanism. There is only one stream to fork, so the fork has to happen before anything starts pulling from it:
const response = await fetch(url)
await response.arrayBuffer()
response.clone()
// TypeError: Response.clone: Body has already been consumed.
A single read() produces the same error, since one chunk taken from the source is enough to make the two branches unequal. response.bodyUsed reports the state, and it is per object rather than shared, so after the original has been read it is true there and false on the copy. Body consumption rules and the fact that TypeScript cannot express any of this are covered in Decorating Promises Without Breaking Them.
Cancelling a clone you have decided not to read does release the retained chunks. Adding copy.body.cancel() to the measurement above brings it to 109.7MB, marginally under the plain read, and it comes with a trap:
const response = await fetch(url)
const copy = response.clone()
await copy.body.cancel()
await response.arrayBuffer()
That deadlocks. Cancelling one branch of a tee returns a promise that stays pending until the other branch has finished, and the other branch is on the line below, never reached. Starting the cancel without awaiting it and watching when it settles shows the dependency:
const response = await fetch(url)
const copy = response.clone()

const t0 = performance.now()
let settled = false
copy.body.cancel().then(() => {
  settled = true
  console.log('cancel settled at', (performance.now() - t0).toFixed(1))
})

await new Promise((r) => setTimeout(r, 200))
console.log('after 200ms, settled?', settled)

await response.arrayBuffer()
console.log('original read at', (performance.now() - t0).toFixed(1))
after 200ms, settled? false
cancel settled at 464.6
original read at 465.4
The cancel is still pending two hundred milliseconds later and only settles when the other branch reaches the end of the response, which is why awaiting it first never returns.
When both branches are read at roughly the same rate, the buffering stays small and clone() costs almost nothing. The expensive case is the asymmetric one, where a fast consumer races ahead and a slow one lags, or where a branch is created for a purpose that later turns out not to need it.
Abort outlives the promise
The mental model most code is written against is that AbortSignal cancels a request in flight, and that once the promise has resolved the request is done and there is nothing left to cancel. The first half is right, the second half assumes the promise resolving means the exchange finished, which is the assumption this whole article is about.
Aborting before the headers arrive gives the familiar result. The promise rejects, there is no Response, and the failure lands wherever the await was. This one needs a server that holds the headers back, so it gets a 300ms delay in front of writeHead and an abort at 50ms:
import { createServer } from 'node:http'

const server = createServer((_, res) => {
  setTimeout(() => {
    res.writeHead(200, { 'content-type': 'application/octet-stream' })
    res.end(Buffer.alloc(60 * 1024 * 1024))
  }, 300)
})
await new Promise((r) => server.listen(0, r))
const url = `<a href="http://localhost:" rel="nofollow">http://localhost:</a>${server.address().port}/`

const controller = new AbortController()
setTimeout(() => controller.abort(), 50)
await fetch(url, { signal: controller.signal })
// DOMException [AbortError]: This operation was aborted
The three examples that follow use the same server without the delay, the seven-line version from the previous section.
Aborting after the promise has resolved is a different operation with a different shape. The Response already exists and nothing can take it away, so the rejection surfaces at the next attempt to pull from the body:
const controller = new AbortController()
const response = await fetch(url, { signal: controller.signal })
const reader = response.body.getReader()
const first = await reader.read()
console.log('first chunk', first.value.byteLength)

controller.abort()
await reader.read()
// DOMException [AbortError]: This operation was aborted
first chunk 65356
The first chunk is already in hand and stays valid. The second read() rejects. On the server side the request emits aborted and the response closes with writableFinished false, so this is a real disconnect rather than a client-side pretence: the remaining bytes are never sent, which is the outcome you wanted and the reason aborting a large download partway through is worth doing.
Everything that arrived before the abort remains readable, and so does everything that was never part of the body. Status and headers are properties of an object you already hold:
const controller = new AbortController()
const response = await fetch(url, { signal: controller.signal })
controller.abort()
console.log(response.status, response.headers.get('content-type'))
// 200 application/octet-stream
await response.arrayBuffer()
// DOMException [AbortError]: The operation was aborted.
The convenience methods have no way to deliver a partial result, so arrayBuffer, json and text reject outright if the abort lands before they finish. Reading through getReader() is what lets you keep the chunks that already arrived, which matters when a partial body is useful, and does not when it isn't.
Once the body has been read to the end, abort() does nothing at all and throws nothing:
const controller = new AbortController()
const response = await fetch(url, { signal: controller.signal })
const body = await response.arrayBuffer()
controller.abort()
console.log('read', body.byteLength, 'bytes, abort threw nothing')
// read 62914560 bytes, abort threw nothing
There is no error to report because the operation it would have cancelled is over. That makes an abort call safe to leave in a cleanup path, which is convenient, and also means the call succeeding tells you nothing about whether anything was actually cancelled.
The cooperative model underneath is covered in Cancellation In JavaScript: a signal expresses intent and the operation decides how to honour it. What fetch adds is that the operation stays honourable for longer than the promise suggests. The signal is not spent when the promise settles, and it stays wired to the body until the last chunk lands.
The timeout that only covered half the request
A timeout written as a race between the fetch promise and a setTimeout rejection is a well-known pattern, putting a deadline on the promise. Since the promise settles when the headers have been parsed, the deadline covers the header phase and stops applying at the moment the body starts arriving.
Both servers below are the same server, distinguished by path. /slow-body sends the headers immediately and then writes 80 chunks of 64KB at ten millisecond intervals. /slow-headers waits 800ms before writeHead and then sends a single chunk. Each stalls in one phase and runs at full speed in the other:
import { createServer } from 'node:http'

const CHUNK = 64 * 1024
const server = createServer((req, res) => {
  const delay = req.url === '/slow-headers' ? 800 : 0
  setTimeout(() => {
    res.writeHead(200, { 'content-type': 'application/octet-stream' })
    if (delay) return res.end(Buffer.alloc(CHUNK))
    let sent = 0
    const tick = setInterval(() => {
      res.write(Buffer.alloc(CHUNK))
      if (++sent === 80) {
        clearInterval(tick)
        res.end()
      }
    }, 10)
  }, delay)
})
await new Promise((r) => server.listen(0, r))
const url = `<a href="http://localhost:" rel="nofollow">http://localhost:</a>${server.address().port}`

const withTimeout = (promise, ms) =>
  Promise.race([
    promise,
    new Promise((_, reject) => setTimeout(() => reject(new Error('timeout')), ms)),
  ])

const t0 = performance.now()
const response = await withTimeout(fetch(`${url}/slow-body`), 200)
console.log('race settled at', (performance.now() - t0).toFixed(1))
const body = await response.arrayBuffer()
console.log('body', body.byteLength, 'bytes at', (performance.now() - t0).toFixed(1))

server.close()
process.exit(0)
race settled at 59.7
body 5242880 bytes at 1251.3
The race is over at 59ms with a Response in hand, so the timer loses and is never going to fire again. The 200ms budget is spent by the time the interesting part of the request begins, and the operation finishes at 1251ms with nothing to stop it. Point the same code at /slow-headers and it behaves exactly as advertised, rejecting with timeout at 225.9, because the phase it guards is the phase that was slow. The code is identical in both runs, which is why this is hard to catch by reading it.
AbortSignal.timeout is passed into the request rather than raced against the promise, and the signal stays attached to the response for as long as the body is still arriving, as the previous section showed. It therefore expires in whichever phase happens to be running when the budget runs out:
for (const path of ['/slow-body', '/slow-headers']) {
  const t0 = performance.now()
  try {
    const response = await fetch(`${url}${path}`, { signal: AbortSignal.timeout(200) })
    const body = await response.arrayBuffer()
    console.log(path, 'read', body.byteLength, 'at', (performance.now() - t0).toFixed(1))
  } catch (error) {
    console.log(path, error.name, 'at', (performance.now() - t0).toFixed(1))
  }
}
/slow-body    TimeoutError at 203.2
/slow-headers TimeoutError at 213.4
Both cases now stop within a few milliseconds of the budget. The slow body is cut off partway through delivery, which the racing version could not do, since by then it had no way to reach the request any more.
If you reproduce this in a browser, keep the tab in the foreground. Chrome clamps setTimeout in backgrounded tabs to roughly one second, so a 200ms budget in an unfocused tab fires somewhere after 800ms and a correctly behaving timeout looks broken. The first run of this measurement was discarded for that reason.
Composing the budget with any other signal is another problem, because a request usually has more than one reason to stop. My http library ffetch builds a single signal out of the caller's signal, the signal a request transform may have introduced, its timeout signal, and an internal controller it uses for its own cancellation, then passes the result of AbortSignal.any into fetch. Any one of those firing aborts the request, and because it goes in as the request's signal rather than around the promise, it keeps working after the headers have arrived.
Reading the body is the real work
Everything so far has been a consequence of the same fact, approached from a different side each time: the connection stays open because the body has not arrived. clone() tees rather than copies because the body has not arrived. Abort still bites after the promise resolves because the body has not arrived. A racing timeout misses the slow case because the body has not arrived.
This gap is the reason a useful set of things is possible at all. response.body is a ReadableStream, and a stream that is still being written into can be piped through something before anyone reads the far end. Counting bytes as they pass is the plainest example:
import { createServer } from 'node:http'

const CHUNK = 64 * 1024
const server = createServer((_, res) => {
  res.writeHead(200, {
    'content-type': 'application/octet-stream',
    'content-length': String(80 * CHUNK),
  })
  let sent = 0
  const tick = setInterval(() => {
    res.write(Buffer.alloc(CHUNK))
    if (++sent === 80) {
      clearInterval(tick)
      res.end()
    }
  }, 10)
})
await new Promise((r) => server.listen(0, r))
const url = `<a href="http://localhost:" rel="nofollow">http://localhost:</a>${server.address().port}/`

const t0 = performance.now()
const response = await fetch(url)
console.log('promise settled at', (performance.now() - t0).toFixed(1))

const total = Number(response.headers.get('content-length'))
let transferred = 0

const counted = new Response(
  response.body.pipeThrough(
    new TransformStream({
      transform(chunk, controller) {
        transferred += chunk.byteLength
        const percent = Math.round((transferred / total) * 100)
        if (percent % 25 === 0) {
          console.log(percent, '% at', (performance.now() - t0).toFixed(1))
        }
        controller.enqueue(chunk)
      },
    })
  ),
  { status: response.status, headers: response.headers }
)

const body = await counted.arrayBuffer()
console.log('read', body.byteLength, 'at', (performance.now() - t0).toFixed(1))

server.close()
process.exit(0)
promise settled at 52.6
25 % at 340.4
50 % at 639.9
75 % at 948.4
100 % at 1257.6
read 5242880 at 1262.3
The promise settled at 52ms and the progress lines are spread across the twelve hundred milliseconds that followed. Those numbers only exist because there was something left to observe after the await returned. content-length is readable at that point too, which is what makes a percentage possible at all, since the total is in the headers and the running count is in the stream.
Wrapping matters as much as the counting: pipeThrough gives back a stream rather than a Response, so the transformed stream goes into a new Response along with the original status and headers, and whoever gets that object can call json() or arrayBuffer() on it without knowing anything happened. This is the shape ffetch's download progress plugin uses in src/plugins/download-progress.ts: it returns early when response.body is null, since there is nothing to transform for a HEAD or a 204, parses content-length defensively because a server may send something that is not a number, counts bytes in the transform and enqueues each chunk unchanged, then rebuilds the Response around the new stream. A plugin that intercepts a response and hands back a different one is only possible because the interception happens before the payload exists.
So await fetch(url) is worth reading as what it is, the point where the headers are complete and the body is about to start. Nothing after that line is safe to treat as the end of the request. The connection, the memory, the cancellation and the deadline all belong to the part that comes next, and the code you write after the await is the code that decides how that part goes.
Hamburg, Germany
Over the last several months I have been tracking AI guys trying to create vibe coded clones of popular apps, especially Adobe’s apps which have always been the most pirated apps since the 90s.
There are now about a dozen vibe coded attempts to clone Photoshop and some other Adobe apps, not including dozens of forks of them. People like this aren't just openly copying Adobe's apps. It's Microsoft, Avid, Autodesk and whoever else is in their sights next including game devs big and small.
Automated or semi-automated cloning to steal revenue away from developers isn’t new. In the early 2000s when Google released Adsense hundreds of Adsense filled spam sites sprung up and cluttered the search engines. If your own site ever had a popular page or article, bots would clone your pages and republish your content on spam sites, stealing traffic away from you. That’s the same unethical and spammy behaviour we are seeing today when AI guys vibe-clone a copy of your apps.
Directly stealing the look and feel of a product but changing the name is what the counterfeit goods market does. This is the same thing but in software.
The amount being spent in AI tokens (API costs) is in the thousands of dollars per project. The largest attempt to vibe clone Adobe’s apps has over 70 devs at the time of writing (update: 165 now, it is rising daily) using Claude to submit 100s of pull requests per day. The amount they are spending on tokens must be over $50,000 in the last two weeks. I will not name this project and don’t want to give them traffic that they do not deserve. Those dozens of devs will be spamming all the social media platforms with their alt accounts anyway.
Yet despite this not one of these vibe coded projects has been able to create a brush engine that matches Photoshop’s brush engine. The performance of their brushes collapses once the canvas size is over 8K x 8K pixels. Photoshop’s brushes work smoothly even when you’re working with 100 megapixel images out of a Hasselblad or Phase One camera. If you’re trying to build a Photoshop competitor in the year 2026 you should be building the engine first and then adding all the advanced features on top later, not the other way around. Unless your intention is just to generate headlines and promote an AI business.
In the Photoshop clone that is getting the most attention, on the billboard size canvas test above Copy/Paste and the Undo stack is extremely slow and momentarily freezes the application each time. This is basic stuff that decent software developers had working well 25 years ago when we had single core computers and nowhere close to 1GB of memory. If you can't get decent performance today on multicore multi gigahertz computers with many gigabytes of memory you or your AI are not doing a good job.
Those defending the poor performance of vibe coded apps have parroted the famous lines AI guys used in the past - “It is only days old” and “this is the worst it gets”. They make the mistake of equating human app development time with generative AI development time (hundreds of times faster). A vibe coded app is, in human hours, not only a few days old but closer to two or three years old. If a brush engine or transform tool works badly after the human equivalent of three years of development that is a demonstration of bad planning or an AI model not doing a good job.
Brush performance aside, each of these projects struggle with 100% file format compatibility and lossless image editing. Image previews while applying filters are downscaled to low res previews to maintain usable speed. Colour profile rendering and soft proofing is hit and miss. Support for the vast number of colour profiles and print profiles is bare. On some platforms many common fonts aren’t available because they require licensing. So instead of innovating and pushing forward they have successfully rewinded the clock back to 1996 when there was a lack of industry standardisation, compatibility and quality.
They’re spending minimum $2K to vibe code a Photoshop competitor when Affinity Photo is free and Photoshop costs $200 a year. Not very smart economics.
They rant and claim the era of subscription software is finished, but they are subscribed to AI services and AI software. The amount they are paying to AI companies is far higher than the cost of Adobe, Autodesk, Canva or Maxxon applications, and the result is barely usable vibe coded apps that will need to be continually maintained at high cost.
Vibe coders brag about their app binaries being much smaller than Adobe’s app binaries, as if that has something to do with the quality of the code. It does not. Application code (which is just text) takes up very little disk space in any application. What takes up the most amount of disk space are the frameworks, libraries, models and media assets an app ships with. The more advanced and capable an app is the larger it will become. But the size on disk is largely irrelevant in the age of terabyte+ size disks. The size of an app in memory, the app’s performance and its stability are how you judge the quality of an application.
Continuing from the last point, they and internet commentors have often made claims that Adobe’s apps have “bloat” in them, but if you ask them to qualify what they mean by bloat they cannot. They will revert to application binary size again. These are mostly people who have no knowledge of programming and parrot each other. An app either has good quality code that performs well or it doesn’t. An app can have tons of redundant functions in it but functions do not run unless they are called by a tool.
Whether software is vibe coded or not, open source software has rarely challenged commercial software. Krita has been around for years and is a decent application, but Clip Studio Paint’s subscriptions earn Celsys millions of dollars a year. Nobody is giving up Clip Studio Paint for software that has rough edges. Blender is a fantastic application, but expensive high end apps like Maya are still the 3D animation applications of choice for larger studios and commercial productions.
In a 2026 survey of 150 CG production companies in Japan, when asked for their main 3D animation suite 58% named Maya, 17% 3ds Max, 12% Blender, and 7% Cinema 4D. The picture is similar elsewhere.
Commercial apps innovate and lead. Open source apps like Blender follow the lead. Innovation costs a lot of money. Clip Paint Studio, Maya, 3ds Max and Cinema 4D, btw, are all subscription applications. But because those apps aren’t in demand by pirates Autodesk has not experienced the hate and bullying campaigns that Adobe has received.
And when it comes to customer support things become even sadder looking. One or two guys in a Discord chatroom cannot support a global user base, especially when those two guys are hunting for underage children to speak to on Discord (yes, I have seen what vibe coders do).
Here we see Photoshop versus a vibe-cloned copy of Photoshop. We test brush stroke performance on a billboard-size canvas with the brush set to 1000 pixels size. Photoshop handles this with no issue. Its commercial competitors struggle to match brush performance. The vibe-coded clones perform the worst (basically unusable).
The saddest part in all this is how it feeds into the ignorance and online hate campaign against Adobe that we have seen in the last 5 or so years. Some have labelled it ‘Adobe derangement syndrome’, but whatever it is it is a mix of stock market manipulation (some admit it) and anger that Photoshop has been getting harder to pirate ever since cloud services were integrated into Adobe’s application suite.
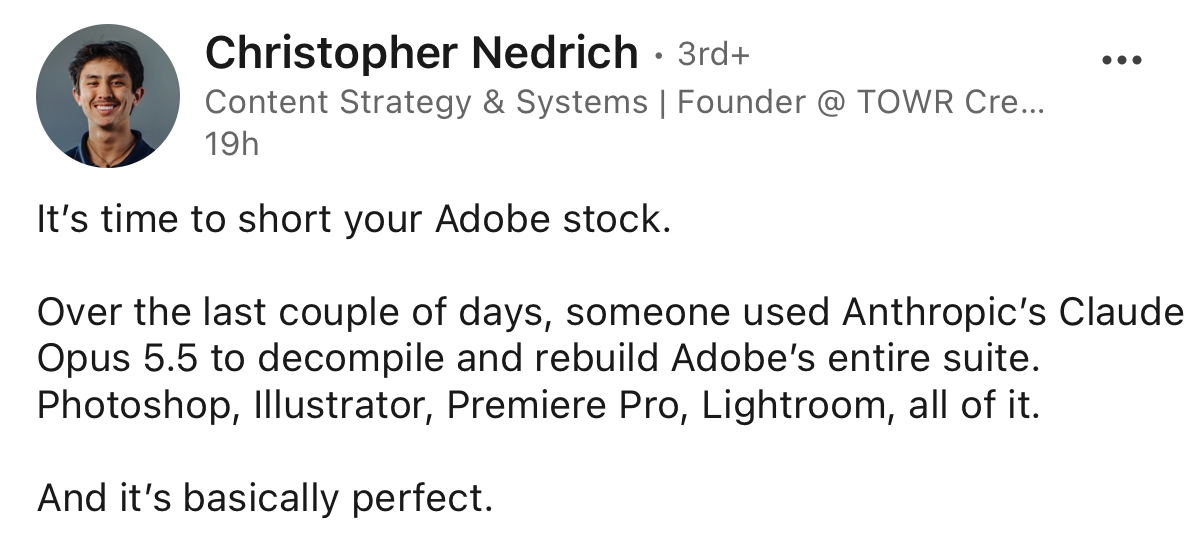
An example above of the kind of misinformation spreading low-lifes that infest Reddit and LinkedIn.
We should clear the air here. Subscription software exists when cloud services and cloud compute are integrated into a software suite. It is the only way to pay for the running costs at wide scale. If you remove these modern services there is limited progress in software development. You'll have to move all high cost compute locally which is impractical because most users cannot afford a high end workstation GPU or cloud server.
Instead of hurling hate speech and bile at thousands of software engineers who lead innovation at large companies (Adobe, Autodesk, Maxxon, Celsys, and others), show them some gratitude for their efforts. They are the engineers who innovate and everyone else follows. Just because they work at a big company doesn't mean they are committing human rights abuses. We have a generation brainwashed by envy and hate instead of urging everyone to be greater and bigger.
If some people have an issue with companies being large, they now have the tools to compete against them. But instead of vibe cloning poor quality rip offs why not build new original creative applications around fresh ideas that have never been tried before?
But then again, vibe cloned piracy is a demotivating force. It ruins the incentive to create. Why create new original apps and games if someone comes along and rips you off?
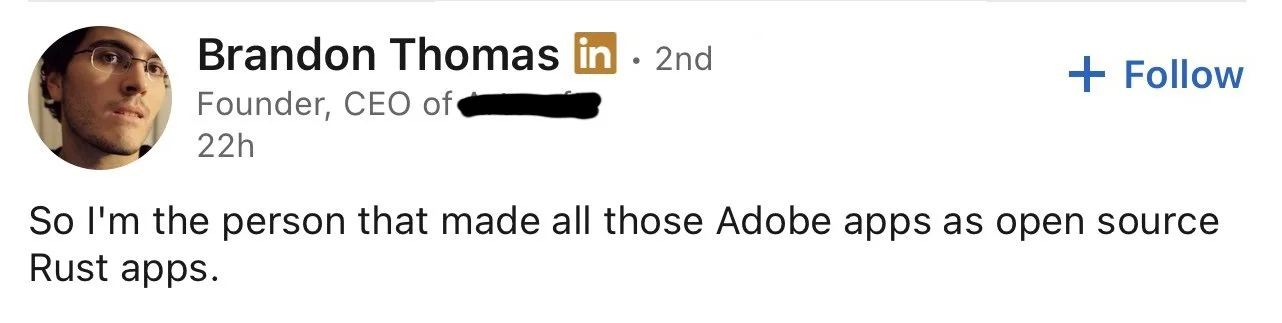
You’re giving yourself too much credit Brandon. There are dozens of people in your GitHub repo and they are all subscribed to a chatbot that is doing almost all the coding after being fed screenshots of Adobe’s apps.
Hamburg, Germany
Last week TypeSafe AI released Jev, which it calls the first “System One model”: a model that does not chat, does not write, and does not reason step by step. It answers structured questions about an input, in a single forward pass, with a probability attached to every answer. Most of the coverage has focused on speed. I think the more interesting claim is the one about calibration, because calibration is the thing that has quietly limited every production classifier I have shipped, including the one in my COMPSAC paper.
This post is my attempt to work out what Jev actually changes, where it fits in a real ML stack, and how I intend to test the claim rather than take it on faith.
What Jev is, without the marketingLink to section: What Jev is, without the marketing
Jev is built around three ideas, per TypeSafe’s launch post:
- Non-autoregressive output. A normal LLM produces its answer one token at a time, and each token depends on the last. Jev emits the entire structured answer at once. That is where the speed comes from: TypeSafe quotes 70–500 ms end to end and “40x–200x faster” than frontier LLMs on equivalent tasks.1
- Typed questions, not prompts. You send a state (text, structured data, or a message history) and a set of questions. Each question is one of three types: choice (pick from a set, get a probability per option), score (rate against ordered levels, get a continuous score and distribution), or noul (a yes/no, returned as the probability the statement is true).2 Every question in a request is evaluated in parallel, so adding questions barely changes latency.
- Training for calibration. The model is trained with what TypeSafe calls reinforcement learning for calibrated decisions (RLCD). The stated goal is “epistemically honest probabilities” rather than the human-preference or verifiable-reward objectives that chat models are tuned on.1
The constraints are just as important as the features. Jev cannot generate free text. A choice question supports at most 255 options. There is no image input yet. Pricing is $0.042 per million input tokens with output tokens free, and access is currently by waitlist.1
So it is not a smaller GPT. It is closer to a very fast, very general tabular classifier that reads unstructured input and returns a typed decision with a confidence you are meant to be able to trust.
Why calibration, not accuracy, is the real bottleneckLink to section: Why calibration, not accuracy, is the real bottleneck
Here is the part of my own paper I keep coming back to. We predicted whether a pull request would be merged, using only signals available at submission time. Random Forest hit an F1 of 0.958. The majority-class baseline, which says “merged” to everything, hit 0.957. The number that actually separated a useful model from a useless one was ROC-AUC: 0.676 for the forest versus 0.500 for the baseline. And even at that, we wrote plainly that the models “should not be treated as perfectly calibrated probability models” and were fit for triage, not for automated accept/reject decisions.3
That is not a quirk of one dataset. It is the normal shape of a production classifier:
- Accuracy saturates early. On imbalanced problems, most of the available accuracy is free. The hard part is the ranking and the confidence.
- Downstream logic needs probabilities, not labels. “Route this order to manual review if the model is less than 80% sure” only works if 80% means 80%. If the model says 0.95 on things that are right 70% of the time, every threshold you set is a lie.
- Miscalibration is invisible in the usual metrics. F1, accuracy, even AUC are all threshold or rank metrics. A model can have a fine AUC and terrible calibration, and you will not know until the business rule built on top of it starts misfiring.
The standard fixes are post-hoc: Platt scaling, isotonic regression, temperature scaling. They work, but they are another fitted component that drifts when the data does. What Jev is claiming, if I read it correctly, is that the probabilities come out of the model already honest, because honesty was the training objective. If that holds on tasks outside TypeSafe’s own benchmarks, it removes a whole layer of glue from production ML systems.
That “if” is the entire question, and it is testable.
Where a System One model fits in a real stackLink to section: Where a System One model fits in a real stack
I work on ML inside a wholesale distribution business. Almost none of it is chat. Most of it is small, repeated decisions that sit between two systems:
| Decision | Today | Why it is annoying | Does Jev’s shape fit? |
|---|---|---|---|
| Is this inbound order an exception that needs a human? | Rules plus a small classifier | Rules rot; retraining the classifier is a project | Yes: a noul with a threshold |
| Which regulatory product category does this new SKU belong to? | Keyword rules, manual cleanup | Vendor descriptions are messy free text | Yes, if categories fit in 255 choices |
| How urgent is this customer support message? | Nothing, or an LLM call that takes seconds | Latency and cost make it hard to run on every message | Yes: a score over ordered levels |
| Which delivery route should absorb this late order? | Constraint solver | Not a classification problem at all | No |
| Write the customer-facing note explaining a substitution | LLM | Needs generated text | No |
The pattern is clear. Anywhere I have an LLM doing a job that is really classification wearing a chat costume, a System One model is a plausible replacement with two orders of magnitude less latency and cost. Anywhere I have hand-written rules that keep breaking because the input is free text, it is a plausible replacement for the rules. Anywhere the job is generation or optimization, it is the wrong tool and TypeSafe says so themselves.
The ERP integration story is also attractive. A model that returns {"is_exception": 0.93} in 100 ms can sit inside a request path. An LLM that returns a paragraph in four seconds has to sit beside it in a queue. That difference decides whether ML is a feature or a batch job.
The claims I am not ready to accept yetLink to section: The claims I am not ready to accept yet
A few things in the launch material deserve a skeptical reading.
“Zero hallucination.” What TypeSafe can guarantee is that the output type is always valid: you asked for one of five categories, you get one of five categories, with probabilities that sum to one. That is real and useful, and LLM structured-output modes only approximate it. But it says nothing about whether the chosen category is right. A confidently wrong answer in a valid schema is still a wrong answer. The honest framing is “zero schema errors,” and calibration is what has to cover the rest.
Calibration on whose distribution? A model can be well calibrated on its training and benchmark distribution and drift badly on yours. Calibration is a property of a model and a dataset. The only number I will trust is one measured on my data.
The comparison baseline. “200x faster than an LLM on classification” is true and also a bit unfair, because the right baseline for many of these tasks is not an LLM. It is a gradient-boosted tree on engineered features, which is also sub-millisecond and free. The interesting comparison is three-way: classical tabular model, LLM-as-classifier, and Jev, on the same task, on accuracy, ranking, calibration, latency and cost.
The experiment I want to runLink to section: The experiment I want to run
I have exactly the right testbed already built: the PR acceptance pipeline from my paper. It is leakage-aware, it has fixed 5-fold splits, and it has a published tree-model baseline with a known calibration weakness. Here is the design.
Task. Same as RQ1 in the paper: given a PR at submission time, predict merged vs. closed without merge. The Jev state will be the PR title, body, and the same submission-time metadata and diff statistics the trees see, serialized as text. Nothing that appears after submission (comments, CI, later commits) goes into the state. The leakage rules do not relax because the model is new.
Questions. One noul: “This pull request will be merged.” Optionally one choice over the task-intent tags (fix, feature, refactor, docs) to see whether Jev’s own reading of intent agrees with our keyword rules.
Baselines. The paper’s Random Forest (400 trees), the same forest with isotonic calibration fitted in-fold, and a frontier LLM asked the same question with structured output.
Metrics. Ranking and calibration, not just F1:
- ROC-AUC, so the result is comparable to the paper.
- Brier score, the mean squared error of the probability against the outcome:
- Expected calibration error, binning predictions by confidence and measuring how far each bin’s accuracy is from its stated confidence:
- A reliability diagram per model, because a single ECE number hides where a model is over- or under-confident.
- Median and p95 latency, and cost per 1,000 PRs.
What would change my mind. If Jev matches the forest’s AUC and beats the calibrated forest on Brier and ECE, without any post-hoc fitting, then the calibration claim is real on a distribution TypeSafe never saw, and I would start moving classification-shaped LLM calls at work onto it. If it beats the uncalibrated forest but not the calibrated one, then it is a convenience, not a capability. If its AUC is materially lower, the speed does not matter.
I will publish the numbers either way, and I will link them from here.
What I would tell a team todayLink to section: What I would tell a team today
If you are deciding whether to care about Jev right now, my advice is:
- Inventory your LLM calls. Tag each one as generate or decide. The decide ones are candidates. In my experience that is most of them.
- Measure calibration on what you already have. Compute Brier and ECE for your current classifiers. If they are bad, you have a problem Jev might solve. If they are fine, you mostly have a latency and cost question.
- Do not skip the classical baseline. A gradient-boosted tree on decent features is the bar. Any new model has to beat it on your data, with your leakage rules, or it is not an upgrade.
- Treat “calibrated” as a hypothesis. Test it on your distribution before a business rule depends on it.
The idea behind System One models is sound: most of the decisions software needs from ML are small, structured, and latency-sensitive, and a chat model is a strange tool for them. Whether Jev delivers on the calibration promise is an empirical question. I have the dataset to answer it, and I intend to.
Further readingLink to section: Further reading
- Introducing System One Models & Jev, TypeSafe AI
- Building a harness with Jev, LangChain, for the request/response shape
- Predicting Pull Request Acceptance the Moment It’s Opened, my write-up of the COMPSAC paper this experiment builds on
- Guo et al., On Calibration of Modern Neural Networks, ICML 2017, the standard reference for ECE and temperature scaling
If you have Jev access and a labeled classification dataset with a known calibration problem, I would like to compare notes. My contact details are on the homepage.
-
TypeSafe AI, Introducing System One Models & Jev, September 2026. Latency, speedup, pricing, cardinality and modality limits are quoted from that post and are the vendor’s claims. ↩ ↩2 ↩3
-
LangChain, Building a harness with Jev, September 2026, which documents the state/questions request shape and the choice, score and noul question types. ↩
-
K. Pansuriya, E. Ghorbani, D. Singh, E. A. AlOmar. Predicting Acceptance and Review Effort in Human and Agent Pull Requests. IEEE COMPSAC 2026. arXiv:2607.12057. Table II reports RF F1 0.958 / AUC 0.676 and the majority baseline F1 0.957 / AUC 0.500. ↩
Hamburg, Germany
TERHECH.DE #web technologies #blender #ffmpeg
Quick note on how to create a transparent video that works in Safari and in Chrome using FFmpeg and Blender
● Feb 2, 2025 № 646 1 min read 291 words
I recently changed the style of this blog and included the video that you can see in the top right corner.
For posterity (should I change the design again), here it is:
The video contains an alpha channel and getting this to work in Safari (and non-Safari browsers) was a bit tricky so I’m keeping it here for future reference.
The video
The video is exported from Blender as a series of png frames with alpha channgel.
Lets say to /tmp/frames/%04d.png.
Chrome et al
Supporting Chrome and Firefox is easy, we can generate a webm video with alpha channel:
ffmpeg -i /tmp/frames/%04d.png -c:v libvpx-vp9 -b:v 0 -crf 25 -pix_fmt yuva420p webm.webmSafari
Safari does not support webm with alpha channels, so we have to do something different.
Thankfully, Apple added support for HEVC with alpha channels to Safari some time ago. So we can do that. Creating these is a bit more work. First, we need to create the image sequence to an Apple ProRes video.
ffmpeg -framerate 25 -i /tmp/frames/%04d.png -vf "scale=iw/2:ih/2" -c:v prores_ks -pix_fmt yuva444p10le -alpha_bits 16 -profile:v 4444 -f mov prores.mov(The -vf "scale=iw/2:ih/2" is optional and used to scale the video down 2x)
Next, we need to convert this to a HEVC video with alpha channel.
I was not able to do this with ffmpeg, but there’s a way to do this with the macOS Finder.
Right click the just-created prores.mov file in Finder and select Services -> Encode Selected Video Files.
A new dialog will appear
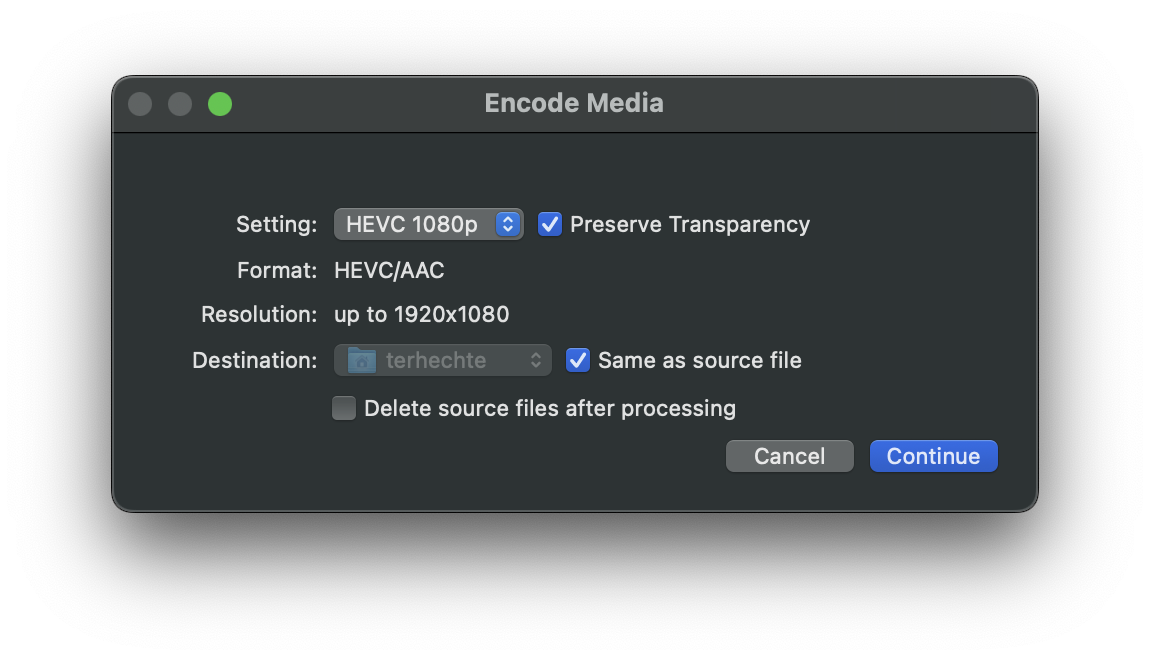
Select HEVC 1080p (or a higher resolution if needed), Preserve Transparency and then Continue.
HTML
Embedding the two videos in HTML is straightforward.
<video autoplay loop muted playsinline width="240" height="200">
  <source src="/img/ben-safari.mov" type="video/mp4;codecs=hvc1" />
  <source src="/img/ben-rest.webm" type="video/webm" />
</video>Hamburg, Germany




Hamburg, Germany
4 public comments

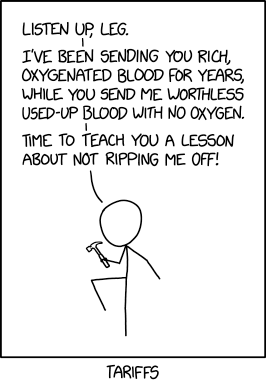
Finally we are able to close the political cartoon deficit that has been open since Smoot-Hawley.
Greenlawn, NY

Sigh...
New York, NY

More, please.
Lexington, KY; Naples, FL


"You legs may have a comparative advantage at running, but we arms have a competitive advantage at swinging hammers, so unless you accept that we're the dominant limbs and stop hogging the oxygen, that running advantage won't be around for long."
Next Page of Stories